
Last updated: September 8, 2026
Key Takeaways
- Multimodal AI in 2026 connects photo, video, and audio in single systems, producing context-aware, reference-conditioned output instead of isolated assets.
- Veo 3.1 leads on audio-visual sync, Seedance 2.5 on reference conditioning, Kling 3.0 on multi-shot storyboards, FLUX.2 and Ideogram 4.0 on image quality, and Sozee on creator-focused consistency across photo and video.
- Reference conditioning defines this generation of models, yet most treat references as per-generation inputs. Sozee instead locks likeness at the character level from as few as three photos.
- Creators who monetize content need locked identity, reusable assets, and built-in scheduling and analytics. Sozee is designed around those needs, while general-purpose models focus on raw generation.
- Get started free and lock your likeness in minutes.
The 2026 Multimodal AI Landscape At A Glance
OpenAI shut down the Sora consumer app on April 26, 2026, and its API is scheduled for discontinuation on September 24, 2026, which leaves a three-player top tier in AI video (Veo 3.1, Seedance, Kling), two specialized image models (FLUX.2, Ideogram), and a new category of reference-driven creator platforms anchored by Sozee. The table below maps the landscape at a glance, highlighting which models handle photo, video, or both, and where each excels. Every data point is cited in the model entries that follow. Sora 2 appears here only as a legacy reference point and is not part of the active ranking.
| Model | Photo Capabilities | Video Capabilities | Best For |
|---|---|---|---|
| Veo 3.1 | Image-to-video via Ingredients (up to 3 reference images) | 8-sec clips, native audio, 4K upscale, Scene Extension to 148s | Cinematic clips with synced audio |
| Sora 2 | Image-to-video, Cameos likeness feature | 1080p, native audio, physics-aware motion | Legacy projects only (being discontinued) |
| Seedance 2.5 | Up to 30 image references per request | 30-sec single-pass audio-video, 1080p | Long-form reference-heavy generation |
| Kling 3.0 | Image-to-video, Elements system | 15-sec clips, native 4K at 60fps, 5-language lip-sync | Multi-shot storyboards, talking heads |
| FLUX.2 | Text-to-image, photorealism | None | Bulk image generation |
| Ideogram 4.0 | Text-to-image, typography leader | None | Design and text-heavy image work |
| Sozee | Locked likeness, Photo Control (5 dimensions) | 15-sec 1080p, animate still, video-to-video, reel cloning | Consistent monetizable creator content |
#7: Ideogram 4.0 Typography Performance (Photo Only)
Ideogram 4.0, released in June 2026, is the top-ranked open-weights model on the Artificial Analysis Text-to-Image Leaderboard with an Elo score of 1017. Its defining strength is text rendering: Ideogram achieves approximately 90–95% text rendering accuracy on standard typography prompts, compared to Midjourney V7 at roughly 30–40%. Native transparent PNG exports at up to 8K resolution make it uniquely suited for print-on-demand designs, a capability no other major tool offers natively. Ideogram 3.0 is 2x faster on Default and 4x faster on Quality than GPT-4o’s image generation, at roughly one-third the cost, which keeps large batches affordable.
The tradeoffs are straightforward. Ideogram does not generate video or audio, and its photorealism still trails Midjourney V7 for natural human portraits. Ideogram fits print-on-demand, ad creatives, and any workflow where legible text inside an image is non-negotiable. It does not address video or cross-modal identity.
#6: FLUX.2 Photorealism For Bulk Images (Photo Only)
Black Forest Labs’ FLUX.2 [max] ranks #19 on the Artificial Analysis Text-to-Image Leaderboard with an Elo score of 1031. For developers, its appeal is economic. FLUX.2 uses pay-per-image pricing, with listed starting prices around $0.014 per image for Klein 4B, which keeps bulk generation economical at scale. FLUX.2 [klein] is open weight under Apache 2.0 for self-hosting, so teams can run high-volume automation pipelines on their own infrastructure.
The core limitation is structural. FLUX.2 has no native video capability and no built-in character consistency system, so every image is a fresh generation with no memory of the last. It sets the benchmark for high-volume, high-quality stills at low cost per image. It does not serve creators who need the same face across a content calendar.
#5: Sora 2 As A Legacy Cautionary Tale
Sora 2, OpenAI’s video model with native synced audio and physics-aware realism, launched on September 30, 2025. At launch it showed real strengths: in the EvalVid 2026 benchmark, Sora 2 scored 8.4/10 on audio-visual sync and 92% prompt adherence, and it delivered best-in-class physics-aware motion, especially in water and foam simulation.
The product still failed. Day-30 retention for standalone Sora users fell to single-digit percentages by February 2026, with fewer than 5% of users returning monthly. Copyright lawsuits from 17 major media companies pushed estimated liability above $2.3 billion. OpenAI shut down the Sora consumer app in April 2026 and scheduled API discontinuation for September 24, 2026. Sora now serves as a warning about legal risk and product fit rather than a viable choice.
#4: Kling 3.0 For Storyboards And Talking Heads
Kling 3.0, launched in Q1 2026 by Kuaishou, delivers native 4K at 60fps, clips up to 15 seconds, integrated native audio generation, and a multi-shot storyboard system supporting up to six camera cuts in a single generation. Kling 3.0 ranks around #4 on the Artificial Analysis text-to-video leaderboard as of June 2026. Its Elements system matters for continuity: Kling 3.0’s Elements system holds a character or object more consistently across multiple cuts than earlier Kling releases. For multilingual productions, Kling 3.0’s five-language lip-sync pipeline outperforms Veo 3.1.
The limitations show up under stress. Kling 3.0 can trade away prompt adherence under heavy motion and occasionally shows micro-detail glitches, such as fingers or fast-moving fluids, or character drift across regenerations. It shines for multi-shot narrative sequences and talking-head content with multilingual lip-sync. It still does not solve identity consistency at the platform level.
#3: Seedance 2.5 For Heavy Reference Conditioning
ByteDance’s Seedance 2.5, launched July 31, 2026, supports up to 30 image, 10 video, and 10 audio reference inputs per request, a specification no competitor has publicly matched at the same duration. Seedance 2.5 can generate a 30-second single-pass audio-video segment, a major jump from Seedance 2.0’s 12-second maximum. Seedance 2.0 leads public leaderboard-style evaluations for both text-to-video and image-to-video as of June 2026, and in VibeDex’s 10-model benchmark it earned the highest blended score of 4.70 out of 5 and a perfect character consistency score.
Access remains the main blocker. As of early August 2026, Seedance 2.5’s API endpoint on BytePlus ModelArk still shows “coming soon,” and no third-party gateway has a live endpoint. ByteDance also does not operate a standalone English consumer website for Seedance. For reference-heavy generation where you need to lock faces, locations, and motion across long clips, Seedance 2.5 is the strongest general-purpose option when you can reach it.
Try Sozee free and see your likeness locked in minutes.
#2: Veo 3.1 For Audio-Visual Precision
Veo 3.1, Google DeepMind’s flagship model released in October 2025 with a 4K upgrade in January 2026, generates synchronized audio in a single pass, with dialogue, ambient sound, and effects aligned to the visuals. In the EvalVid 2026 benchmark, Veo 3.1 scores 9.1 out of 10 on audio-visual sync, ahead of Sora 2 and Kling 3.0. Veo 3.1 ranks first on both MovieGenBench and VBench for image-to-video quality. Its Ingredients feature accepts up to three reference images for character consistency, and tail-frame extension chains iterative eight-second passes into sequences up to 148 seconds. Veo 3.1 Lite costs less than half of Veo 3.1 Fast while matching its speed.
The gaps matter for creator workflows. Veo 3.1’s character consistency scored 6 out of 10 in VibeDex’s benchmark, compared to Seedance 2.0’s perfect score. Text rendering inside video remains unreliable, and audio can become unstable for longer monologues. The eight-second base clip cap is also the shortest among the top models. Veo 3.1 is the clear choice when audio-visual sync and lip-sync precision sit at the top of your requirements. It is less suited to pipelines that depend on rock-solid character identity.
#1: Sozee As A Reference-Driven Creator Studio
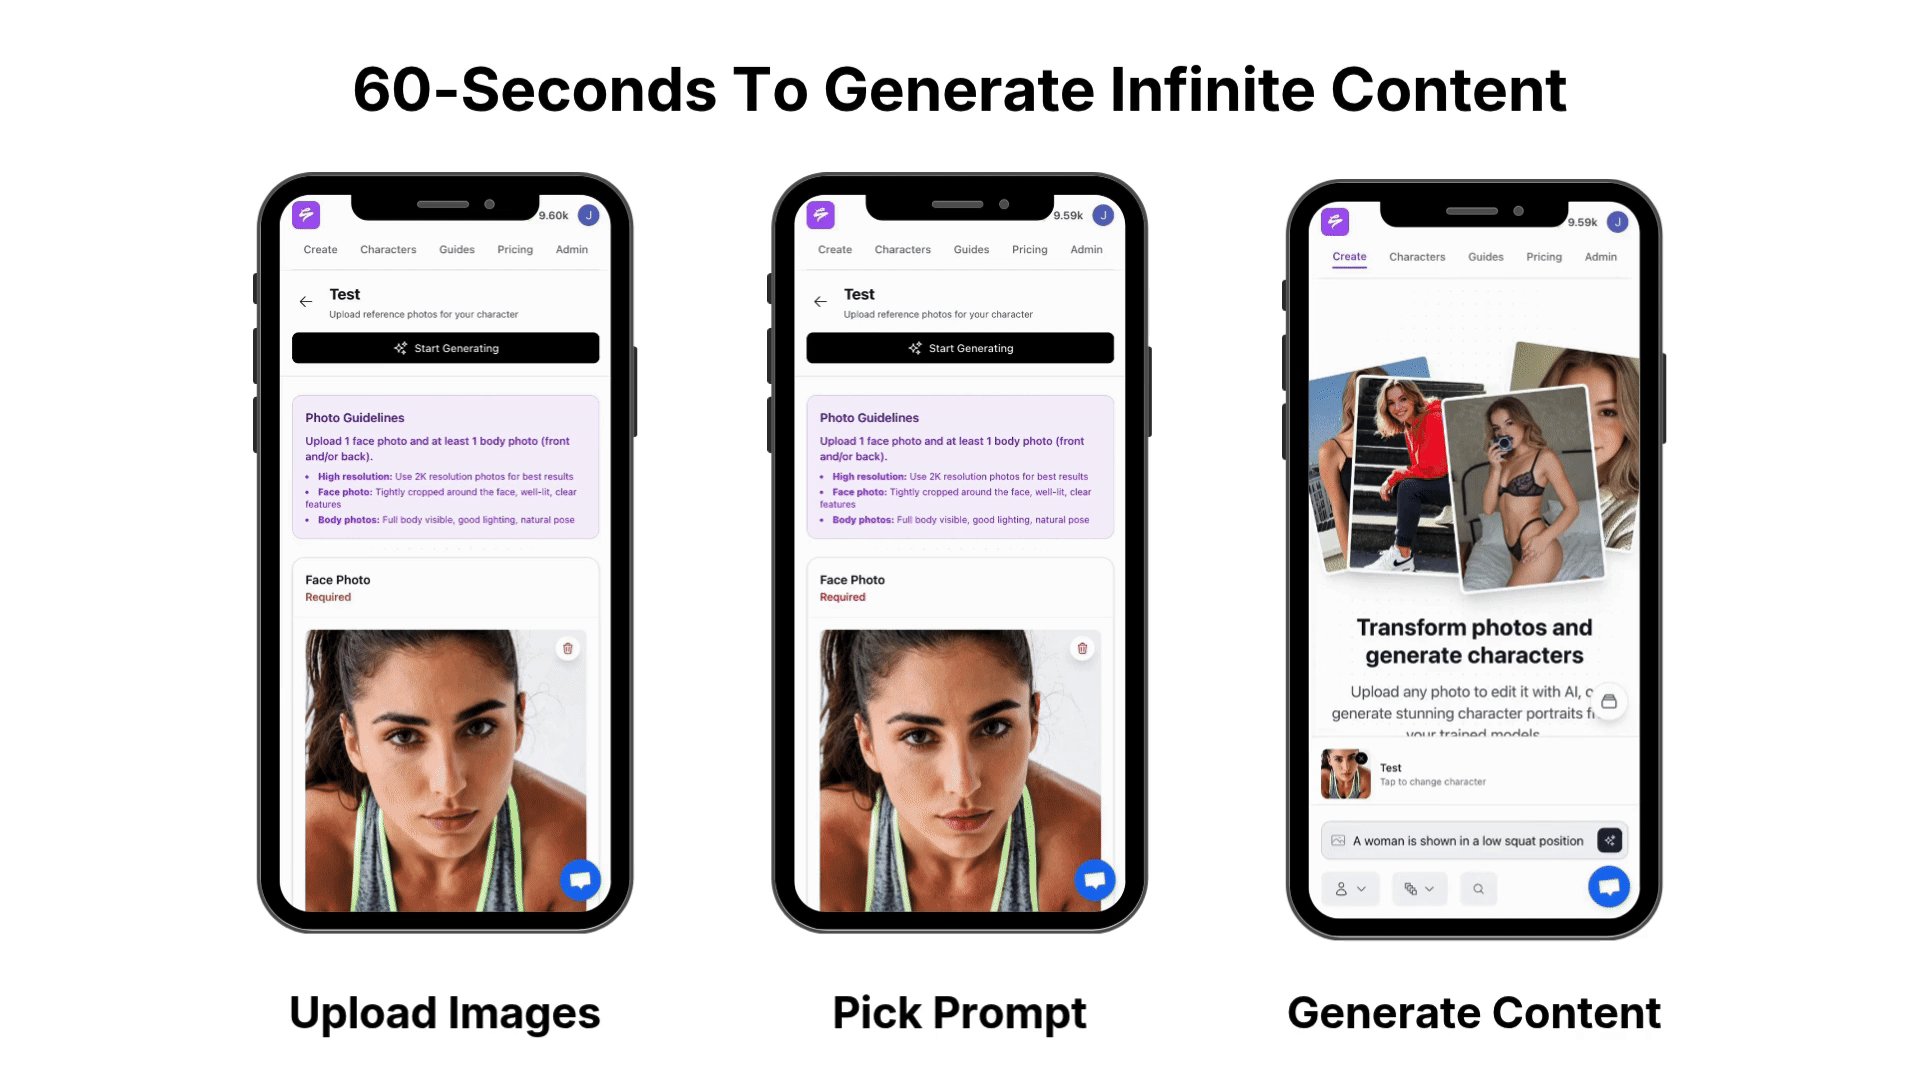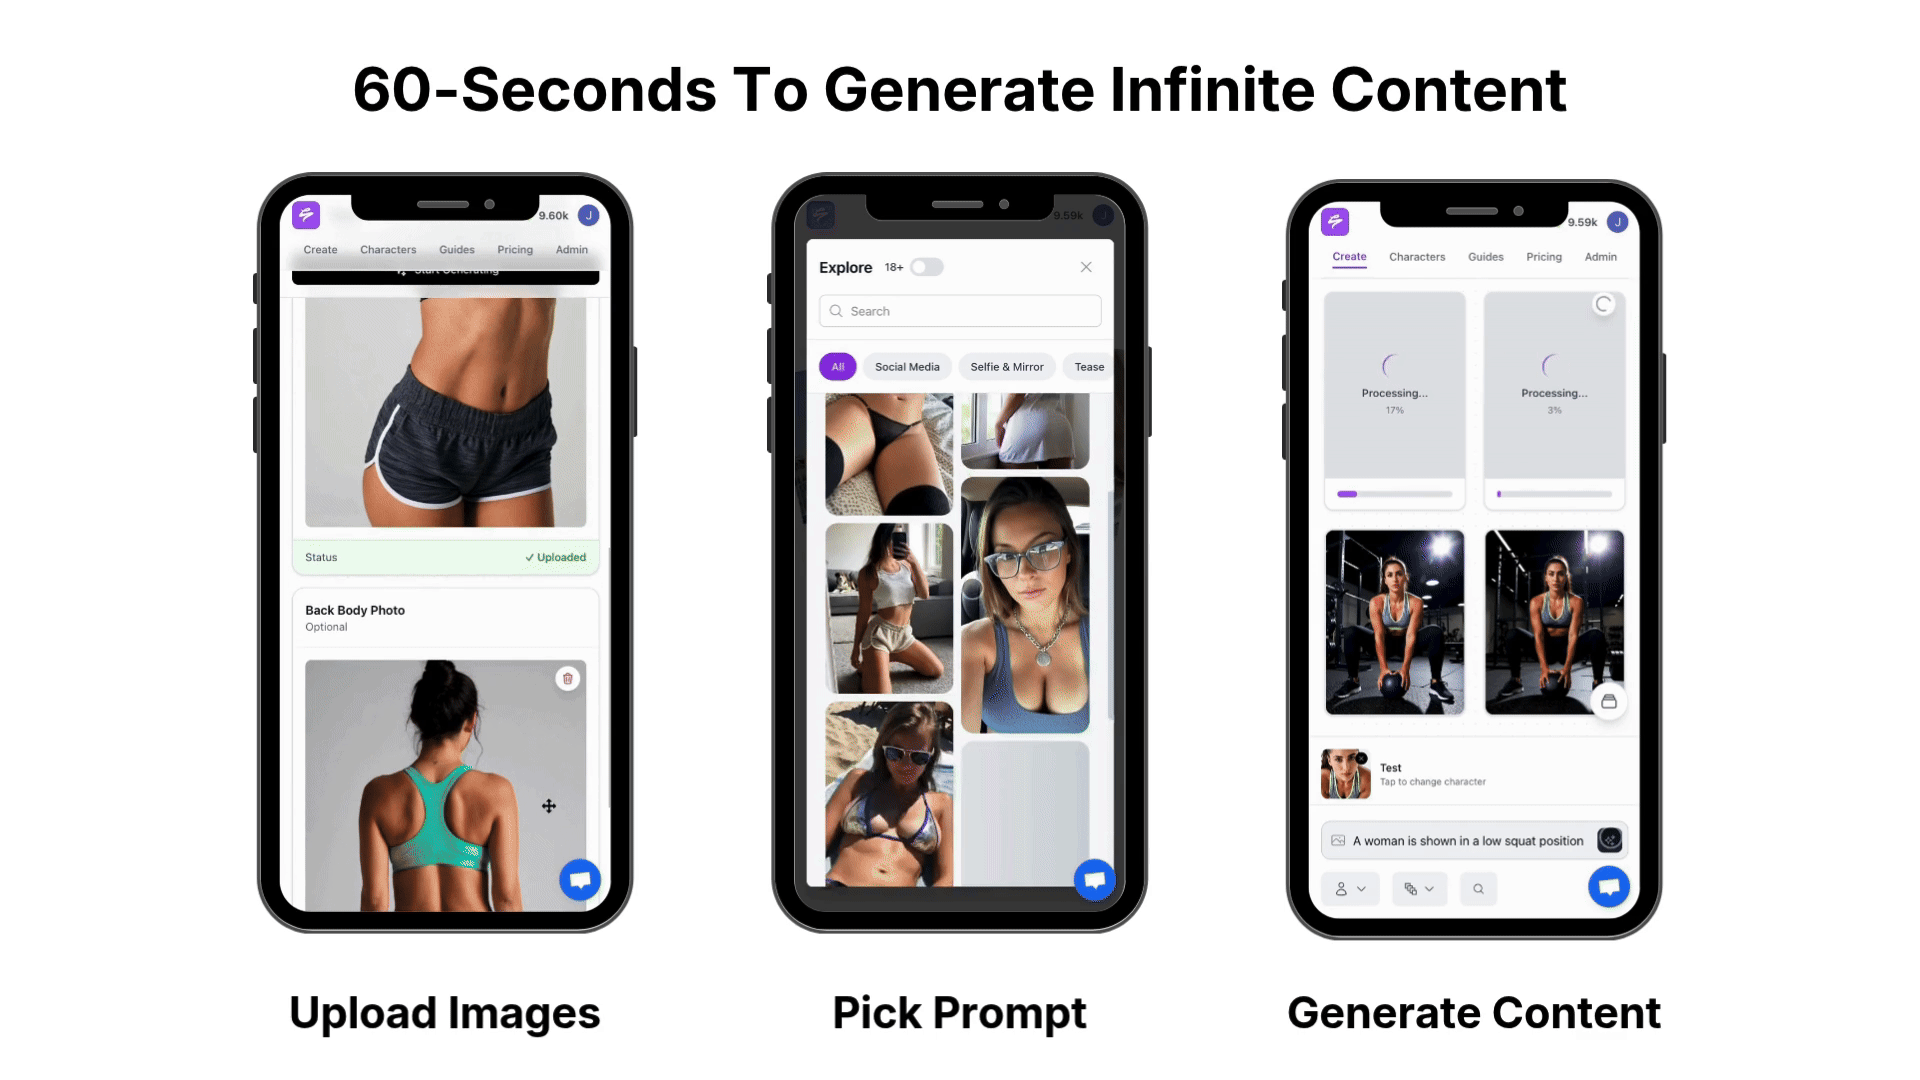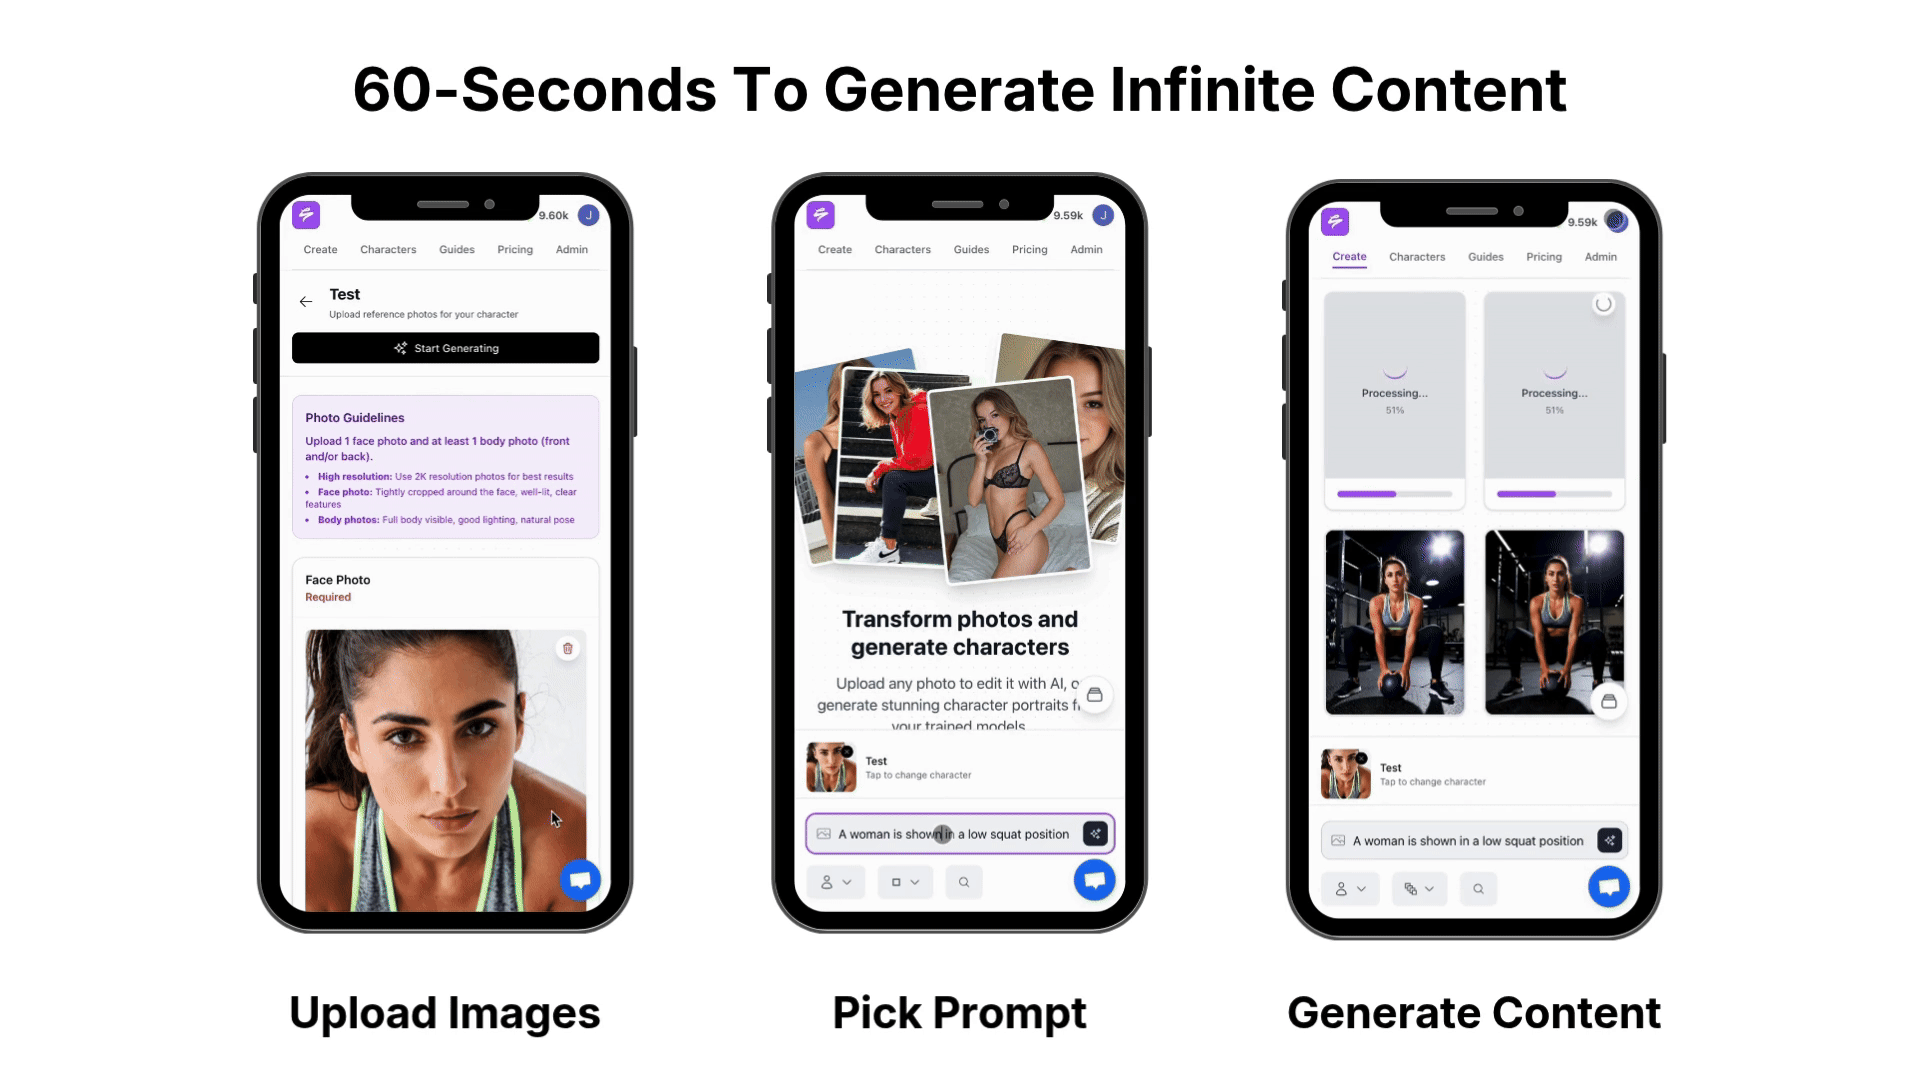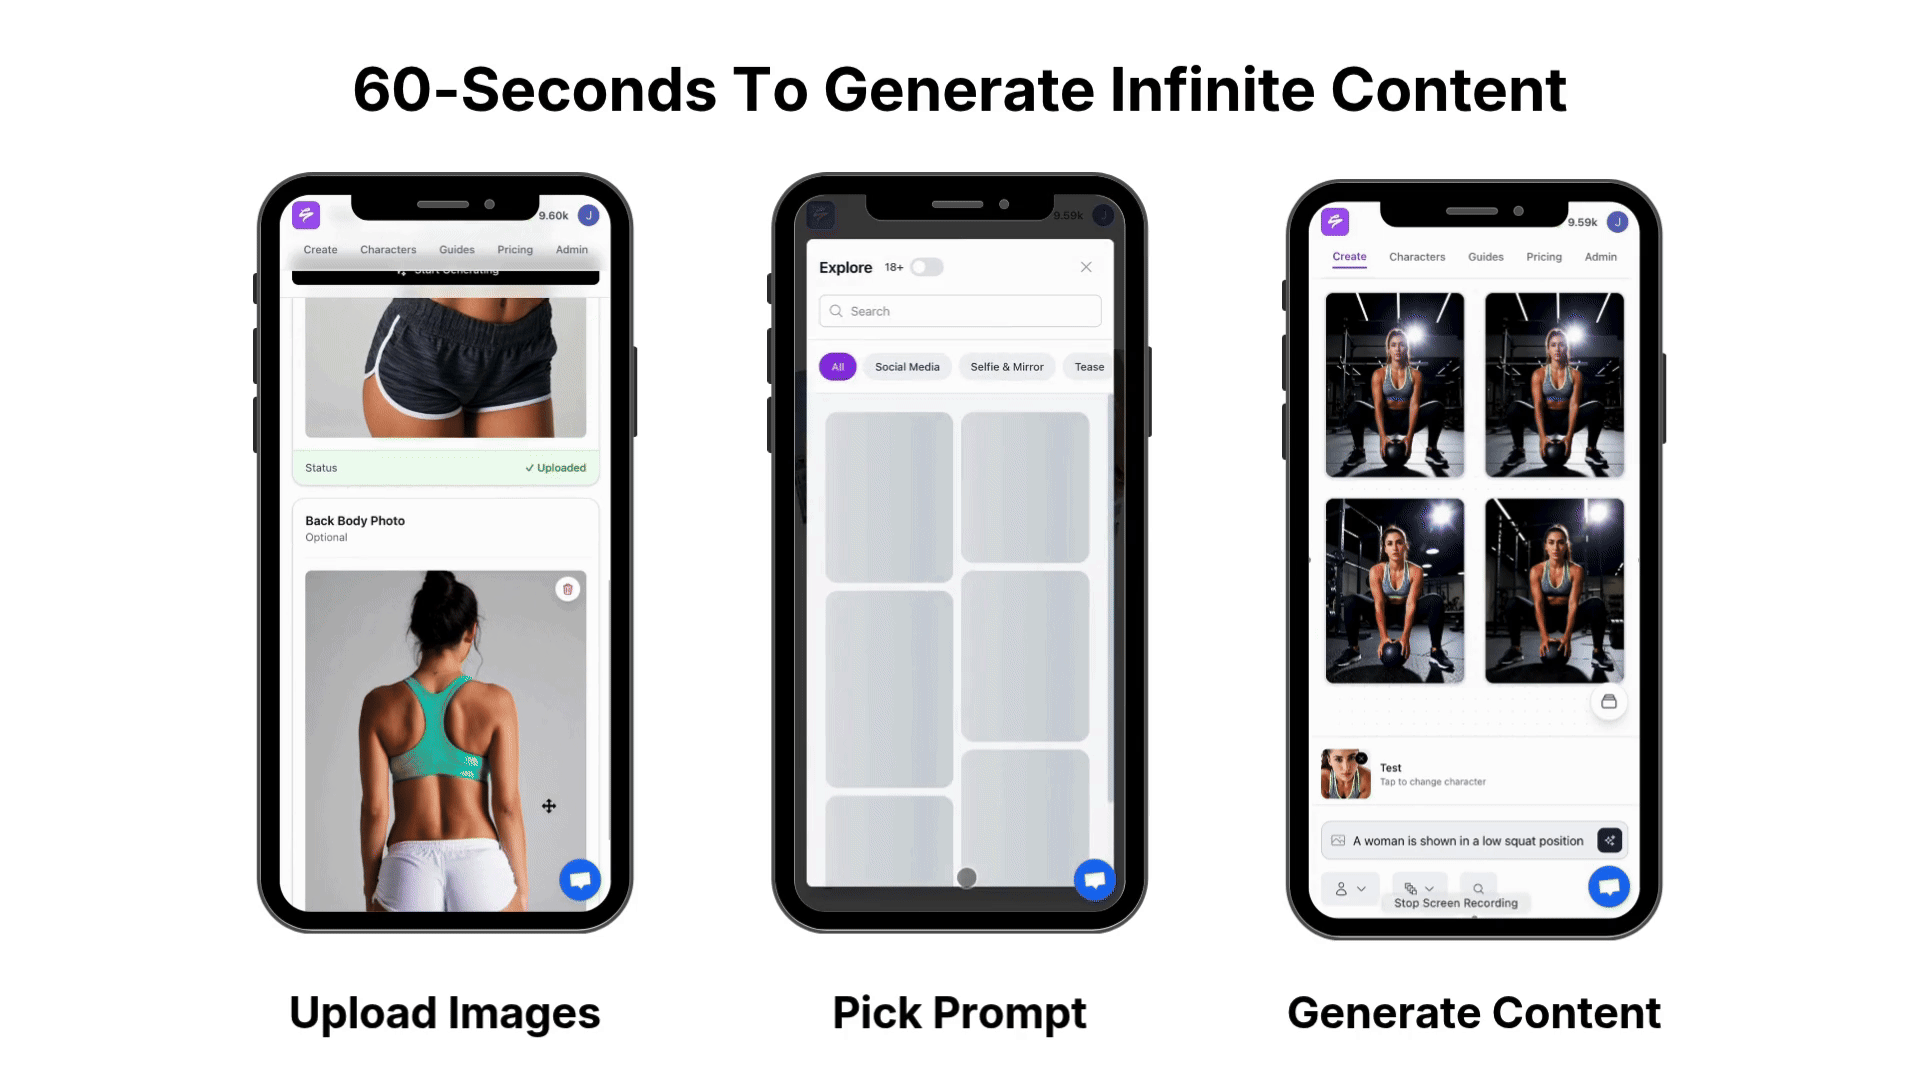
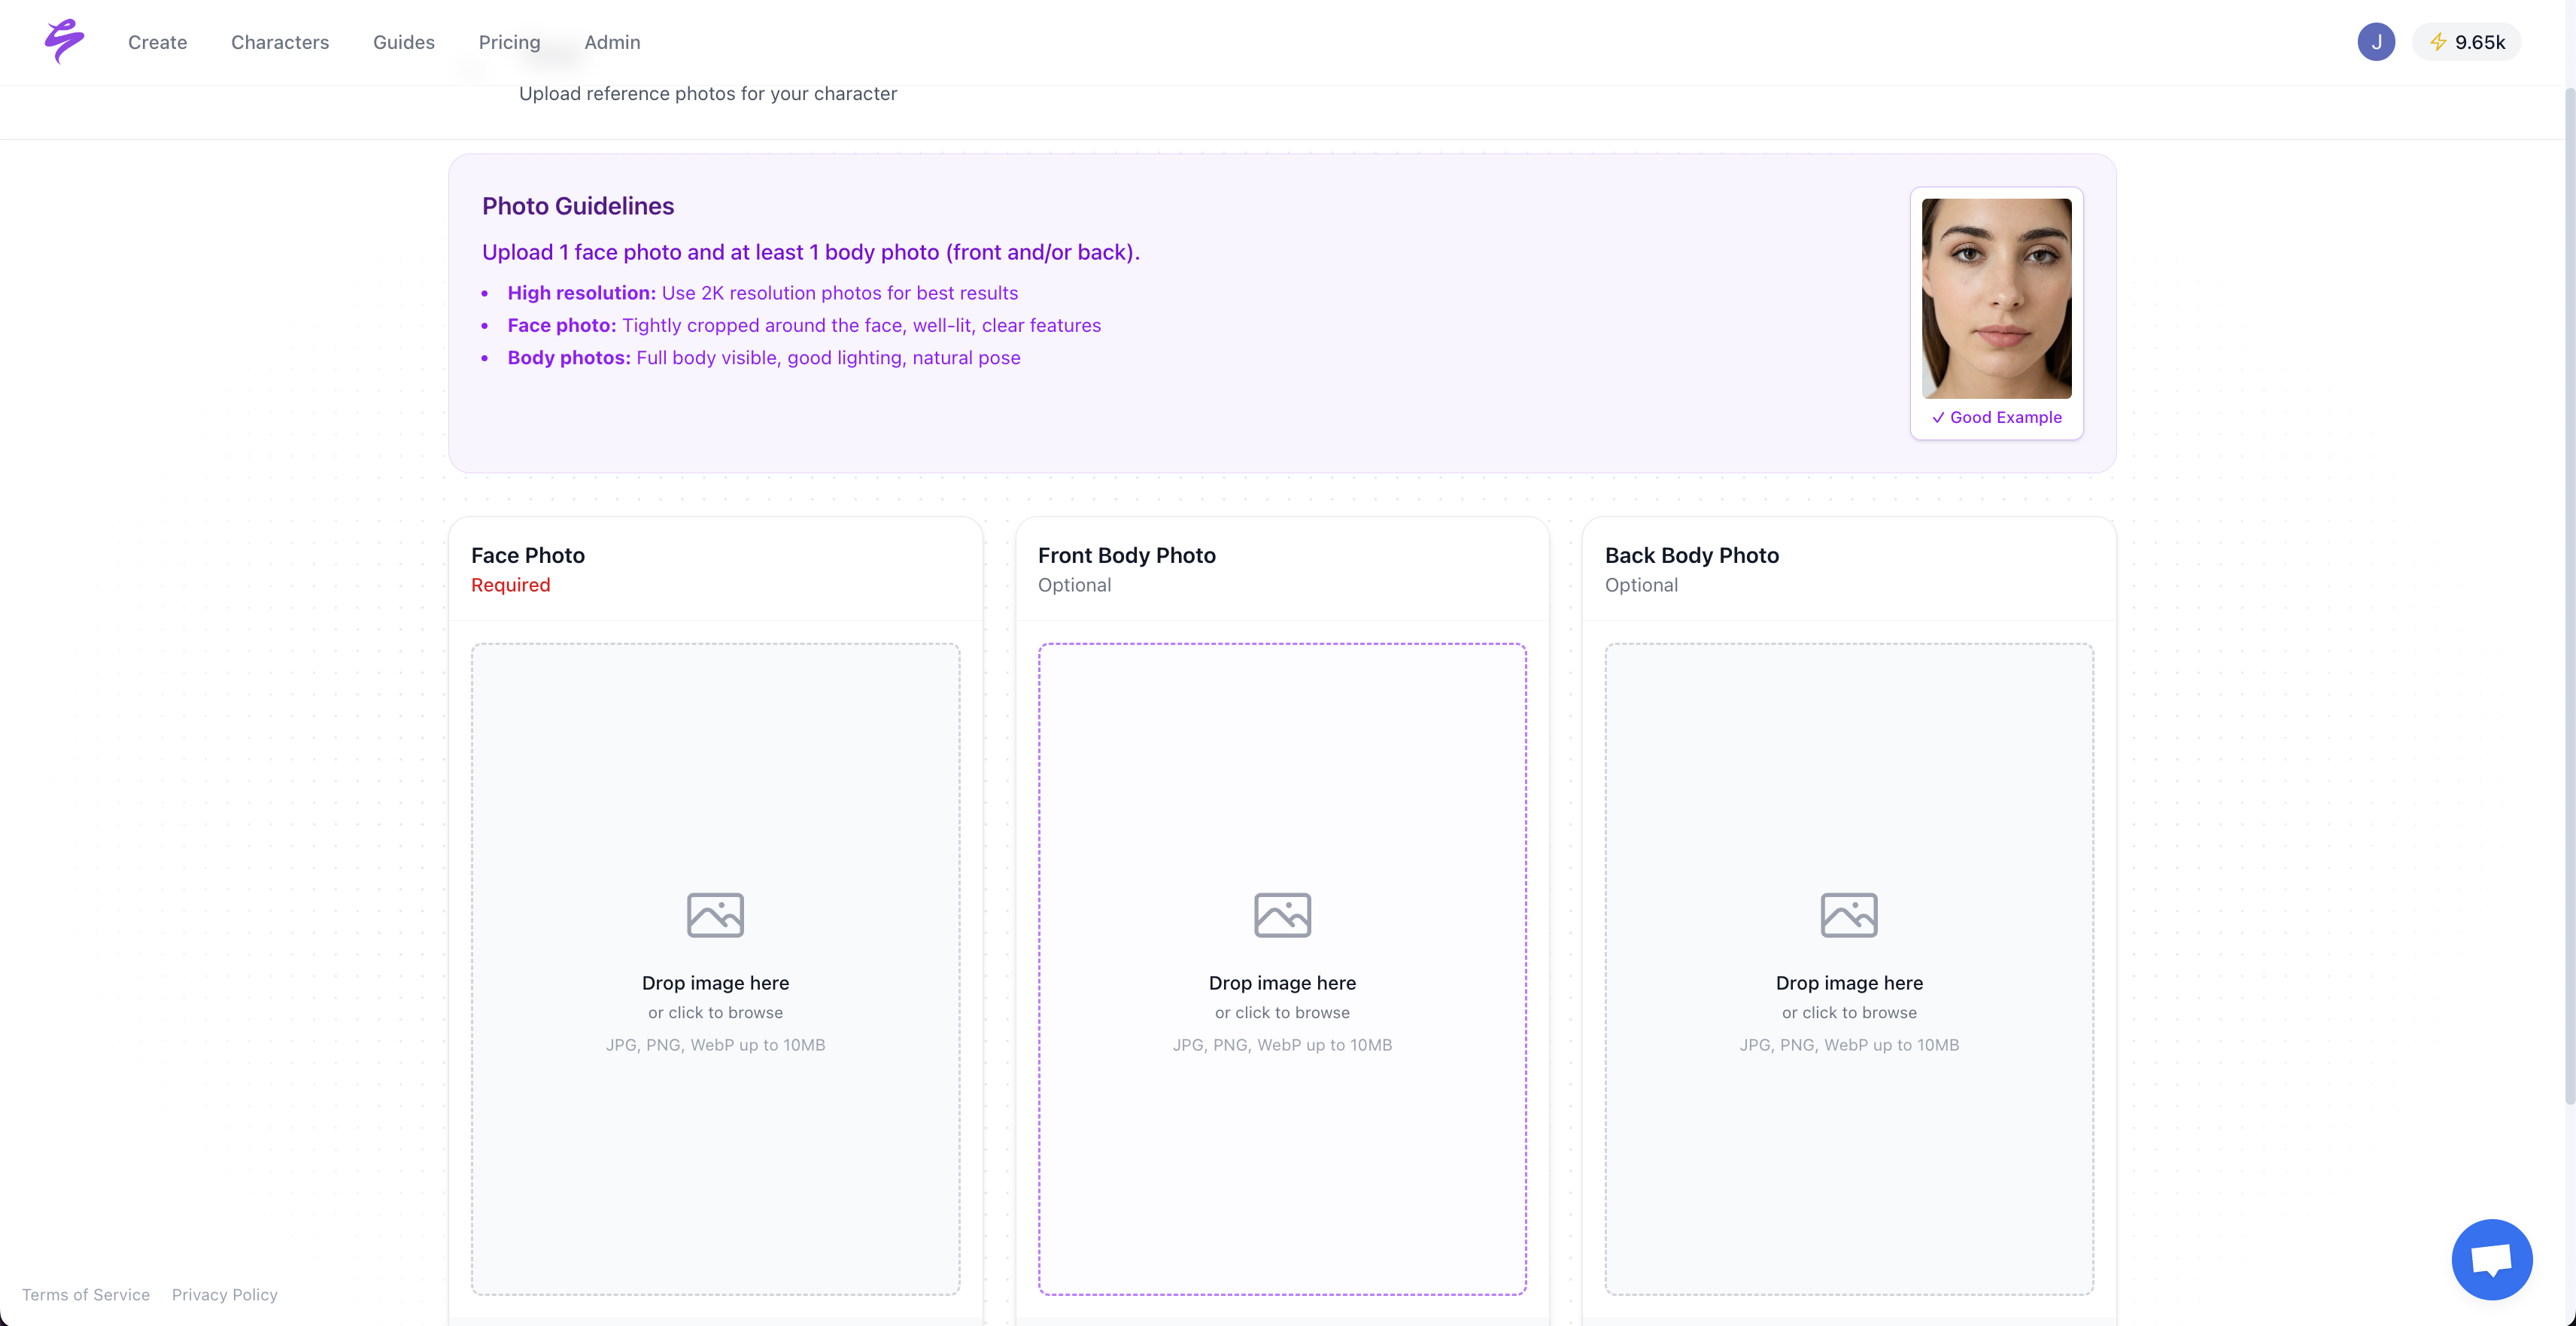
Sozee focuses on creators who monetize content and need a studio, not just a model. Upload as few as three photos and Sozee locks a hyper-realistic likeness, or generate an original character from scratch with no training or technical setup. The architecture locks likeness at the character level, so identity persists across every clip and frame.
Photo Control exposes five directable dimensions, including Setting, Outfit, Shot Style, Expression, and Object, so each shoot becomes a set of clear choices. Photo Shoot takes a single image and builds a coherent locked set of up to ten, with identity, outfit, and environment staying consistent while angle, pose, and expression vary. Video features include animate-a-still with directed motion, video-to-video cloning, and reel cloning from Instagram, TikTok, or YouTube links. Text-to-video generates clips up to 15 seconds at 1080p. Live Mode renders your character onto your camera feed in real time. The built-in Scheduler publishes across Instagram, TikTok, X, Facebook, Reddit, and Fanvue with per-platform captions, and Analytics separates Sozee-posted content from your manual posts so you can see the platform’s impact.
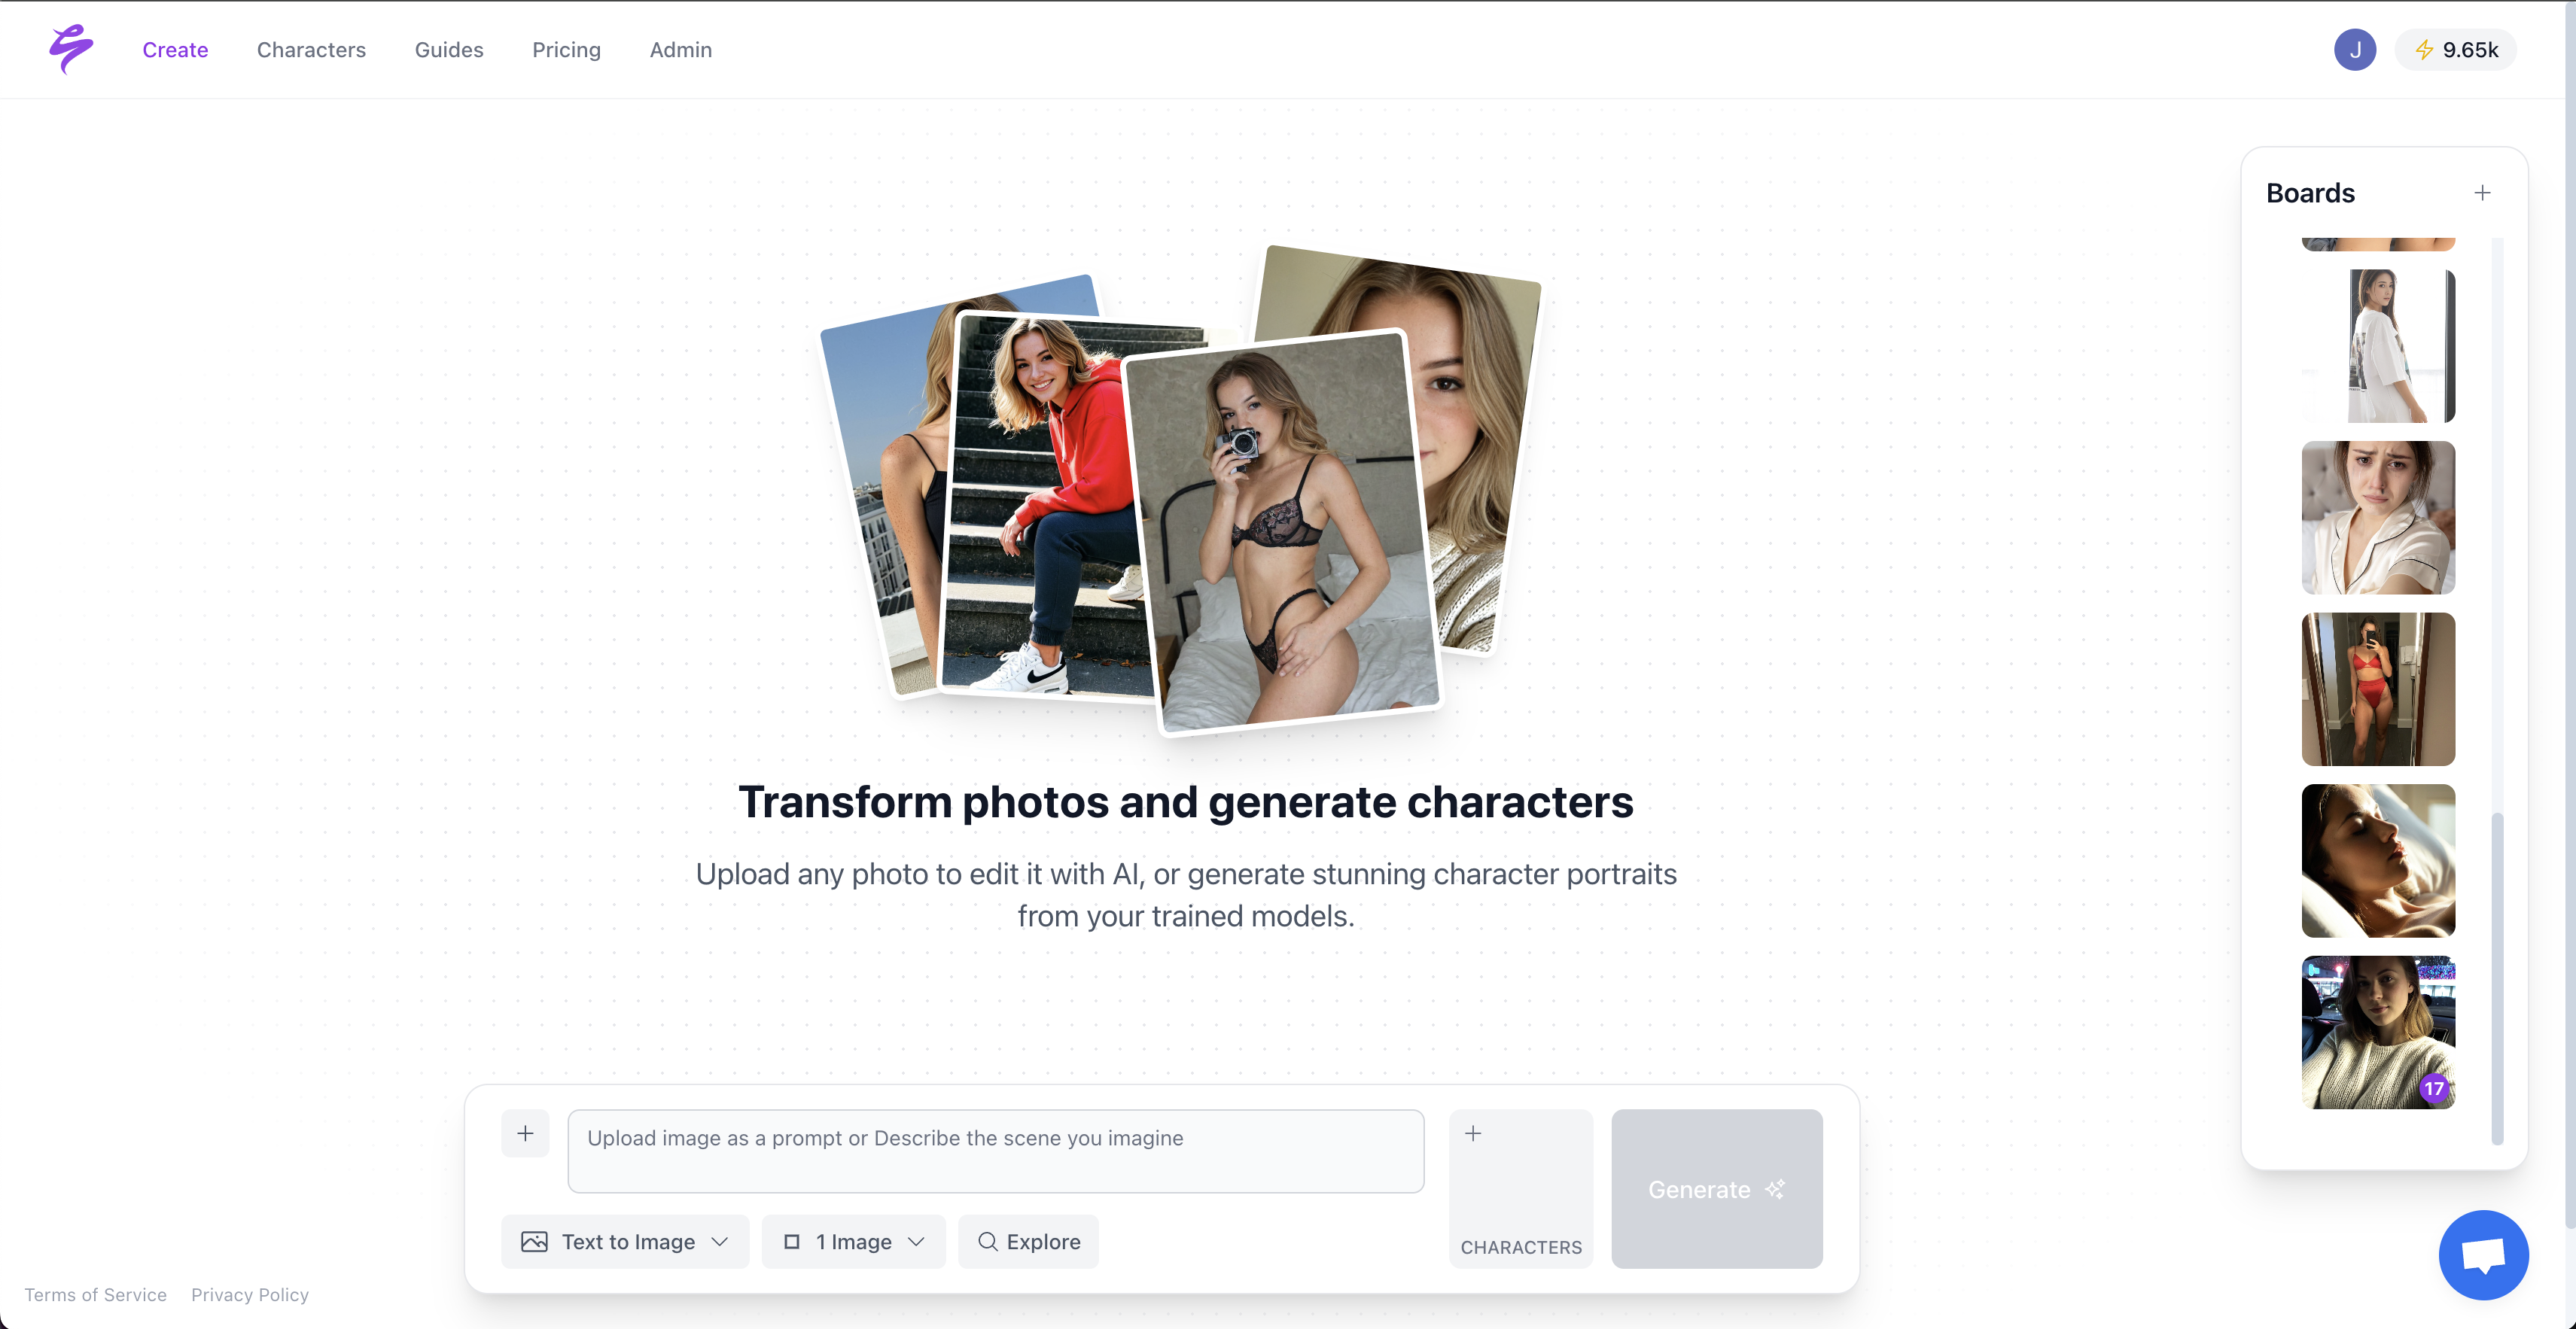
The @-reference system attaches saved elements such as environments, outfits, and objects inline without leaving the prompt. Settings become reusable environments built from up to four reference shots, so each new shoot builds on the last. This structure turns reference-driven generation into the foundation of the platform.
Sozee focuses on creator workflows rather than enterprise-scale API workloads or broad general-purpose generation. It serves creators, agencies, and virtual influencer builders who need consistent, monetizable content across both photo and video.
Start creating now and see your locked likeness in action.
Photo Generation Capabilities Compared
Photo generation quality looks strong across the leading image models, but control and consistency separate them. On the Artificial Analysis Text-to-Image Leaderboard, FLUX.2 [max] ranks #19 with an Elo score of 1031, and Ideogram 4.0 ranks as the top open-weights model with an Elo score of 1017, yet neither model generates video. For creators, consistency across shoots matters more than a single standout frame. Sozee’s Photo Control dimensions turn each shoot into a repeatable setup instead of a prompt gamble.
Ideogram runs roughly twice as fast as GPT-4o’s image generation at about one-third of the cost, and FLUX.2 Klein starts around $0.014 per image, which suits volume workflows. Sozee outputs up to 4K and builds reusable environments, outfits, and objects that gain value with every new shoot.
Video Generation Capabilities Compared
Video generation in 2026 splits across three strengths: sync, references, and storyboards. Veo 3.1 holds the highest published audio-visual sync score in the EvalVid 2026 benchmark. Seedance 2.5 offers industry-leading reference input capacity per request. Kling 3.0 supports up to six camera cuts in a single multi-shot storyboard generation.
Clip length and audio support also differ. Seedance 2.5 generates 30-second single-pass clips. Kling 3.0 delivers 15 seconds at native 4K. Veo 3.1 caps at eight seconds per clip, extendable to 148 seconds through Scene Extension. Sozee generates up to 15 seconds at 1080p across the main social aspect ratios. Veo 3.1 and Seedance 2.5 both generate synchronized audio natively, and Kling 3.0 supports native dialogue in five languages. Sozee adds voice cloning and Voice Notes for fan engagement. Its video tools, including animate-a-still, video-to-video cloning, and reel cloning from platform links, all inherit the same locked character identity as photo generations.
Which AI Works Best For Image And Video Together?
Different models lead different categories. FLUX.2 and Ideogram 4.0 lead image quality benchmarks, yet they do not generate video. For video, Veo 3.1 leads on audio-visual precision, Seedance 2.0 leads on reference conditioning and character consistency, and Kling 3.0 leads on multi-shot storyboards. Sozee is the only platform in this comparison that generates both photos and video with a locked character identity and directable controls.
Which AI Model Handles Image To Video Best?
Veo 3.1’s Ingredients feature accepts up to three reference images, and Seedance 2.5 supports 30-image reference input, which makes them the strongest general-purpose options for image-to-video. Both can still drift across longer sequences and extreme camera moves. Sozee takes a different approach by locking likeness at the character level. Animate-a-still uses that persistent identity, which makes Sozee a reliable choice for creators who need brand-consistent video from still images.
Use-Case Recommendations For Creators
The right model depends on the job you need to ship.
- Best For Cinematic Clips With Audio Sync: Veo 3.1, with a leading EvalVid audio-visual sync score, native 4K, and Scene Extension for narrative sequences. Seedance 2.5 follows for longer single-pass clips.
- Best For Talking-Head Avatars: Kling 3.0, with five-language lip-sync and the Elements system for character continuity. Sozee’s voice cloning and Live Mode suit creators who want real-time performance capture.
- Best For Bulk Image Generation: FLUX.2 Klein at roughly $0.014 per image for high-volume drafts, and Ideogram 4.0 for text-heavy design work. Sozee fits bulk consistent images, since Photo Shoot generates up to ten locked images from one frame.
- Best For Consistent Character Content: Sozee, with locked likeness across photo and video, reusable environments, outfits, and objects, Photo Control dimensions, and an Agent that sets up shoots from a conversation.
The Shift To Reference-Driven Generation
Reference conditioning now anchors high-end multimodal workflows. Veo 3.1’s Ingredients feature accepts up to three reference images. Seedance 2.5 offers one of the highest published reference input capacities per request. Kling 3.0’s Elements system improves character consistency across cuts compared to prior releases. In each case, references still operate on a per-generation basis, so every new generation requires re-uploading assets and trusting the model to hold them.
Sozee treats reference-driven generation as the core of the platform. Likeness locks at the character level from as few as three photos or from a generated base. Every photo and video inherits that identity. Settings act as reusable environments built from up to four reference shots. Outfits live as saved options instead of repeated prompt text. Objects steer scenes. The @-reference system attaches any element inline. This structure places Sozee in a different category from general-purpose models.
How To Choose The Right Model For Your Workflow
Use a simple decision framework and match each project to a model.
- Need cinematic clips with precise audio sync? Choose Veo 3.1.
- Need long-form, reference-heavy generation? Choose Seedance 2.5.
- Need multi-shot storyboards with multilingual lip-sync? Choose Kling 3.0.
- Need bulk stills at the lowest cost per image? Choose FLUX.2.
- Need legible text rendered inside images? Choose Ideogram 4.0.
- Need consistent, monetizable content across photo and video with scheduling, analytics, and publishing built in? Choose Sozee.
General-purpose models focus on content generation. Sozee focuses on running a creator business with locked likeness, reusable assets, and a workflow that compounds over time.
Frequently Asked Questions
How Do I Pick One AI For Both Images And Video?
No single general-purpose model dominates both images and video. FLUX.2 and Ideogram 4.0 lead image benchmarks but do not handle video. Veo 3.1, Seedance 2.5, and Kling 3.0 lead video benchmarks but treat images as temporary inputs. Sozee is the only platform here that delivers both photos and video with a persistent locked character, which makes it a strong fit for creators who want one workflow.
Which AI Model Works Best For Image-To-Video Workflows?
Veo 3.1, with up to three reference images via Ingredients, and Seedance 2.5, with high-capacity image references, stand out for general-purpose image-to-video. For creators who need brand-consistent video from still images, Sozee’s animate-a-still feature uses the character’s locked likeness, which removes the drift that appears in per-clip reference systems.
What Happened To Sora In 2026?
The Sora shutdown mentioned earlier resulted from a mix of legal pressure, low retention, and product strategy. Copyright lawsuits from 17 major media companies, estimated liability above $2.3 billion, and day-30 retention below 5% all contributed. Veo 3.1, Seedance, and Kling now fill the gap Sora left.
What Does Reference-Driven AI Generation Mean?
Reference-driven generation uses uploaded images, audio, or video clips to guide output so character identity, environment, or style stays consistent. In 2026, Veo 3.1, Seedance 2.5, and Kling 3.0 all support reference inputs per generation. Sozee instead locks likeness permanently at the character level from a small set of photos, so every photo and video inherits that identity without repeated uploads.
Can Current AI Video Models Generate Audio?
Yes, the leading 2026 video models generate synchronized audio. Veo 3.1 produces dialogue, ambient sound, and sound effects in a single pass and holds the top published audio-visual sync score. Seedance 2.5 generates 30-second single-pass audio-video segments. Kling 3.0 supports native dialogue in five languages. Sozee adds voice cloning and Voice Notes, so a character can speak in her cloned voice for fan engagement without new recordings.
The 2026 Verdict For Creators
The multimodal AI landscape in 2026 looks mature yet fragmented. Photo specialists like FLUX.2 and Ideogram 4.0 ignore video. Video specialists like Veo 3.1, Seedance 2.5, and Kling 3.0 still do not lock identity across a content pipeline. Sora has exited the market. These models act as powerful tools for individual assets rather than full creator businesses.
Sozee stands out as a platform built around monetized creator workflows. Locked likeness, directable Photo Control, reusable assets, photo and video generation, Live Mode, scheduling, and analytics all live in one studio. You move from gambling on prompts to directing shoots.
Go viral today and build your locked likeness from three photos.