
Last updated: September 24, 2026
Key Takeaways
- Deepfacelab is the dominant open-source face-swapping tool, powering the large majority of deepfake videos worldwide through a six-stage pipeline of extraction, detection, training, reconstruction, merging, and rendering.
- Training demands significant hardware, including an Nvidia GPU with 6–24+ GB VRAM, 12–20 hours for basic results and up to a week for cinema-quality output, plus curation of at least 2,000 varied source images.
- Common failure modes include flicker, warping, color mismatch, and visible seams that require manual tuning and can degrade final video quality.
- Deepfacelab carries serious legal, security, and reputational risks for creators and subjects, with non-consensual imagery, election interference, and corporate fraud among documented harms, plus new EU and U.S. regulations effective 2026.
- Sozee offers a consent-first, hardware-free alternative that produces consistent, high-quality face-swap results from just three photos without training, VRAM limits, or untrusted downloads.
Create A Consent-First Face Swap From Three Photos
What Is Deepfacelab And Who Uses It
Deepfacelab was released in 2018 under the GPL-3.0 license and developed by Iperov, with an active community maintaining it since. The framework is estimated to power more than 95% of all deepfake videos created worldwide, a figure that reflects its high quality ceiling among open-source alternatives.
Its user base spans four broad groups:
- VFX hobbyists and independent filmmakers seeking cinema-quality face replacement
- Academic researchers studying deepfake generation and detection
- Content creators experimenting with synthetic media
- Bad actors who exploit the tool for fraud, harassment, and non-consensual imagery
Deepfacelab is primarily designed for Windows 10 or later, with Linux as a secondary platform. It does not support real-time processing and relies on a batch-file workflow rather than a modern GUI, although community-built interfaces layer on top of the core scripts.
How Deepfacelab’s Six-Stage Pipeline Works
The pipeline follows six discrete stages. The source dataset is the face being transplanted, often called Person A. The destination dataset is the footage being manipulated, often called Person B.
- Frame Extraction. The destination video is split into individual image frames using FFMPEG. Source footage for Person A is handled the same way, which produces two large image sequences ready for face detection.
- Face Detection And Alignment. Deepfacelab uses the S3FD detector to locate faces and the FAN landmark network to extract 68 facial landmarks. It then applies the Umeyama algorithm to align each crop to a standard template. The result is a faceset of consistently posed, square-cropped face images for both identities.
- Autoencoder Training. An autoencoder is a neural network that compresses an image into a compact numerical code and then reconstructs it. Deepfacelab uses a shared encoder trained on both facesets simultaneously, while two separate decoders each learn to reconstruct one identity. The shared encoder learns a representation that captures pose and expression rather than identity, so the same code can be decoded through either person’s decoder.
- Face Reconstruction. After training, a frame of Person B is fed through the shared encoder. The resulting code is passed through Person A’s decoder, which produces Person A’s face carrying Person B’s expression, head angle, and lighting.
- Masking And Merging. The generated face is composited back into the destination frame. Deepfacelab’s merger applies color transfer to match skin tone and uses Poisson blending or alpha-feathering to hide the seam at the face boundary.
- Final Render. Processed frames are reassembled into a video file with the original audio track restored via FFMPEG. This step produces the finished output.
Skip The Six-Stage Pipeline — Try Sozee Free
What Deepfacelab Actually Costs In Hardware, Time, And Data
Deepfacelab system requirements act as a hard constraint rather than a suggestion. Training requires an Nvidia GPU with CUDA support. Its 6–24+ GB of VRAM determines the achievable model resolution and training speed, and RTX-series cards are described as ideal. A 16+ GB system RAM baseline and 50+ GB of free disk space are practical minimums. A 12 GB VRAM card is the entry-level comfort line for training a decent model, while 8 GB cards can still run Deepfacelab but require lowering resolution and batch size, which lengthens the training cycle.
Training duration scales with dataset size, resolution, and GPU. On an RTX 3060, basic facial structure emerges after roughly 100,000–150,000 iterations, or about 12–20 hours. Usable output takes 300,000–500,000 iterations, or about 2–4 days, and high-quality results require 800,000+ iterations, which often means a week or more.
Dataset quality matters more than raw training duration. Practitioners attribute roughly 99% of poor results to source dataset problems and recommend at least 2,000 source face images with varied angles and lighting similar to the destination footage.
Those hardware, time, and data costs also show up as quality failures. Four failure modes appear consistently across practitioner accounts:
- Flicker. Frame-to-frame alignment instability under fast motion or occlusion causes the swapped face to shimmer or jump between frames.
- Warping. When the training distribution diverges from the target footage, such as when the source dataset lacks certain head angles, the model cannot reconstruct those angles cleanly and produces geometric distortion.
- Color Mismatch. No single color transfer method reliably eliminates tone mismatch across all footage, so compositing must be manually tuned for each clip.
- Visible Seams. Imperfect blending masks leave color discontinuities, sharpness mismatches, and halo effects at the face perimeter.
Who Bears The Risks Of Deepfacelab Deepfakes
The risks of Deepfacelab deepfakes become clearer when you look at who bears the harm. The people who control the tool often differ from the people who suffer its consequences.
The Subject. Non-consensual intimate imagery is the most documented harm. The Australian eSafety Commissioner reports that deepfakes have been used to create fake pornographic videos targeting politicians and celebrities, and that targets experience financial loss, damage to professional or social standing, fear, humiliation, and loss of self-esteem. The U.S. Government Accountability Office has documented deepfake threats to individuals in its reporting on synthetic media, and the harm extends to reputation damage and sustained harassment campaigns.
The Viewer. Deepfakes erode trust in video evidence at scale. Chesney and Citron introduced the “liar’s dividend” concept in the California Law Review. Deepfakes make it easier for liars to avoid accountability for things that are in fact true, because any authentic video can now be plausibly dismissed as fabricated. A 2026 Harvard Kennedy School Misinformation Review expert survey rated deepfake video the highest-threat AI disinformation modality at a mean of 6.19 on a 7-point scale, with election interference identified as the most urgent risk by 78% of respondents.
The Organization. Corporate fraud now uses deepfakes as a growing vector. In February 2024, a deepfake attack on engineering firm Arup Group caused a $25.6 million loss when an attacker used AI-generated avatars of the company’s CEO and other staff during a video conference to authorize fraudulent transfers. KYC bypass and social engineering via CEO impersonation represent the same threat applied to financial institutions at scale.
The Creator. The person who runs the Deepfacelab pipeline faces legal exposure, platform bans, and reputational fallout, even when the intent was experimental rather than malicious. Platform terms of service add a layer of risk that operates independently of criminal law.
Is Deepfacelab Legal In 2026
Legality depends on content, consent, purpose, and jurisdiction. The same output can be lawful in one context and criminal in another.
In the European Union, Article 50 of the EU AI Act imposes transparency and labeling obligations on deepfake content, enforceable from 2 August 2026, with fines up to €15 million or 3% of worldwide annual turnover, whichever is higher. The obligations apply extraterritorially. The trigger is the location of use rather than the location of the organization, so U.S.-based creators whose content reaches EU users fall within scope.
In the United States, at least 45 states have enacted some form of deepfake law covering sexual deepfakes, election deepfakes, or AI voice cloning. At the federal level, the Take It Down Act (Public Law 119-12, signed May 19, 2025) makes it a federal crime to knowingly publish nonconsensual intimate visual depictions of adults or minors, expressly including AI-generated “digital forgeries,” with penalties reaching two years in prison for adult victims and three years when minors are depicted.
Platform terms of service add a further layer. A deepfake that is technically legal under applicable law may still result in account termination, content removal, and permanent bans from major distribution platforms. Legal exposure is not the only risk that comes with the tool itself. The way Deepfacelab is distributed introduces a separate security problem.
Supply-Chain And Maintenance Risk
Beyond the legal and reputational exposure, Deepfacelab’s open-source distribution model creates a security risk that most tutorials ignore, and it compounds every other cost in the pipeline. Community integration packages are frequently flagged by antivirus software, and some tutorials instruct users to disable Windows Defender or uninstall antivirus software entirely, which carries real risk because the contents of bundled packages from unknown sources cannot be verified.
The project has circulated through multiple forks and mirrors since its original release. The original author Iperov has not made substantive updates to the official repository for years, so users now rely on community-maintained forks. A community-developed PyTorch port appeared in April 2026, but the provenance of any given download, including pretrained models, cannot be assumed to be clean. Users should verify checksums against known-good sources before running any downloaded package.
Legitimate Uses And A Safer Alternative
Deepfacelab has documented legitimate applications such as VFX production, academic research into deepfake detection, clearly labeled parody, and consent-based face swapping where all parties have explicitly agreed. The original Perov et al. paper frames the framework partly as a tool for advancing deepfake defense research, arguing that generation methods are necessary for detection research to progress.
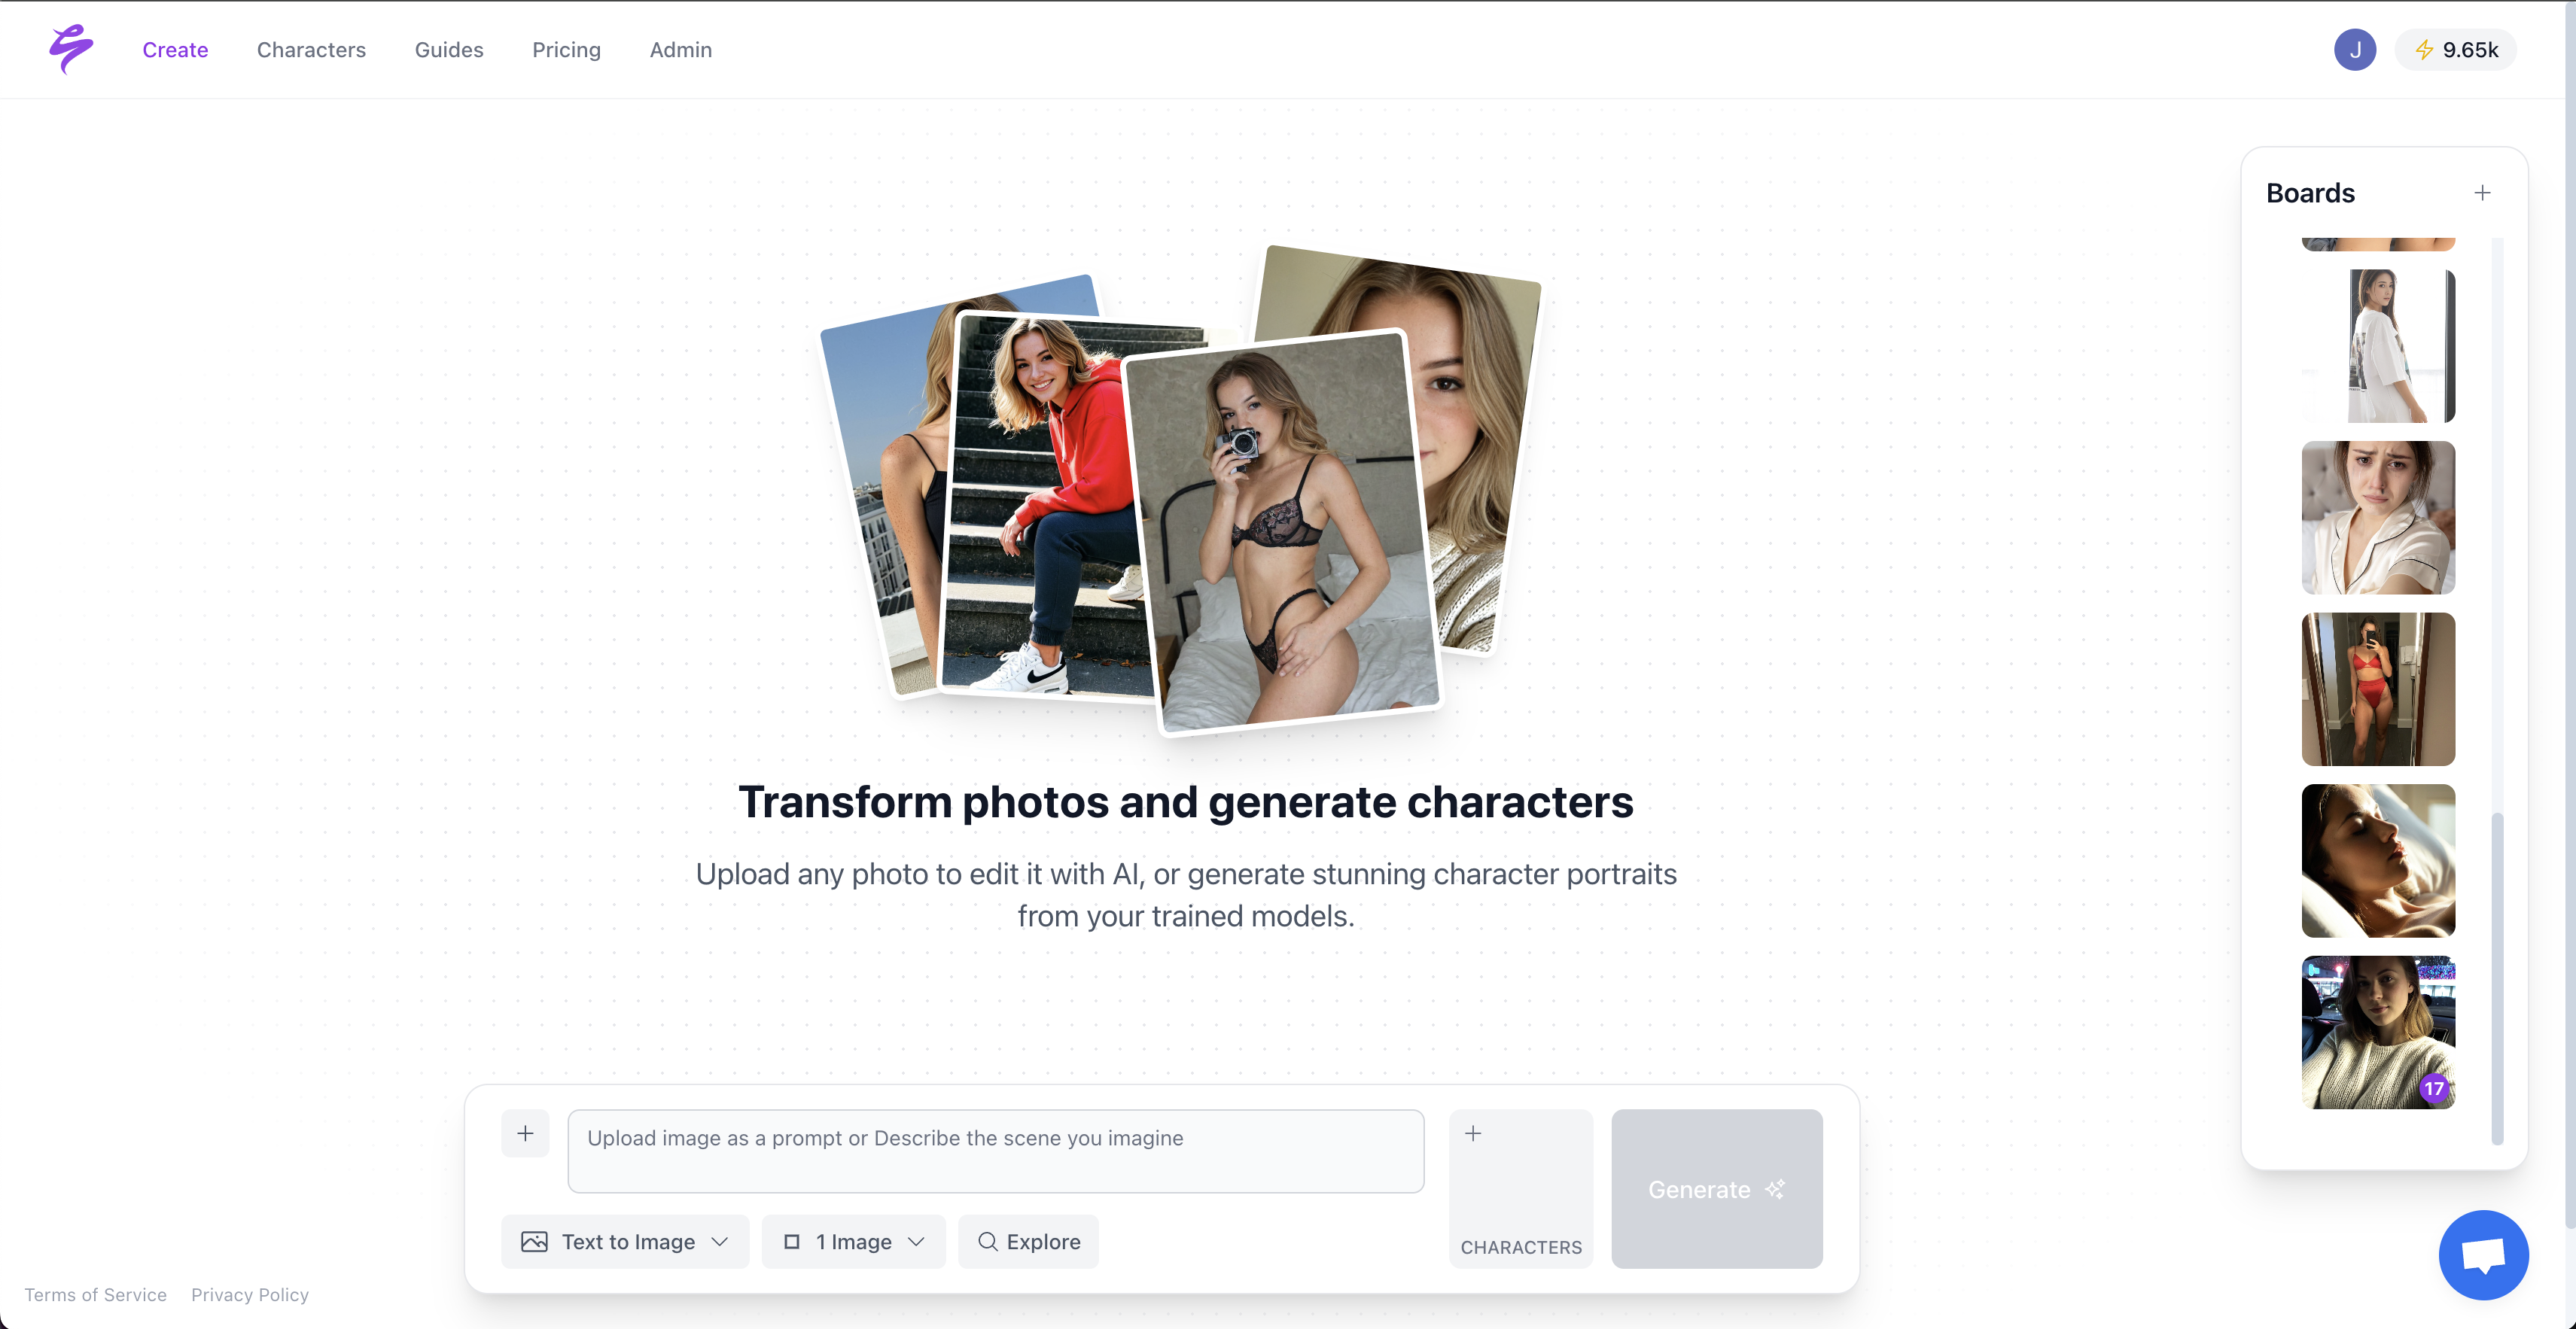
Many creators want face-swap-style output without the hardware burden, training grind, dataset curation, or legal exposure that the Deepfacelab pipeline creates. Sozee is the consent-first alternative for that group. Upload as few as three photos and Sozee instantly reconstructs a locked, consistent likeness, so there is no training run, no VRAM ceiling, and no download from an untrusted repository. Models are private, isolated, and never used to train anything else. Where Deepfacelab typically requires days of iteration to reach usable output, while polished, high-quality models can take about a week or more, Sozee replaces the entire pipeline with a directable studio that produces consistent results from the first frame.
Turn Three Photos Into A Directable Sozee Studio
Here are the questions creators ask most often about Deepfacelab.
Frequently Asked Questions
Is Deepfacelab Free?
Yes. Deepfacelab is free and open-source software released under the GPL-3.0 license. There are no subscription fees, usage limits, or watermarks imposed by the software itself. The real costs are the ones described above: a capable Nvidia GPU, days to weeks of training, and the labor of curating a clean dataset.
Does Deepfacelab Still Work In 2026?
Yes, the software still functions, but the original repository maintained by Iperov has not received substantive updates for years. Active users now rely on community-maintained forks, including a PyTorch port released in April 2026 that added support for Nvidia’s Blackwell-architecture RTX 50-series GPUs and mixed-precision training. The practical consequence is that support, documentation, and security vetting depend on community volunteers rather than a maintained official release.
How Long Does Deepfacelab Training Take?
Training time depends on GPU, resolution, dataset size, and target quality. As covered above, the timeline runs from roughly 12–20 hours for basic facial structure to a week or more for cinema-quality results, depending on GPU, resolution, and dataset size. Quick results using pretrained models can be achieved in 2–4 hours, while cinema-quality results may take considerably longer.
Can Deepfacelab Run Without A GPU?
CPU-only training is technically possible if the processor supports AVX instructions, but it is impractically slow for most use cases. Deepfacelab is architected around CUDA-based Nvidia GPU acceleration, so the software assumes a GPU rather than merely preferring one.
What Is A Safer Deepfacelab Alternative?
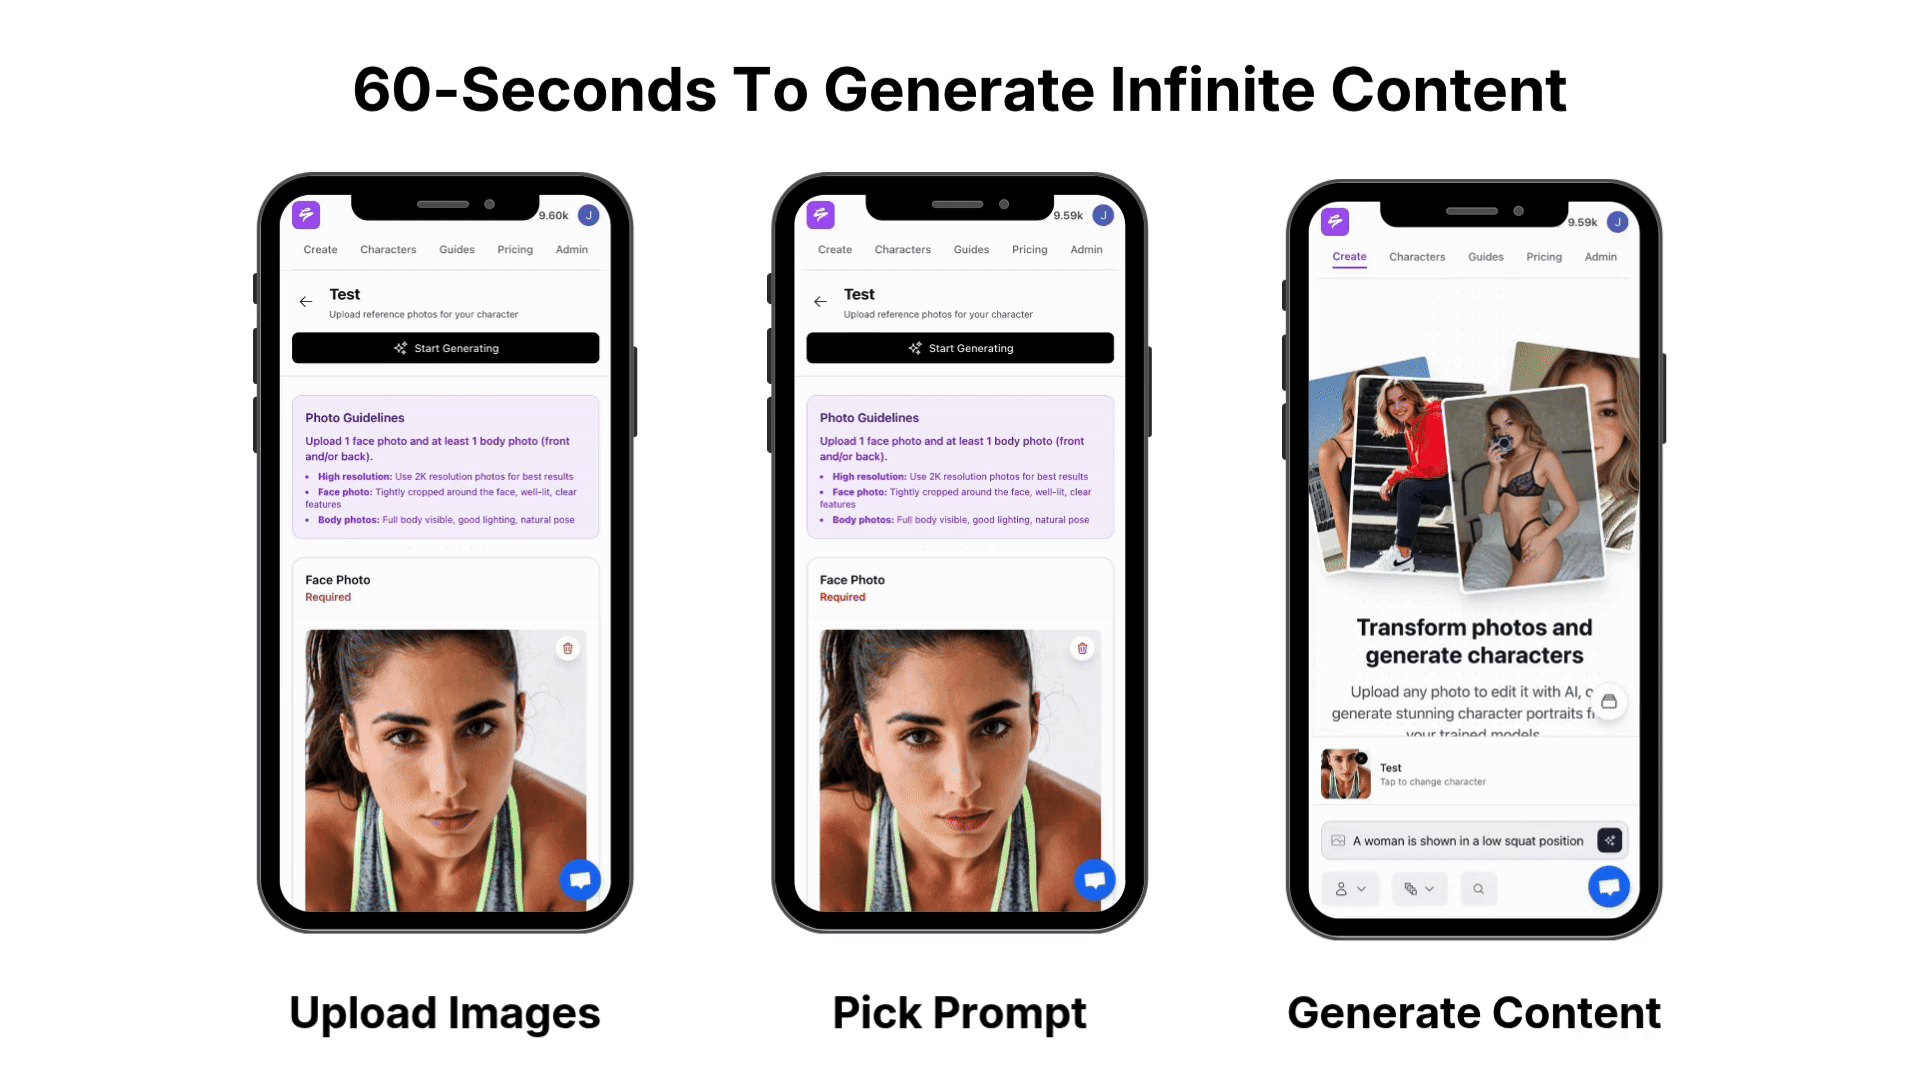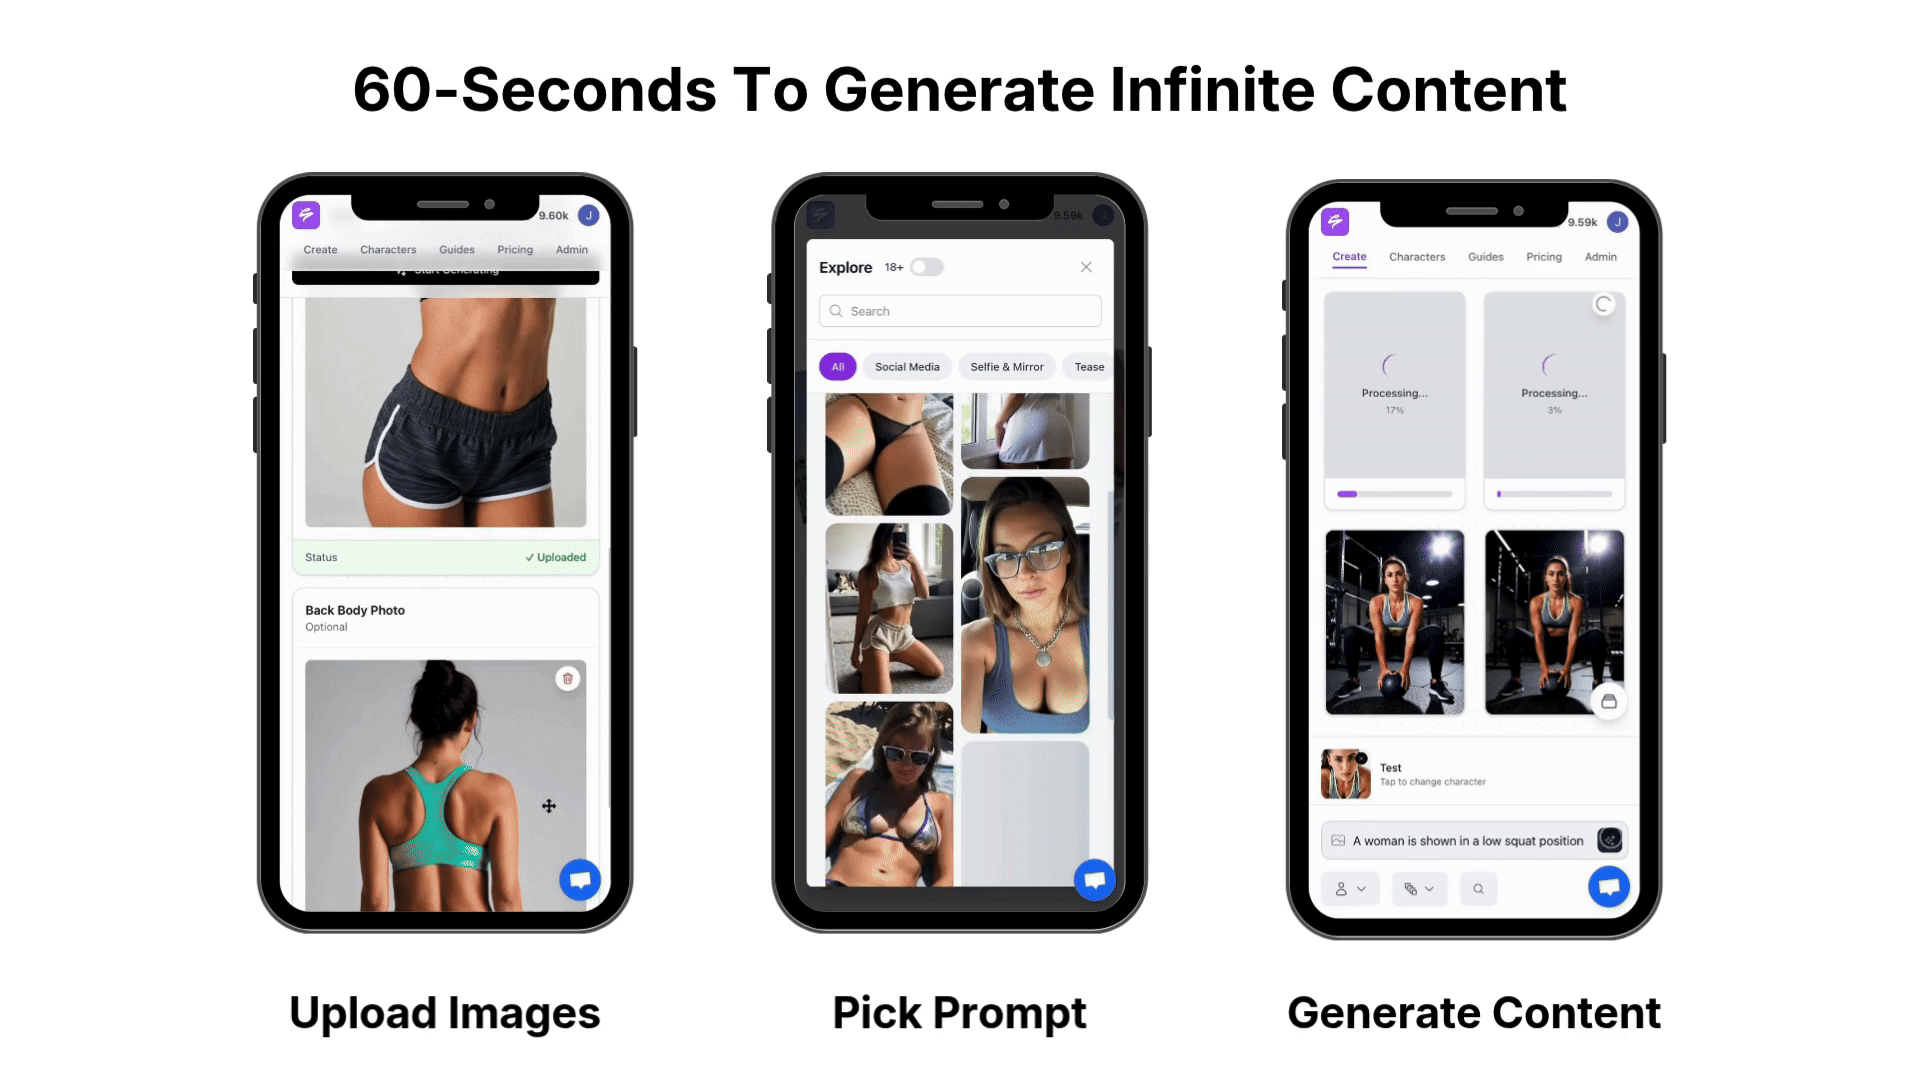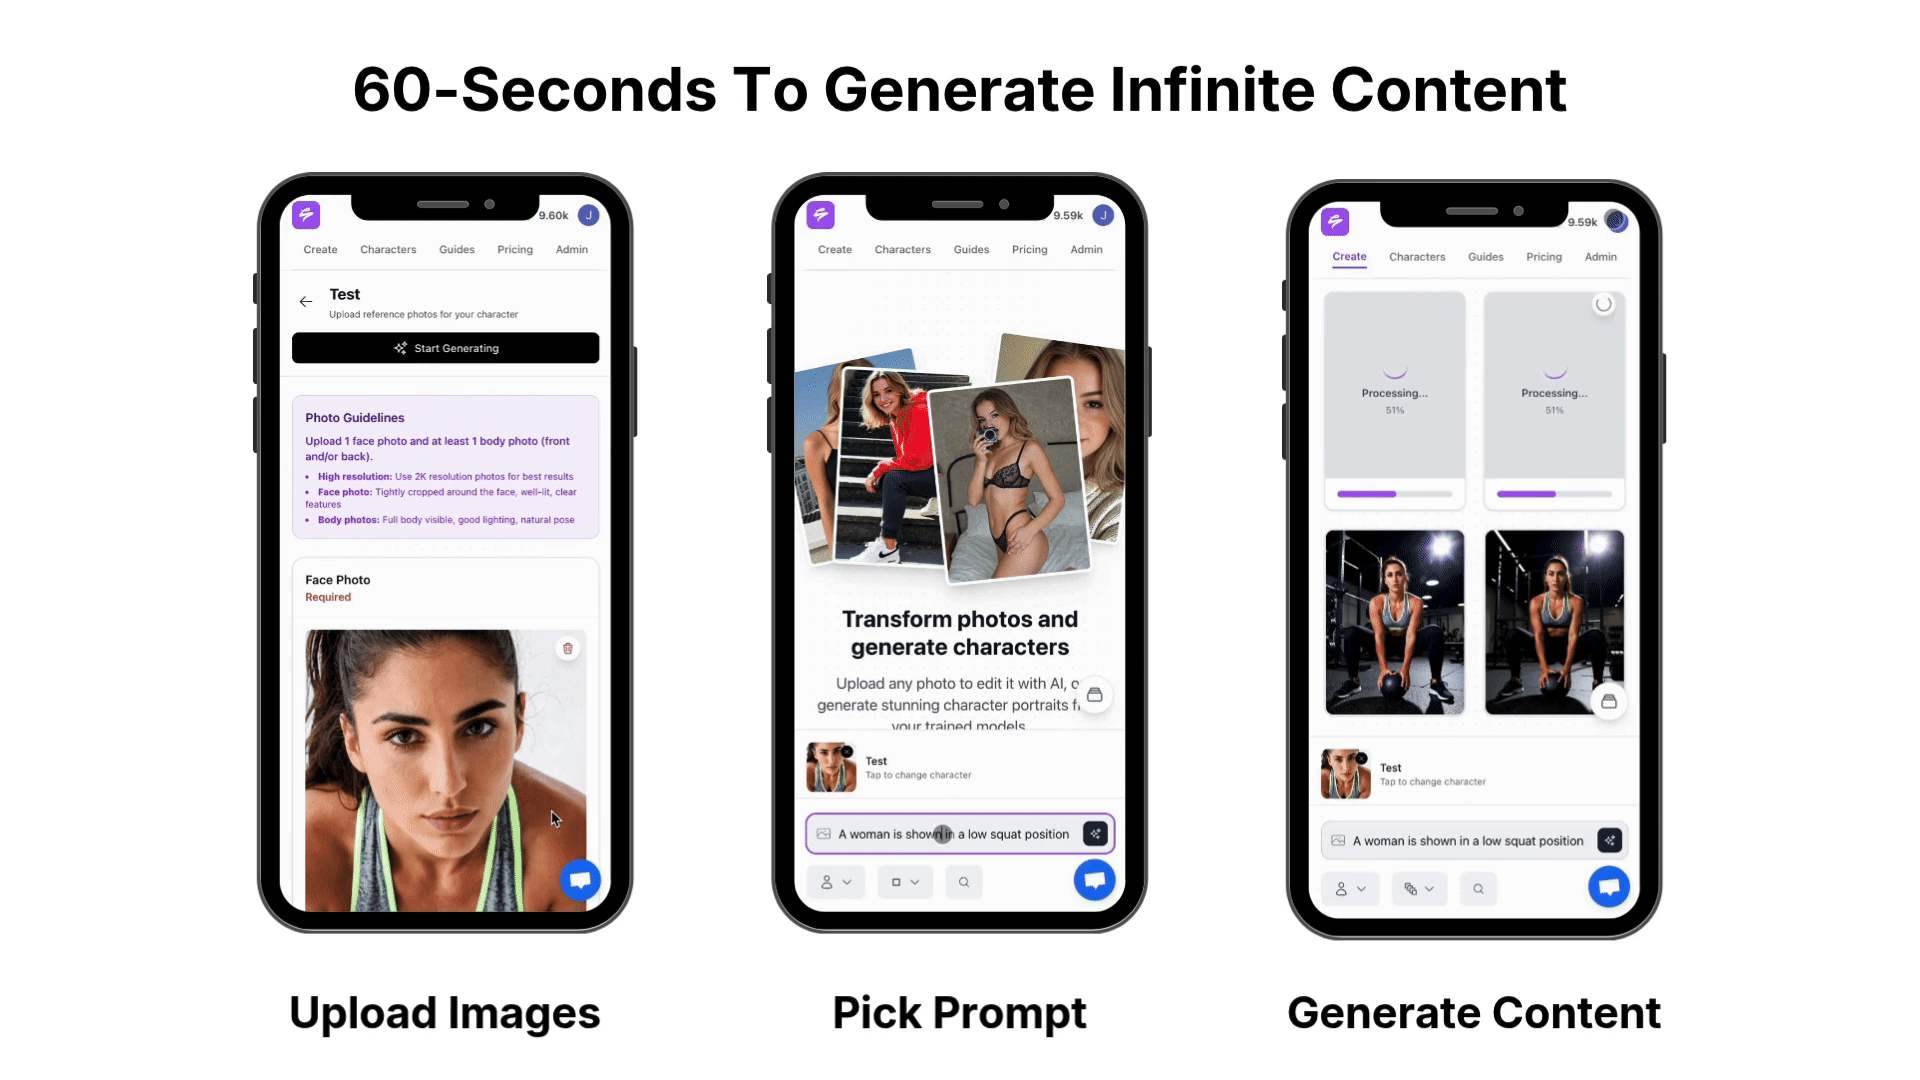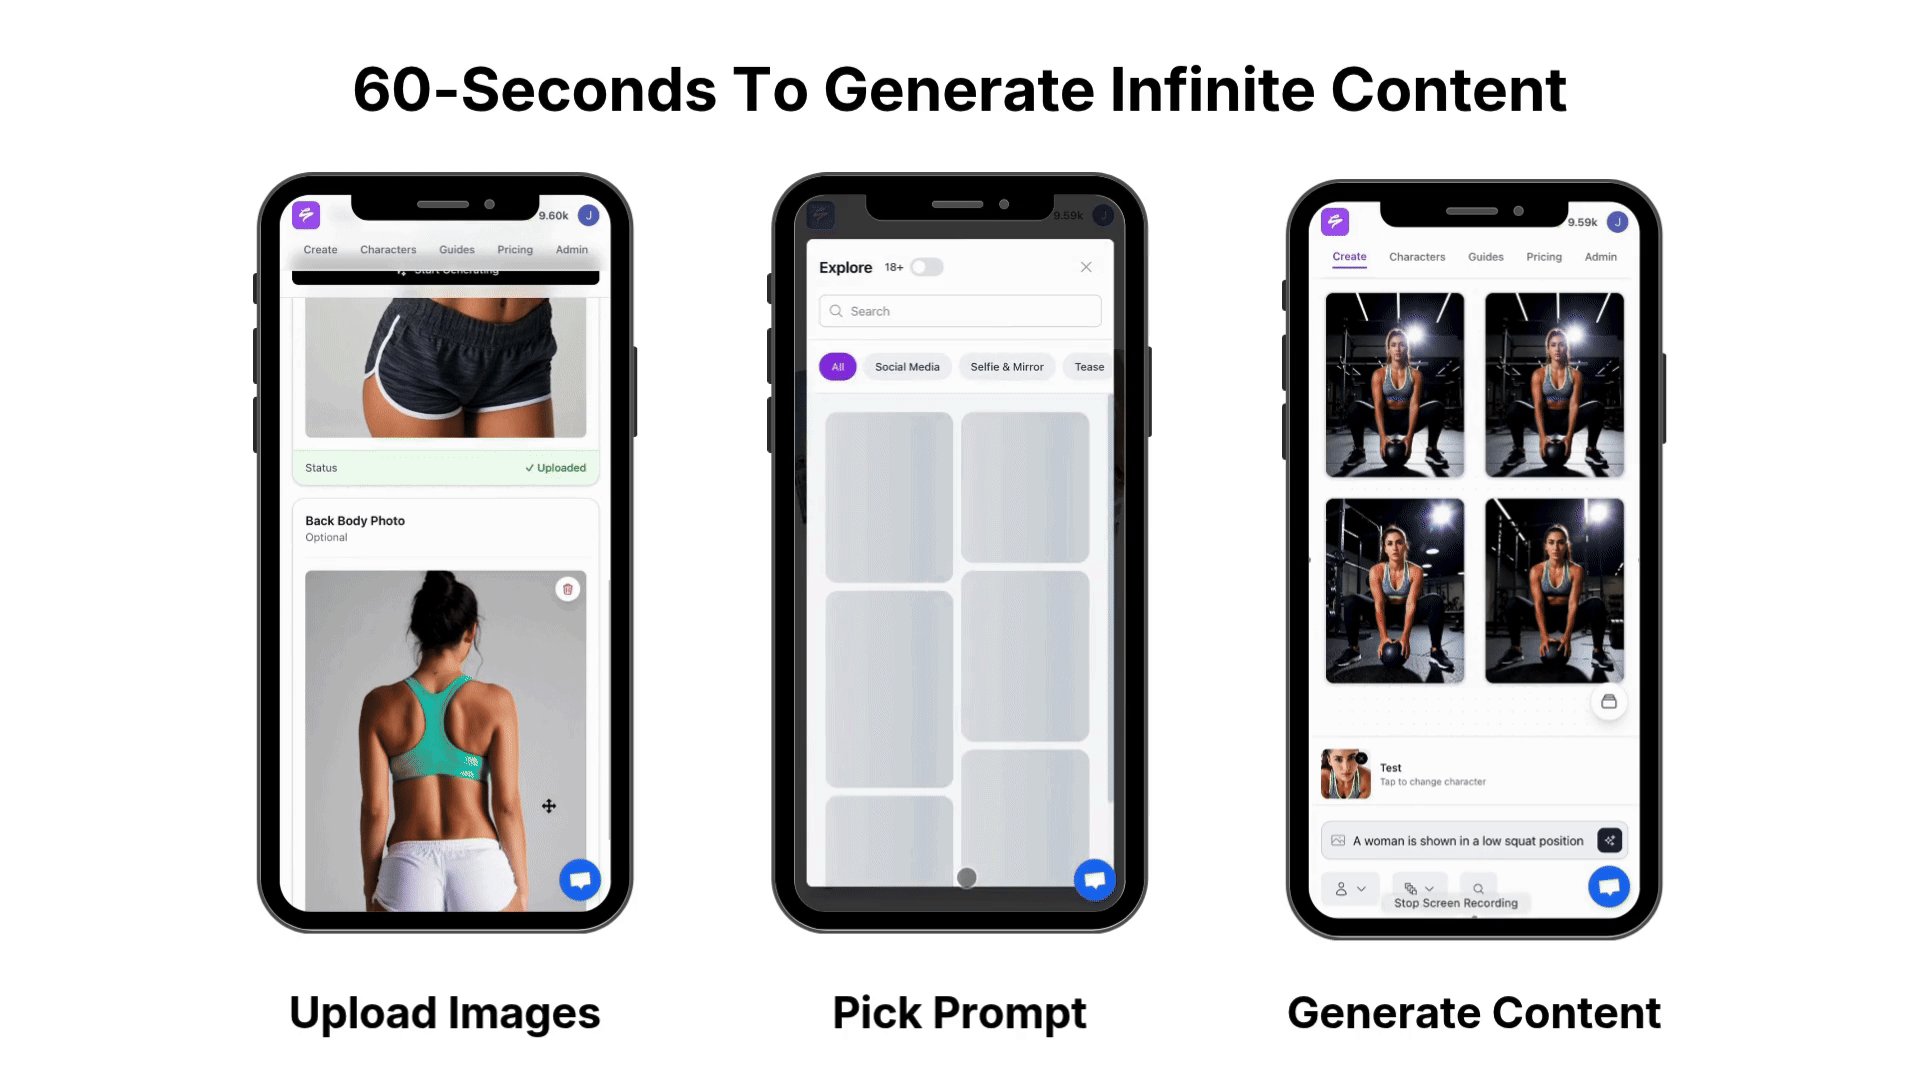
Sozee is the consent-first alternative designed for creators who need consistent, realistic likeness output without the Deepfacelab pipeline’s hardware requirements, training time, or security risks. From as few as three photos, Sozee locks a likeness and makes it directable across photos, video, and live mode, with no dataset curation, no VRAM constraints, and no downloads from untrusted repositories. Privacy is a core design principle, so your likeness model is private, isolated, and never used to train anything else.
Try Sozee And Start Creating Safely
Conclusion
Deepfacelab is a technically sophisticated framework that delivers a very high quality ceiling among open-source face-swap tools. That capability carries specific costs: VRAM constraints that force hardware investment, training runs measured in days or weeks, dataset curation that requires thousands of clean images, failure modes including flicker, warping, color mismatch, and visible seams, legal exposure that now spans federal law and dozens of state statutes, and supply-chain risk from a project that circulates through unverified forks and mirrors. The people who bear the harm from misuse, including subjects, viewers, and organizations, are rarely the people who control the tool.
Sozee exists for creators who want the output without the pipeline. It locks a likeness from three photos, so there is no training run, no VRAM ceiling, and no download from an untrusted repository. What replaces the weeks-long grind is a directable studio that produces consistent results from the first frame.
Create Your First Sozee Face Swap In Minutes