
Last updated: September 21, 2026
Key Takeaways
- The best AI image-to-video engine depends on the influencer archetype: HeyGen Avatar IV for talking-head UGC, Kling 3.0 and Runway Gen-4.5 for fashion and lifestyle motion realism, and Seedance 2.5 for faceless aesthetic content.
- Maintaining a locked likeness across multiple posts matters more than any single clip; identity drift makes content unusable for monetization on Instagram or TikTok.
- Free tiers across most tools restrict commercial use, resolution, length, or watermark removal, so they work best for testing before committing to paid plans.
- Reusable environments, outfits, and objects are essential for consistent output; a dedicated system handles this in one place instead of exporting to multiple tools.
- Sozee is purpose-built for virtual AI influencers who need locked identity, reusable worlds, and end-to-end scheduling in one platform.
Which AI Video Generator Fits Your Influencer Archetype?
Engine choice depends on the influencer archetype and whether the creator needs one clip or a month of consistent posts. Omid Saffari’s 2026 Image-To-Video Roundup frames it plainly: “animate this image” covers four different jobs. The archetype split below names the best engine per job and highlights how general-purpose engines struggle to hold a face across a calendar.
| Influencer Archetype | Best Engine | Primary Limitation |
|---|---|---|
| Talking-Head / UGC | HeyGen Avatar IV | Free tier restricts commercial use, identity drifts across sessions |
| Fashion / Lifestyle | Kling 3.0, Runway Gen-4.5 | Strong per clip, weak at holding a face across a calendar |
| Faceless / Aesthetic | Seedance 2.5, free-tier tools | Short clips, watermarks, resolution caps on free plans |
| Virtual AI Influencer | Sozee | Built for locked-likeness production pipelines, not single-clip demos |
Talking-Head And UGC Influencers: HeyGen Avatar IV Wins The Job
For short-form, direct-to-camera talking-head clips, HeyGen’s Avatar IV wins on lip-sync and mouth tracking against Synthesia and offers voice cloning across all 175+ supported languages. The realism advantage is narrow and largely disappears on longer-form content. For a creator who needs a clean, on-brand spokesperson delivering scripted lines, HeyGen’s Avatar IV is the industry benchmark for avatar realism. Its lip-sync, micro-expressions, and full-body gestures lead the category, while real human talent still suits emotionally nuanced or high-budget brand work.
HeyGen breaks on three fronts: limited motion realism, identity drift across sessions, and licensing. Section 4 of HeyGen’s terms restricts free output to personal, non-commercial, and internal evaluation purposes, which rules out client work, advertising, and monetization by name. Watermark removal and 1080p export start on the Creator plan at $29 a month.
The talking-head gap is narrowing as other engines add audio and lip sync. Kling 3.0 adds native audio generation and multilingual lip sync for English, Chinese, Japanese, Korean, and Spanish. Veo 3.1 generates dialogue and ambience in the same pass, which makes it a credible alternative for creators who want synchronized native audio without a separate lip-sync tool.
Fashion And Lifestyle Influencers: Kling 3.0 And Runway Dominate Motion Realism
Talking-head tools solve the spokesperson problem, but fashion and lifestyle content depends on motion realism, such as how fabric moves or how a walk reads. That is where Kling 3.0 and Runway Gen-4.5 stand out. Kling 3.0 supports image-to-video as a core input mode, claims native 4K output, and includes multi-shot storyboarding with up to six connected shots. Runway Gen-4.5 pairs with a real editor including a motion brush and camera directives and hosts Veo 3.1, Kling 3.0, and Seedance inside one subscription.
Both engines excel on a single clip and struggle to hold a face across a content calendar. For the Kling vs Runway comparison, Runway scored 9.2/10 for editing flexibility versus Kling’s 8.2, so Runway fits workflows where the generated clip is one stage in a larger creative process. Kling is cited most often by practitioners for close-up face consistency on dialogue beats, and one 2026 roundup rates its free tier as the most generous in the category, while other sources describe that free tier as watermarked, 720p-capped, and non-commercial.
For the Veo 3.1 vs Kling comparison, one 2026 image-to-video roundup calls Veo 3.1 the benchmark for photorealism and synchronized native audio, though its access routes are less straightforward for repeatedly animating stills. Kling remains the pick for keeping a face from morphing or drifting across a clip. Google retired Veo 3 and Veo 2 on 30 June 2026, so reviews of those versions describe models that are no longer available.
Faceless And Aesthetic Accounts: Seedance 2.5 And Free-Tier Tools
Faceless accounts sidestep the face-consistency problem, so reference depth matters more than likeness lock. That shift makes Seedance 2.5 especially useful. ByteDance Seed’s official blog post states that Seedance 2.5 allows users to input up to 30 images, 10 video clips, and 10 audio clips as reference materials in a single pass, and generates native 1080p video up to 30 seconds with joint audio. For faceless aesthetic content such as product reveals, ambient lifestyle loops, and abstract visual storytelling, that reference depth is a genuine production advantage.
Free tiers across the category carry real restrictions and work best as test beds. Free tiers often run on older or smaller model versions, so quality comparisons made on a free plan understate what a paid plan produces. Treat free tiers as a testing ground before committing to a monetized stack.
The Image-To-Animation Handoff: Your Source Image Determines Your Motion
In image-to-video workflows, the source image acts as the model’s frame zero, defining the diffusion starting point and setting noise levels, so output quality is disproportionately tied to input composition. That connection means the source image’s flaws become the video’s flaws. A cluttered image with ambiguous depth cues produces jitter and shimmering, while flat or soft lighting produces the most stable outputs.
Image-to-video is significantly more reliable than text-to-video for maintaining exact character identity, because text prompts force the AI to invent the digital actor and the motion simultaneously, which often causes severe facial morphing.
Re-generating a character for every clip causes identity drift. Diffusion models have no persistent character memory: each frame is rebuilt from random noise conditioned on text, so small shifts in jawline, eye spacing, or skin tone accumulate until the face reads as someone else. Even a tiny per-frame drift compounds into a visibly new person across a 20-shot film.
How To Keep The Same AI Character Across Multiple Videos
The following workflow steps appear consistently across the character-consistency literature and give creators a repeatable process.
- Lock the character’s likeness at the source-image stage. Build a reference set of front portrait, three-quarter view, expression shot, and full body, all sharing the same lighting family and free of filters or beauty smoothing, because four aligned images outperform eight contradictory ones.
- Reuse the same reference images rather than re-generating. Swapping reference images between shots because a new one “looks sharper” breaks continuity.
- Save and re-attach environments, outfits, and objects instead of re-describing them. Lock vocabulary so “shoulder-length dark brown hair” never becomes “brunette,” because the model treats them as different people.
- Keep the same aspect ratio and resolution across a set. Prepare the final aspect ratio before generation, so a clip intended for TikTok or Reels is generated in a vertical frame rather than heavily cropped afterwards.
- Review frames before publishing to catch drift. Check eye spacing, nose bridge width, jawline contour, and that distinguishing marks remain on the correct side.
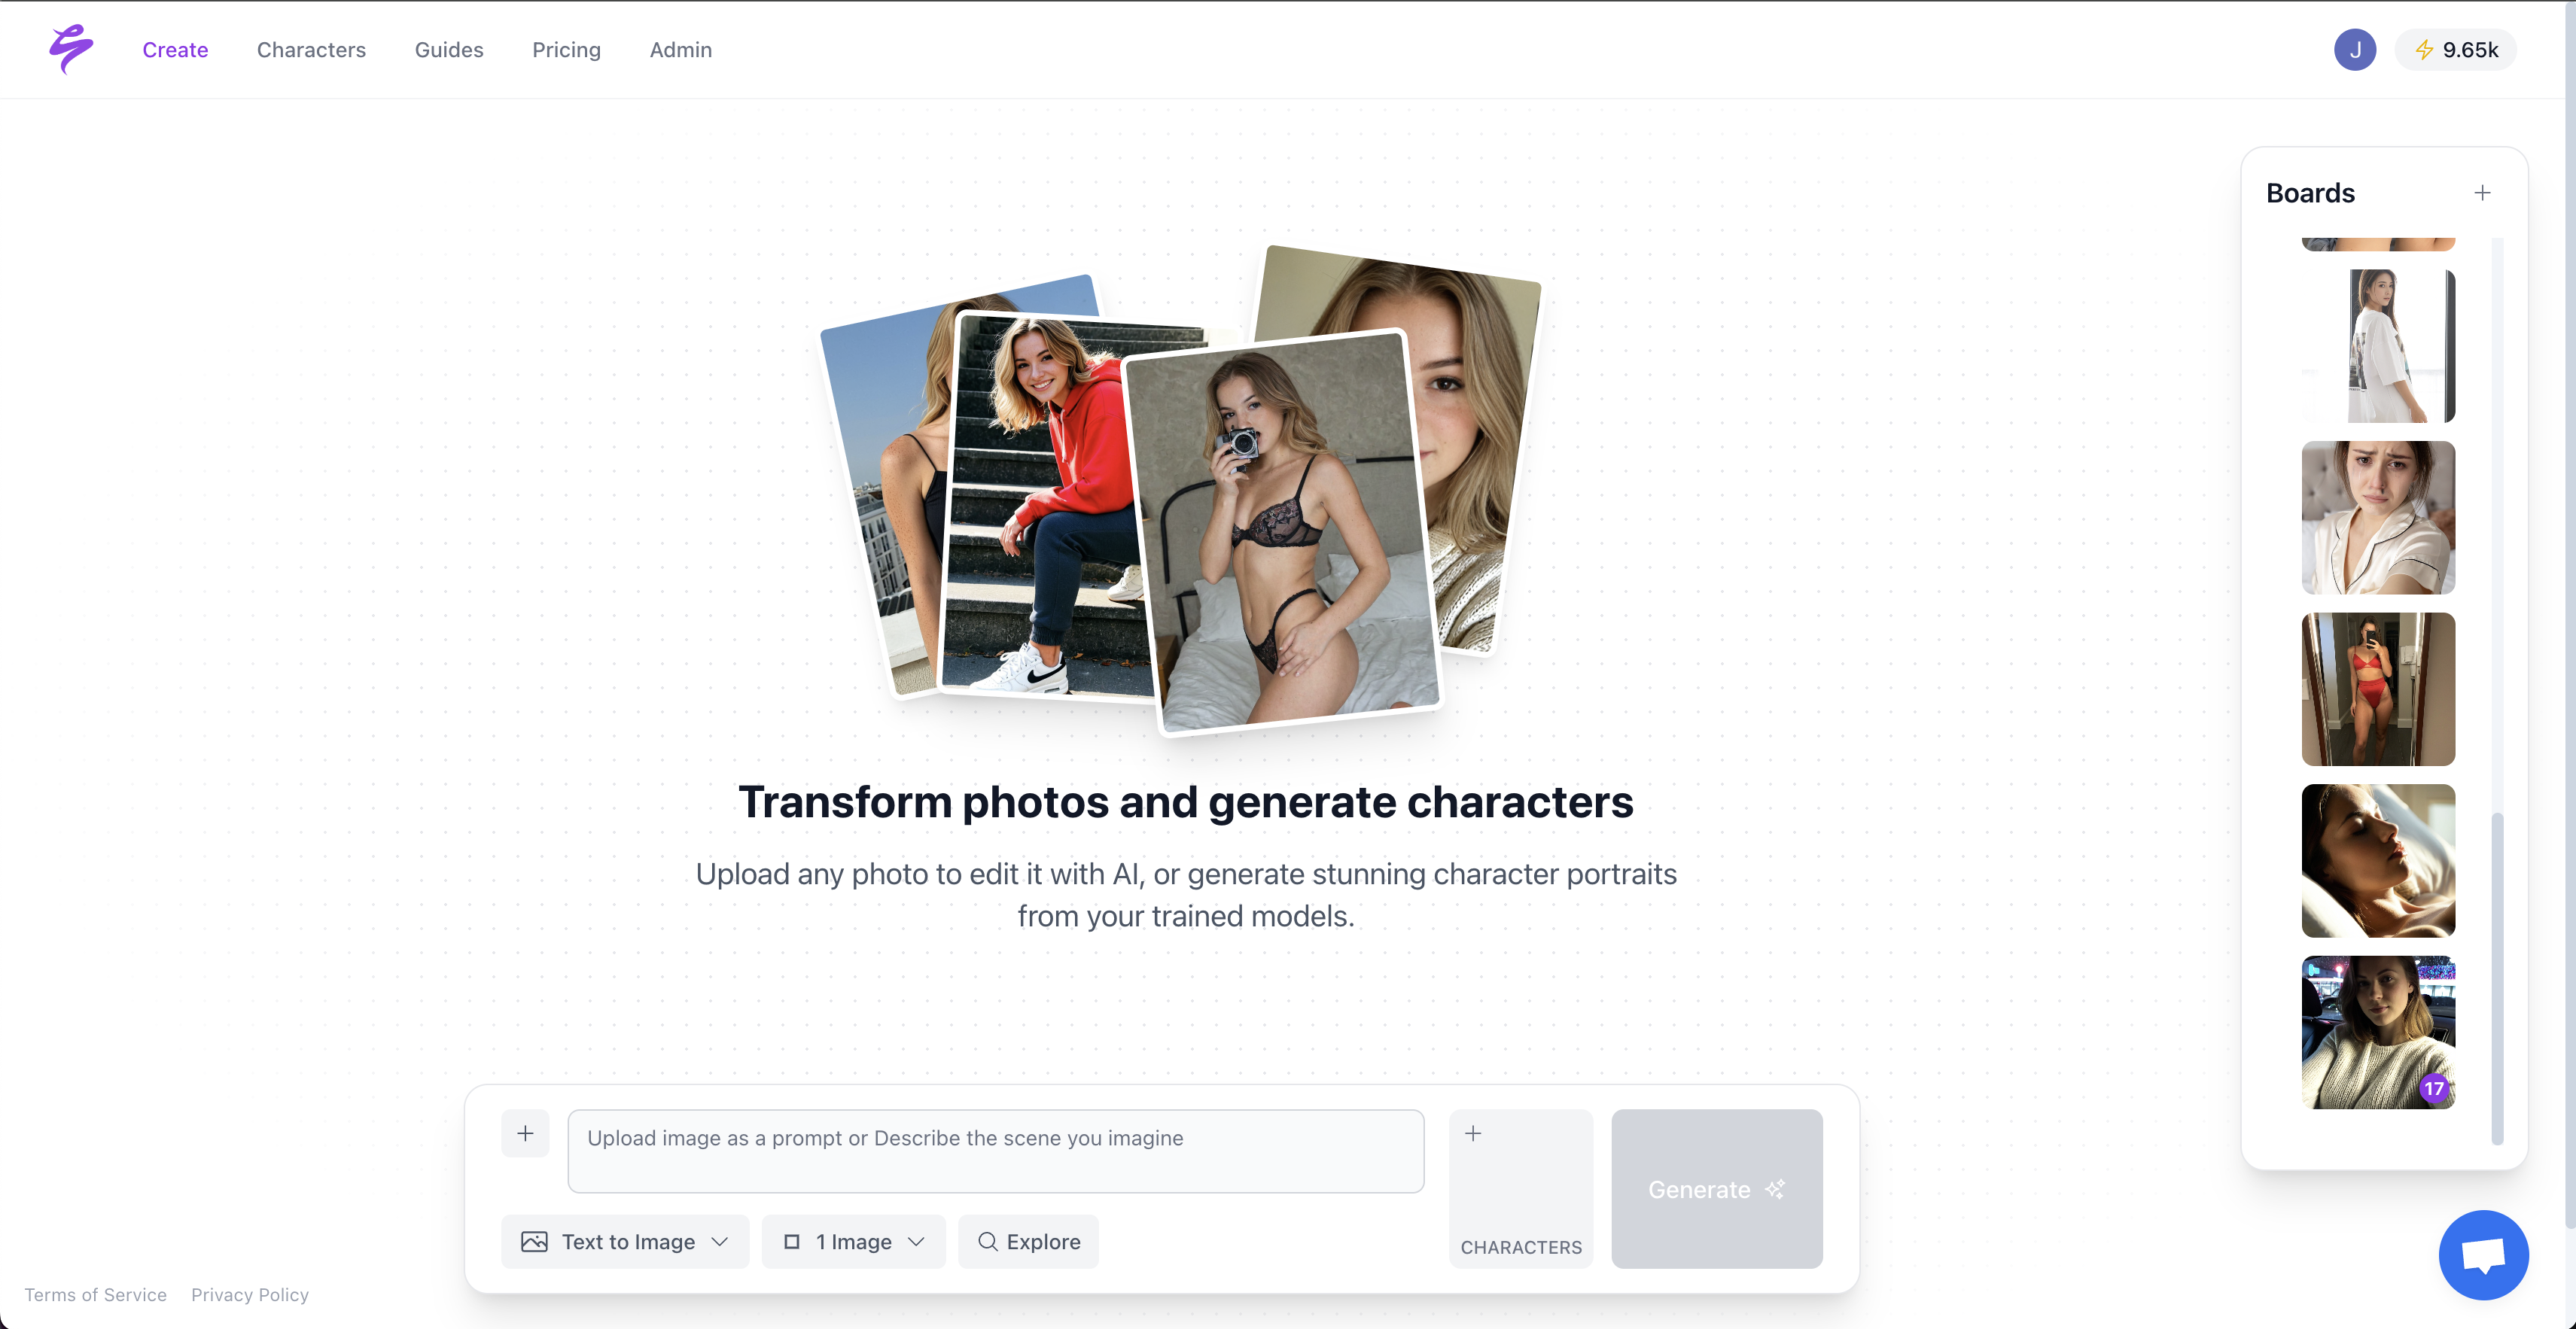
Sozee’s locked-likeness and reusable-asset model turns that workflow into a repeatable system. Each reference set becomes a locked likeness, environments become reusable Settings, and outfits and props become library items that re-attach with one click. The same face and world return every time without rebuilding them from scratch.
Virtual AI Influencers: Sozee Is The Only Platform Built For A Locked Identity
The global virtual influencer market is valued at USD 13.2 billion in 2026 and projected to reach USD 424.8 billion by 2036 at a 41.5% CAGR. The infrastructure problem holding that market back is consistency, not model quality. General-purpose AI tools cannot solve that structural gap, and Sozee is built specifically for it.
Upload as few as three photos and Sozee reconstructs a likeness with hyper-realistic accuracy. You can also generate an entirely original character from scratch, a face that has never existed, consistent from the first frame. No training, no waiting, and no technical setup.
Direction in Sozee works through Photo Control’s five dimensions: Setting, Outfit, Shot style, Expression, and Object. Each slot can be filled by upload, library selection, or inline @-reference. Photo Shoot takes one image and builds a coherent locked set of up to ten, so identity, outfit, and environment stay locked while angle, pose, and expression move. For motion, Sozee supports animating a still, video-to-video, and reel cloning, and Live Mode renders the character onto a camera feed in real time.
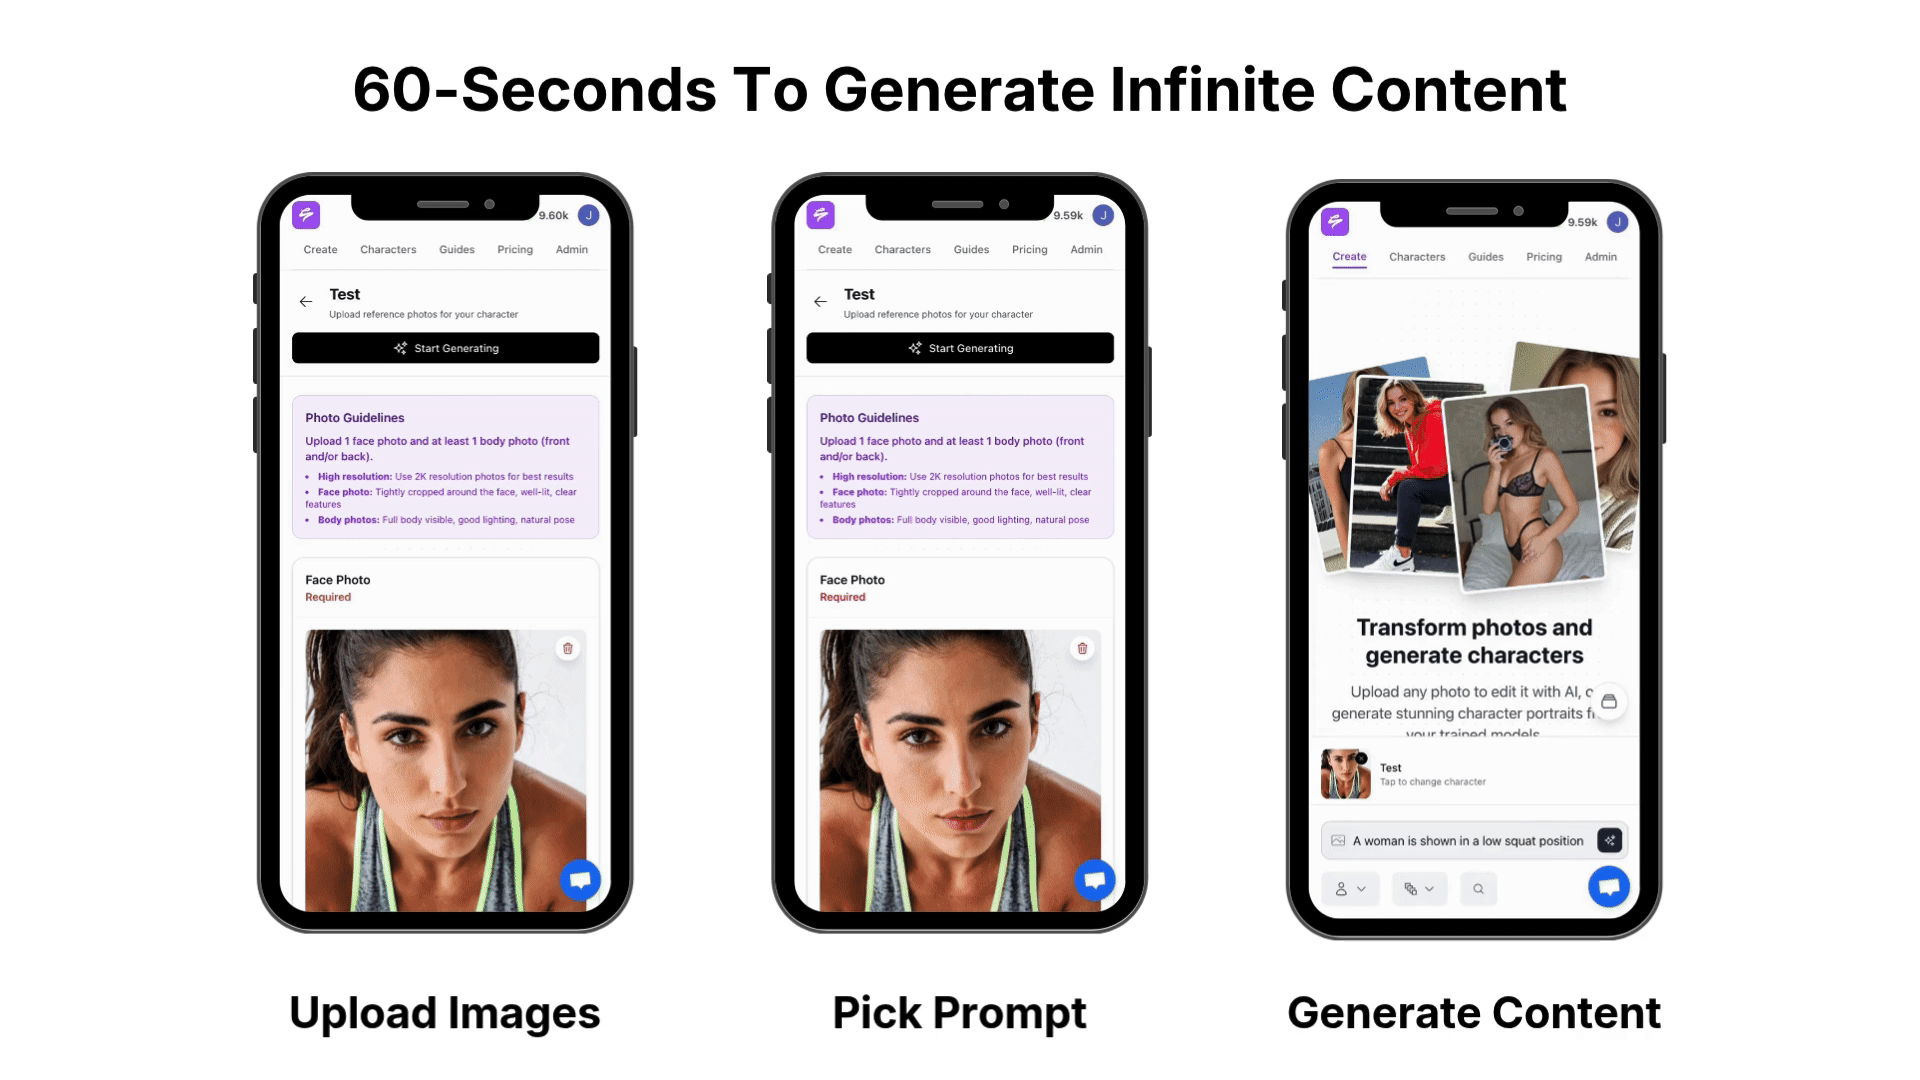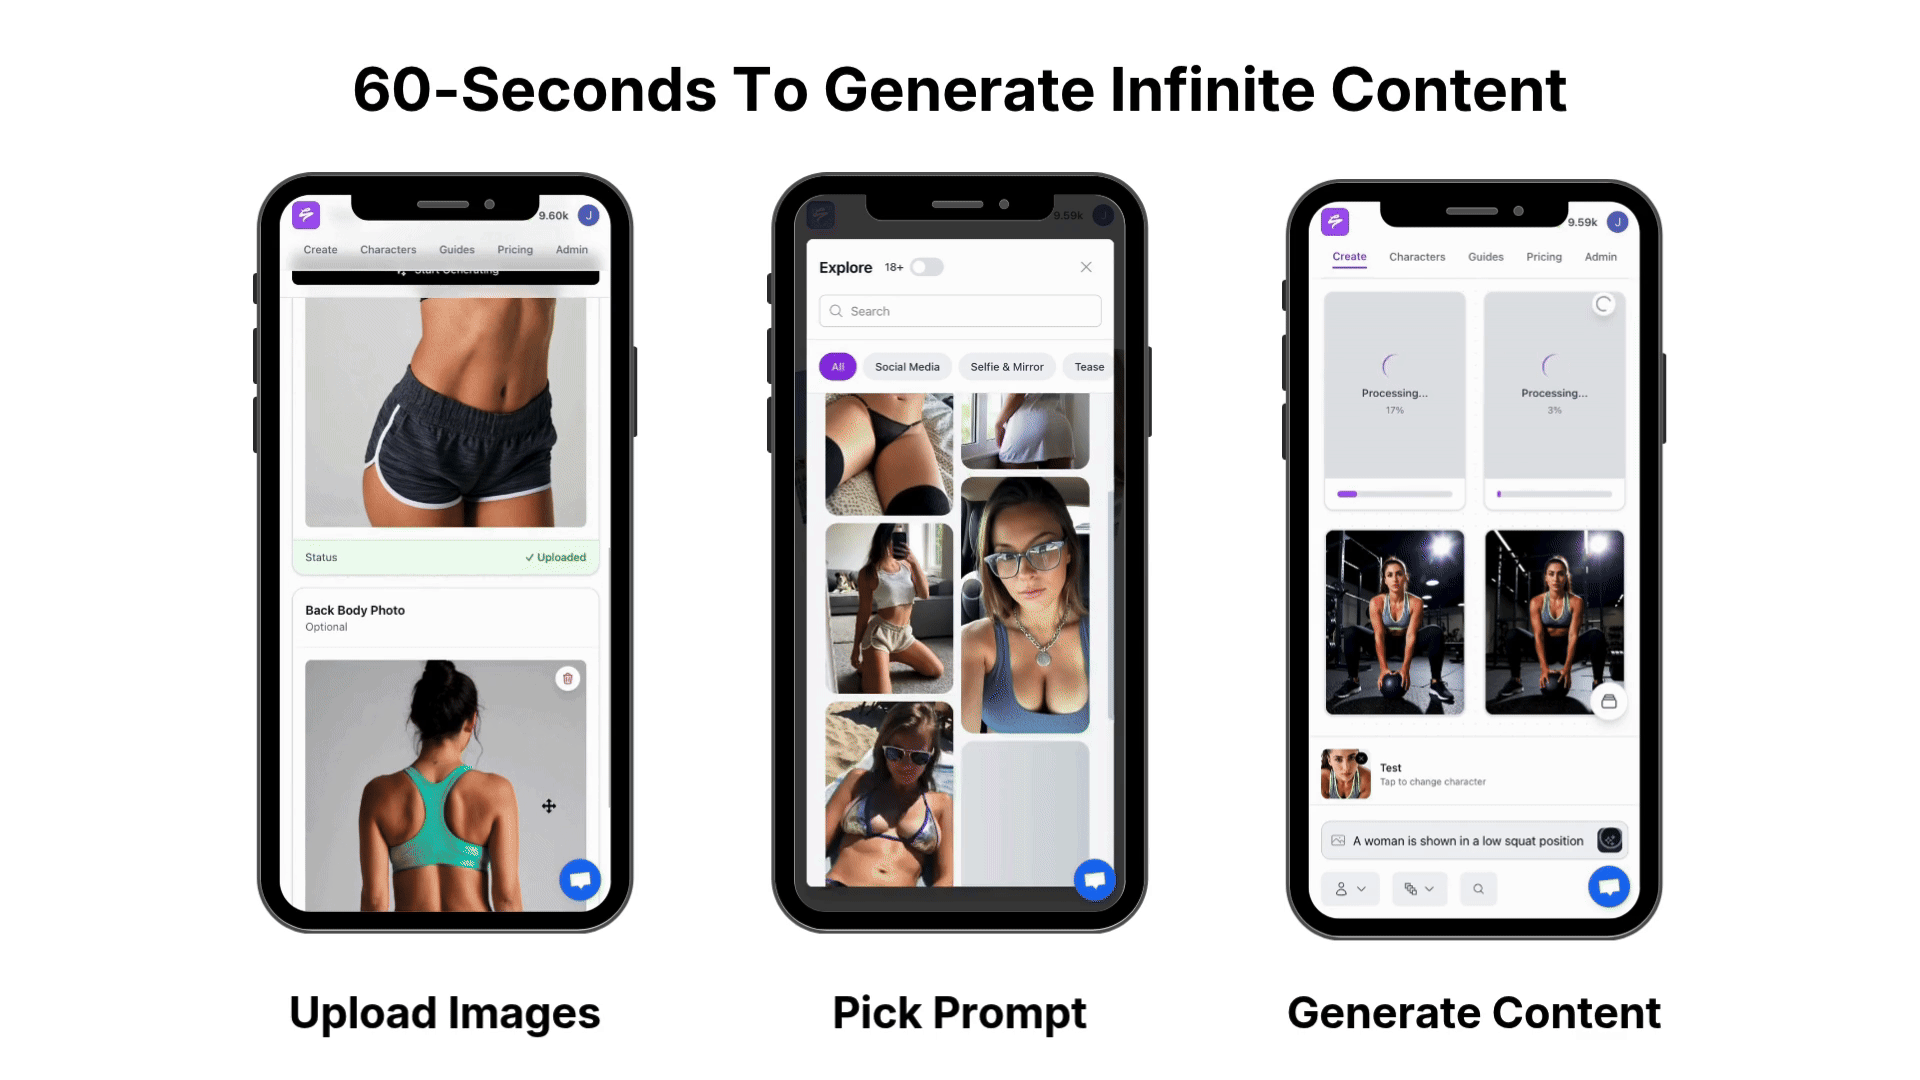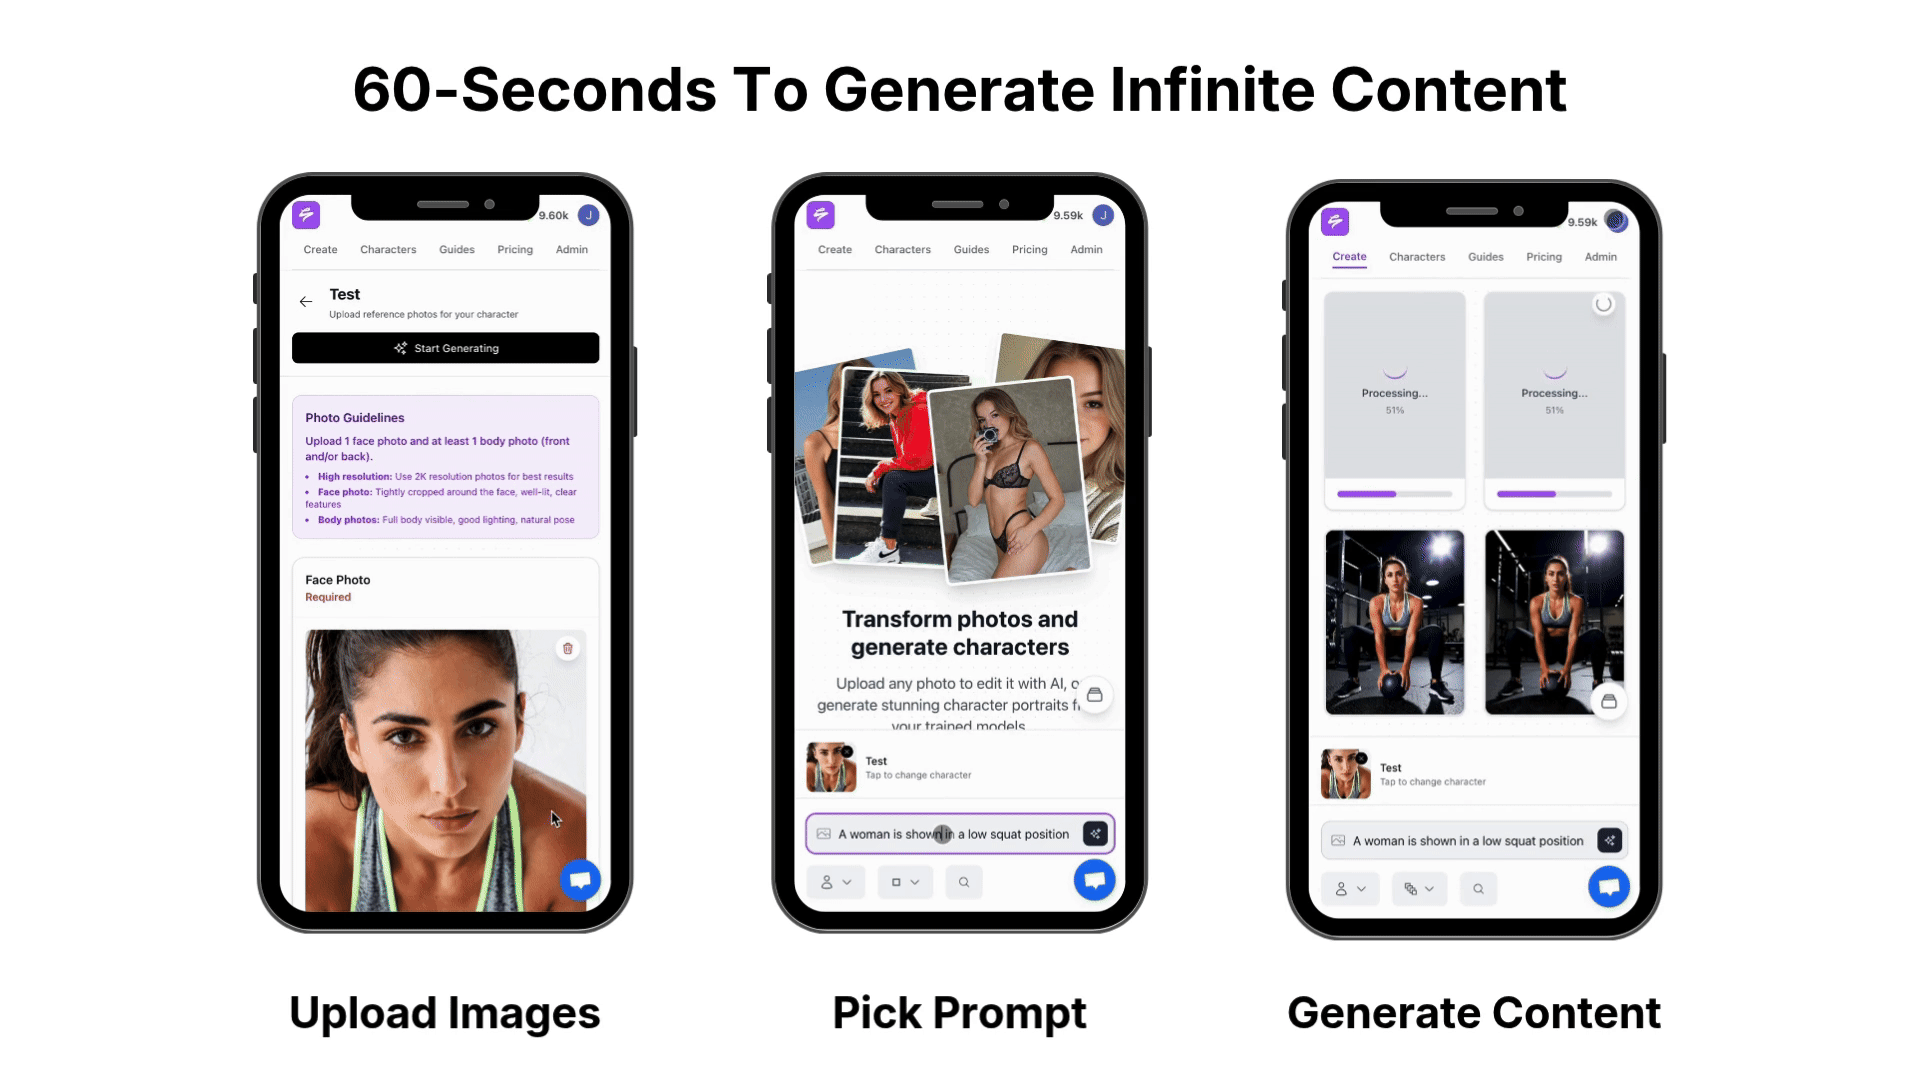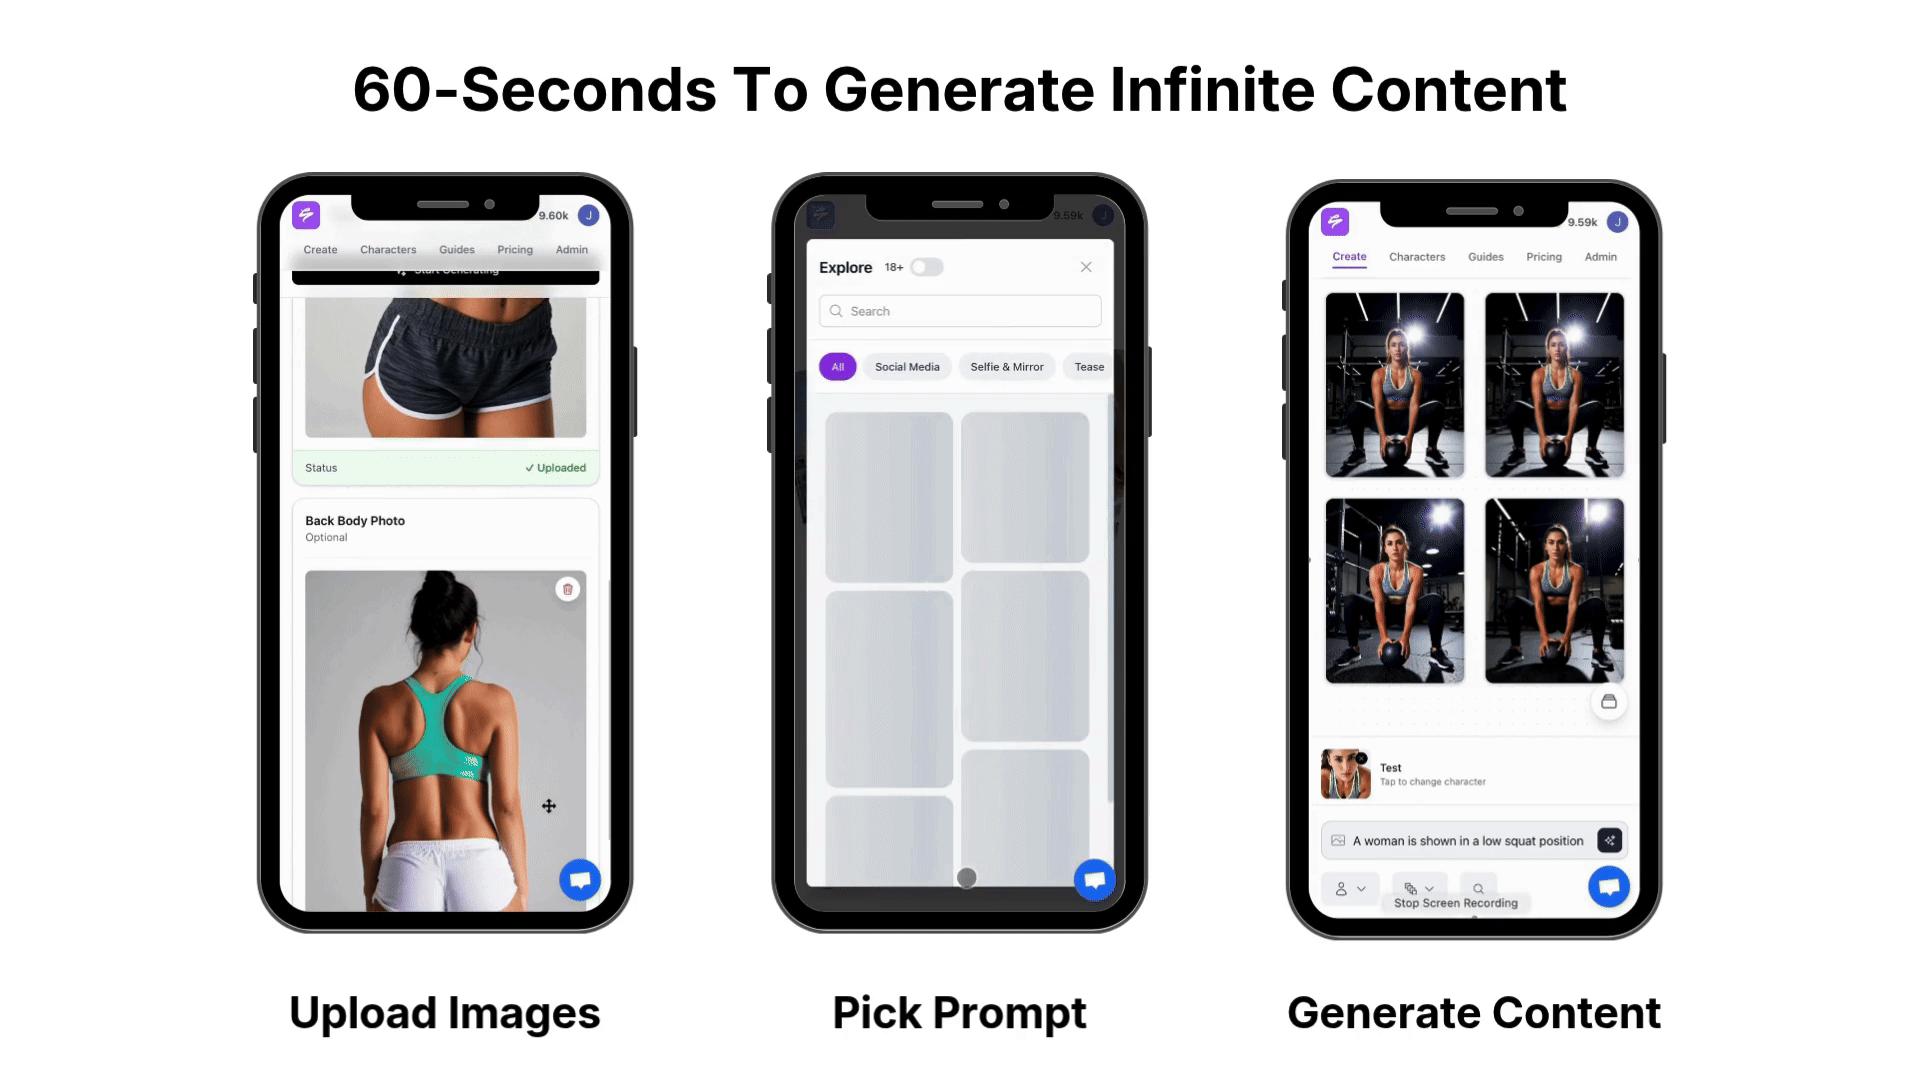
The differentiator is structural rather than a claim about model quality. Settings are reusable environments built from up to four reference shots, outfits assemble from a curated library with one piece per category, and objects steer the scene with up to four props per set. Because those assets persist, the Vault, Scheduler, and Analytics close the loop from generation to scheduled post across Instagram, TikTok, X, Facebook, Reddit, and Fanvue, with a caption per platform and a live preview. That structure keeps the same face and world present every frame, every week, without exporting to five other tools.
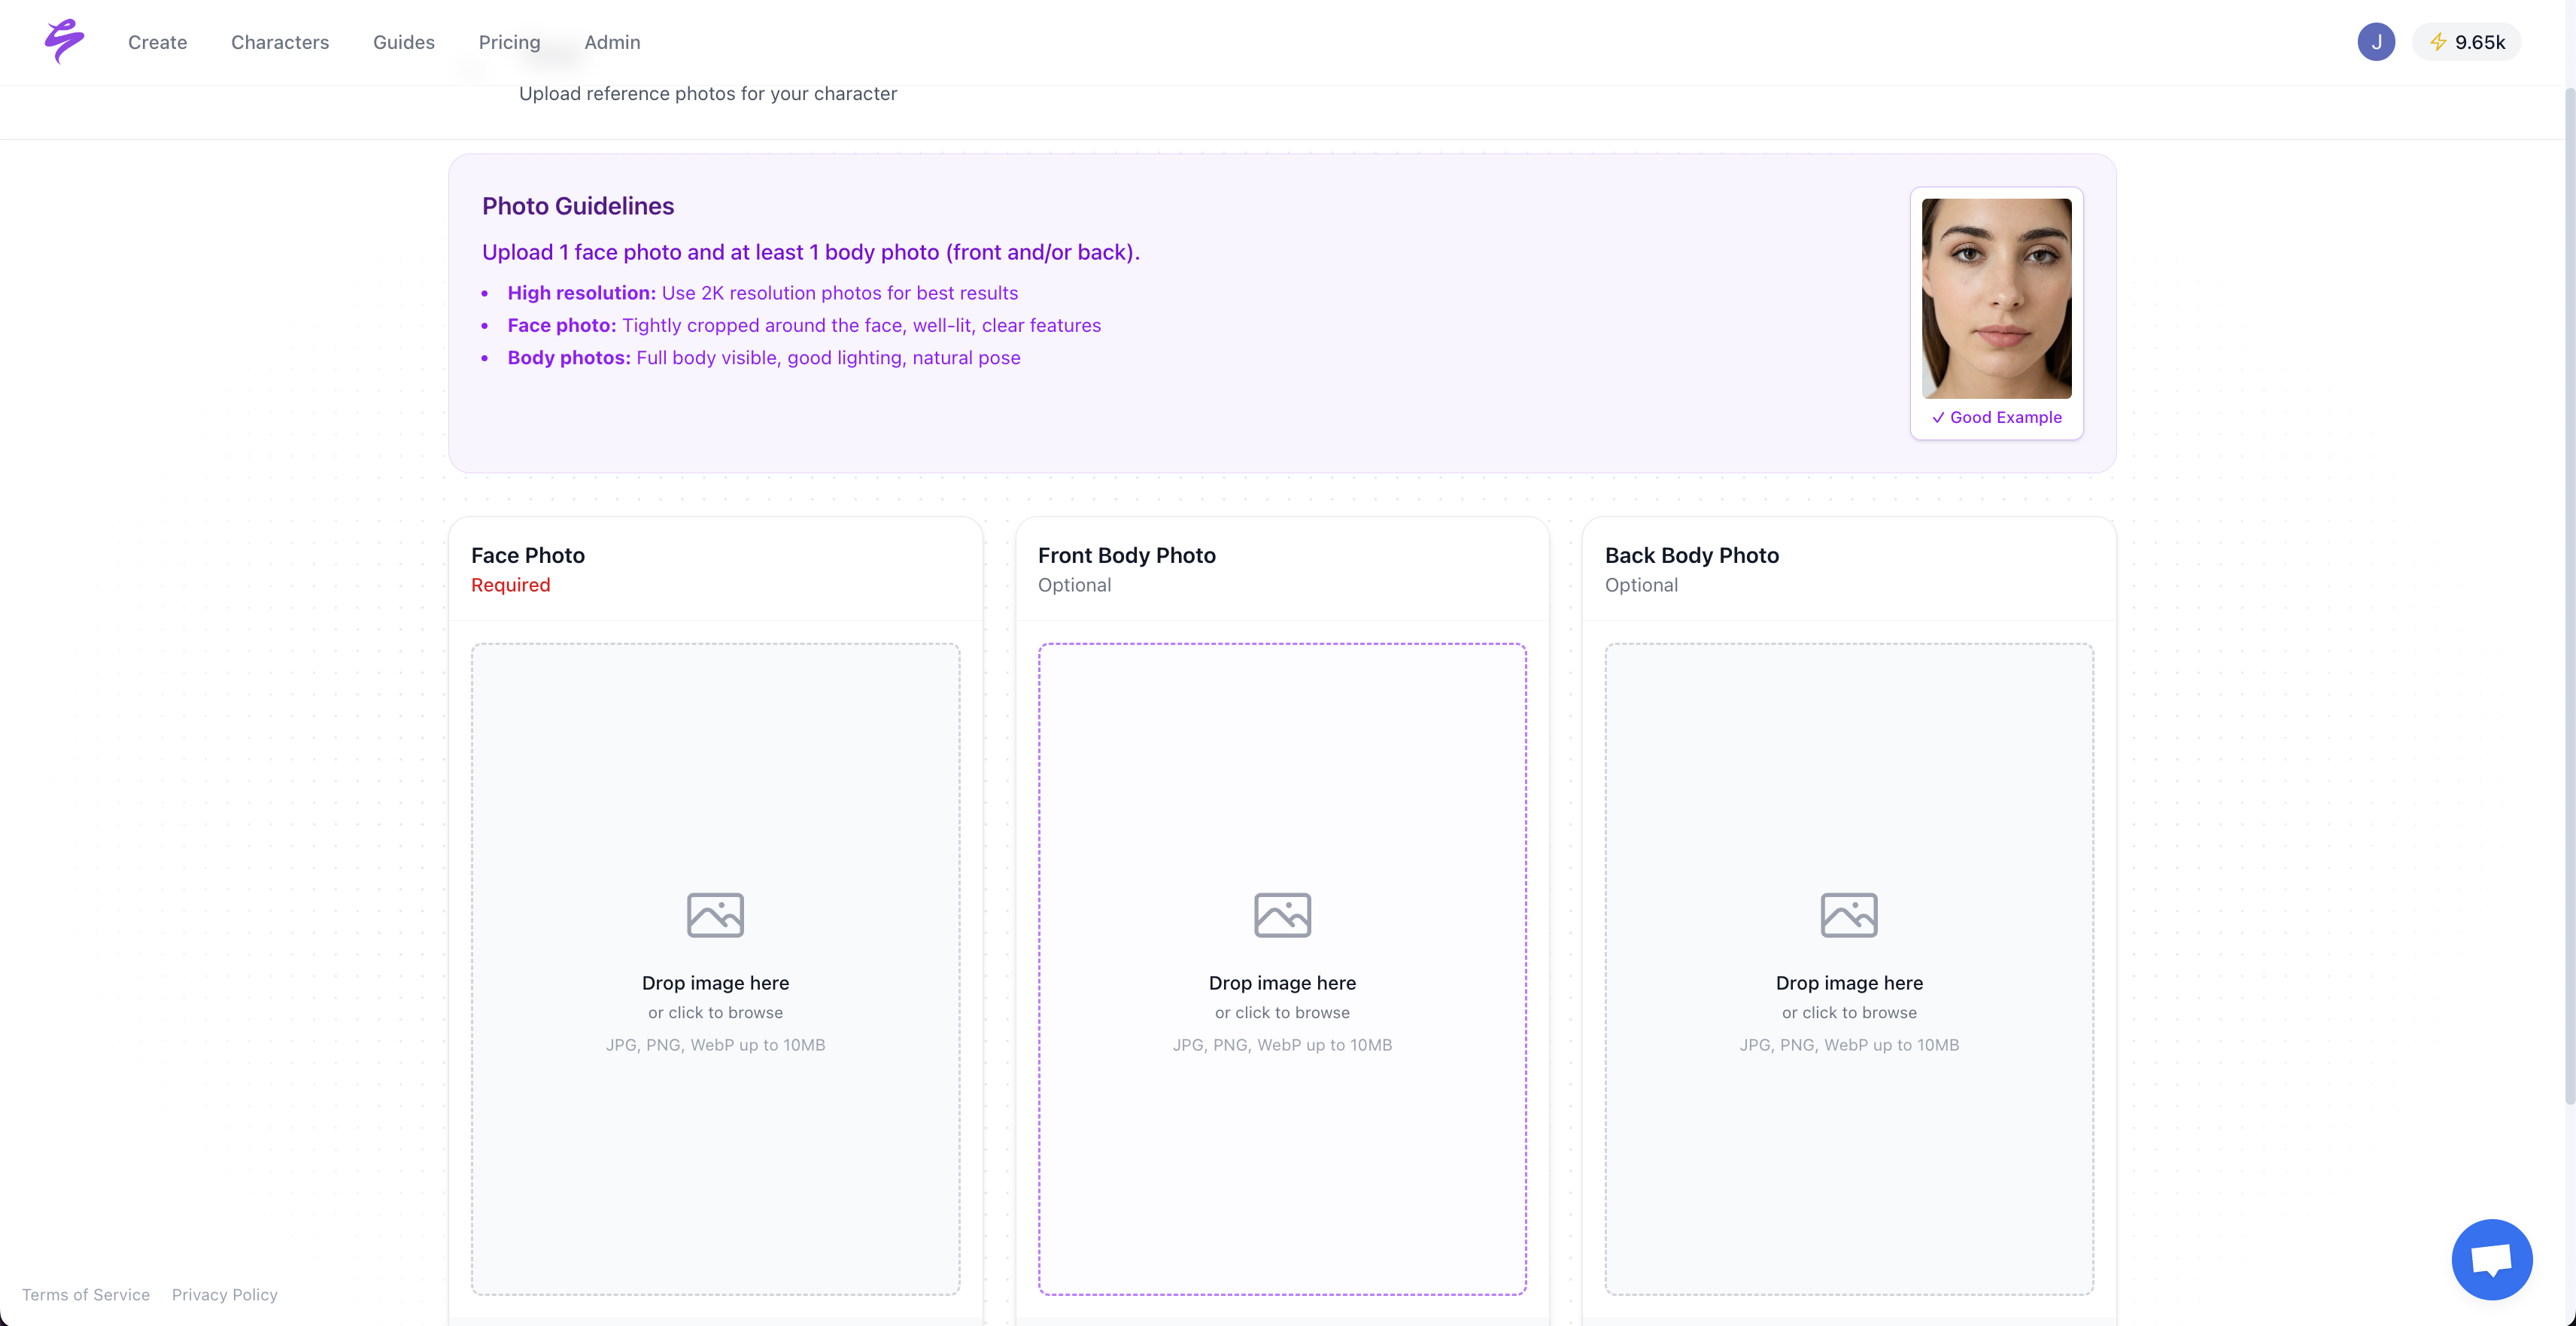
Create Your Locked-Identity Influencer
What Happens After Generation: Scheduling, Captions, And Posting Cadence
Even a perfectly consistent clip only matters if it reaches an audience on schedule. Most engines generate a clip and stop. Kling AI is a video generation model rather than a complete video production tool, so it generates clips but does not add voiceover, narration, captions, or music. The creator still has to move that clip into a posting workflow and keep the calendar full.
The loop has to close or the production system remains incomplete. Sozee’s Scheduler connects Instagram, TikTok, X, Facebook, Reddit, and Fanvue per character rather than per account. It supports photos, carousels, reels, and stories, with a caption per platform and a live preview of the real post. Analytics splits what Sozee posted from what the creator posted, so the platform’s contribution becomes measurable rather than assumed. 87.49% of surveyed brands expected to increase influencer marketing budgets in 2026, and the creators who can demonstrate consistent, on-brand output across a full calendar are the ones who capture that spend.
Is There A Free AI Image To Video Generator For Influencers?
Free tiers exist across the category, but every one restricts at least one of export volume, video length, output resolution, commercial licensing, or watermark removal.
- Kling’s free tier tops up daily, covers one to three short generations, caps at 10 seconds, and states generated content is not for commercial use.
- Runway’s free plan grants 125 one-time credits with watermarked output, enough for about two short clips, ever.
- Pika’s free Basic plan is the exception, with 80 video credits a month at 480p and commercial use granted, but the resolution cap still limits it to testing.
Free tools are a legitimate testing ground before committing to a monetized stack. When output goes anywhere near money, locate the sentence granting commercial use before building on it. The commercial-use permission is rarely on the pricing page, as Runway’s grant sits in its help center and HeyGen’s ban sits in Section 4 of its terms.
Frequently Asked Questions
Quick Start: How Do I Generate An AI Influencer Video From A Single Image?
Start with the cleanest source possible: at least 720p resolution, clear subject-to-background separation, a front-facing or three-quarter pose, and no pre-existing motion blur. Prepare the final aspect ratio before generation so a clip for TikTok or Reels is generated vertically rather than cropped after the fact. Describe motion rather than repeating what the model can already see in the image, and give the first generation one main job. For multi-scene projects, expand the single photo into a reference set before animating any clip, so every generation has a consistent identity anchor rather than reconstructing the face from scratch each time.
Quick Answer: Which Engine Should I Pick?
Engine choice depends on archetype and posting cadence. See “Talking-Head And UGC Influencers,” “Fashion And Lifestyle Influencers,” and “Faceless And Aesthetic Accounts” above for detailed tradeoffs and tool picks.
Quick Answer: Are Any Image-To-Video Tools Free?
Several engines offer free tiers with limits on resolution, credits, or commercial use. See “Is There A Free AI Image To Video Generator For Influencers?” above for specific caps and licensing details.
Quick Answer: How Do I Keep The Same AI Character Across Videos?
Consistency comes from locked references and reusable assets. See “How To Keep The Same AI Character Across Multiple Videos” above for the step-by-step workflow and how Sozee maps each step to saved assets.
Conclusion: The Stack Decision
A single good clip loses value when the next clip shows a different face. The engine is rarely the problem; the absence of a consistency system is. Creators monetizing on Instagram or TikTok, micro-influencers delivering sponsorship campaigns, and virtual influencer builders scaling to daily posts all face the same structural gap: impressive individual generations that cannot hold a brand across a month of content.
Sozee is built for creators who are monetizing, not just experimenting. It is the only platform that locks likeness, reuses environments and outfits, animates stills, closes the loop to scheduled posts, and measures the result, all without exporting to five other tools. The brands increasing their influencer budgets, as noted above, are looking for creators who can deliver consistent, on-brand output at scale. The stack decision starts with likeness lock, and every other choice builds on that foundation.
Start Your Consistent Content Stack