
Last updated: September 5, 2026
Key Takeaways
- Generic AI generators often produce inconsistent portraits because each image starts from random noise, which causes identity drift even with identical prompts.
- Training a custom AI model from your own selfies fixes this and lets you create consistent, professional portraits you can build a brand on.
- Quality selfies matter more than quantity: 10–20 sharp, well-lit, varied-angle photos outperform filtered or low-resolution shots for traditional LoRA training.
- Sozee.ai removes the training workflow entirely. Upload just 3 photos and the system fixes your appearance instantly with no technical setup.
- Create consistent AI portraits without the learning curve. Start your free trial
Why Train a Custom AI Model from Selfies?
Generic AI generators usually produce a different face every time, which makes them unusable for a recognizable personal brand. A custom-trained model solves this at the root and gives you practical, everyday benefits.
- Brand consistency: your audience recognizes you across every post, platform, and campaign.
- Reusable content: one trained model generates unlimited portraits for social media, personal branding, and professional photography.
- Time and creative control: you skip reshoots, waiting for golden hour, and scheduling a photographer. A trained model generates unlimited variations at minimal marginal cost, unlike a single professional session that costs hundreds of pounds and yields limited variety.
- Stable identity with flexible styling: change outfits, settings, and expressions while your face remains consistent.
Step 1: Select and Prepare Your Selfies
How Many Selfies Do You Need?
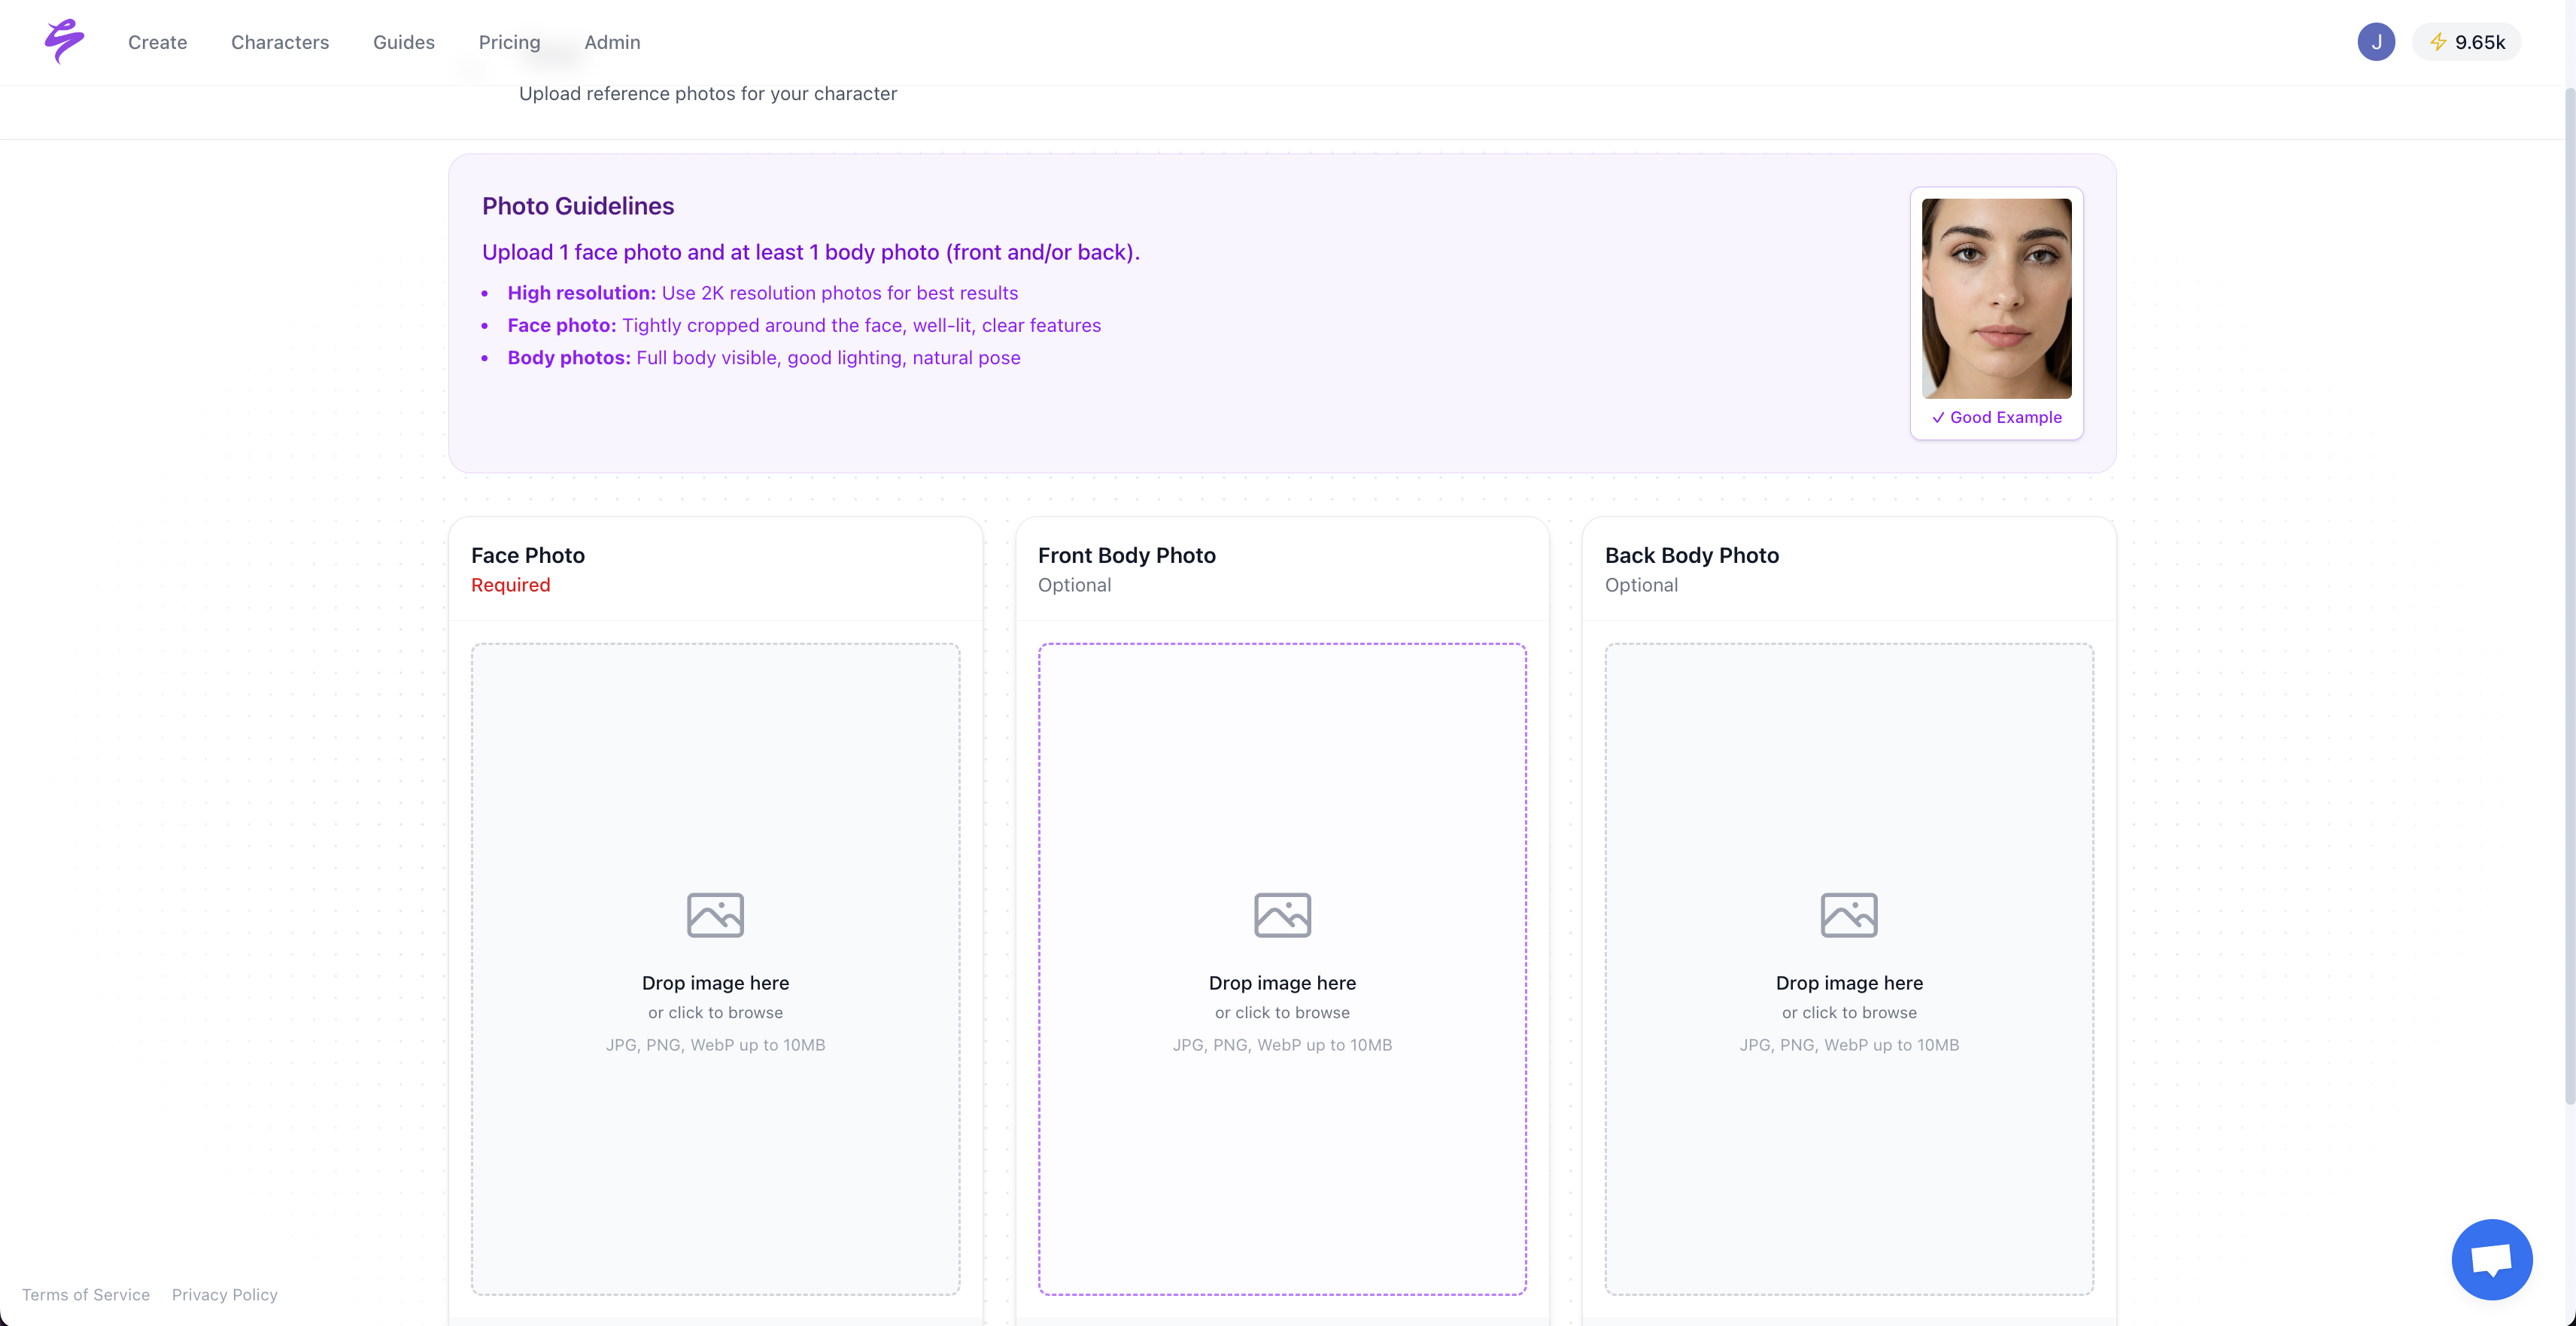
The number of photos you need depends on your platform. For traditional LoRA training, 15 to 30 high-quality images showing the face from various angles, in different lighting conditions, and with varied expressions is a recommended starting point. The community consensus for LoRA training suggests 10 to 20 images depending on rank and training strategy, and more diverse photos give the model a richer understanding of your face. Sozee.ai needs only 3 photos to establish your appearance instantly, with no training step.
Quality beats quantity in every case. One sharp, well-lit, unfiltered selfie consistently outperforms a stack of filtered or close-range shots. A low-quality selfie forces the model to guess at facial details, which leads to eye shape drift, incorrect nose width, and uncanny skin texture.
Do’s and Don’ts for Training Photos
Follow these guidelines so your selfies give the model the clearest possible view of your face.
- Do use well-lit, sharp, front-facing photos with varied angles and expressions.
- Do include different backgrounds and outfits so the model learns your face rather than your wardrobe.
- Do shoot on the rear camera from about one metre away. Front-facing phone cameras use a wide-angle lens that makes the nose appear wider and ears appear further back than they actually are, which teaches the model a distorted face.
- Don’t use blurry, low-resolution, or heavily filtered images. The model learns the distortion.
- Don’t wear sunglasses or hats that obscure your face.
- Don’t use group photos. They confuse the model about which features to learn.
- Don’t use photos older than 6–12 months if your appearance has changed. An outdated selfie causes the model to learn an outdated face.
Preparing Your Dataset
Crop images to focus on the face and shoulders. Training images should generally exceed 512×512 pixels, though the optimal training resolution depends on your platform. Some practitioners train at 512×512 even with 1024×1024 source images to avoid overly coarse outputs. Use a batch tool like Birme or Photoshop to standardize your set to a consistent resolution.
Step 2: Choose a Training Platform
No-Code Platforms for Fast Setup
- Replicate: Simple web interface for training LoRA models. You upload a zip of photos, set a trigger word, and start training. Replicate offers per-second GPU billing and a marketplace of public and custom models via a simple API.
- Getimg.ai: User-friendly pipeline with built-in character training, which suits creators who want a guided setup.
- Sozee.ai: The outlier with no training at all. Upload as few as 3 photos and the system fixes your appearance instantly. You avoid dealing with zip files, learning rates, or waiting. Photo Control then lets you set setting, outfit, shot style, expression, and objects while your face stays consistent across every generation.
Local Training for Full Control
Tools like Kohya_ss give full control but require a GPU with sufficient VRAM, Python, and command-line comfort. Training a LoRA on an RTX 4090 takes roughly 2.5–3 hours for 2,000 steps on a 30-image dataset; an RTX 3080 takes approximately 4–5 hours. The result is a 50–500MB adapter file that loads into any compatible ComfyUI or Forge workflow. You gain an offline, ownable brand asset.
Platform Comparison at a Glance
| Platform | Training Time | Setup Required |
|---|---|---|
| Sozee.ai | Instant (no training) | None, upload 3+ photos |
| Replicate | 10–30 minutes | Zip file and trigger word |
| Getimg.ai | 10–30 minutes | Guided web interface |
| Kohya_ss (local) | 2.5–5+ hours | GPU, Python, config files |
Step 3: Set Up Your Training with Trigger Words and Captions
What a Trigger Word Does in Your Model
A trigger word is a unique token, like ohwx, that you train into the model to summon your likeness in prompts. It acts like a password. When you include it in a prompt, it signals the AI to apply the trained data. A good trigger word is a neutral 6–12 character string with low existing meaning and low collision risk. Examples include ohwxperson, nvychar, or zvpack.
Follow these best practices when choosing and using your trigger word:
- Keep it short, low-conflict, and consistent across every caption.
- Avoid descriptive keywords as trigger words. Training
redheadas an identity handle ties the identity to red hair and bleeds into unrelated prompts. - Pair the trigger word with one accurate class word, such as
ohwxperson woman, to anchor the broad category while the unique token identifies the specific concept. - Put the trigger word in the same position and form in all intended captions, preserving spelling, capitalization, and punctuation.
Captions and Training Parameters
Caption each image with your trigger word plus a class word, for example ohwx woman, and describe variable elements like clothing, pose, and background. A recommended starting configuration is 1,000 steps, learning rate 0.0001, with a default caption like “a photo of sks subject”. Run this first, then adjust based on results. For portrait and character LoRAs, community guides typically recommend starting with a learning rate around 1e-4, a batch size of 1–2 (with 1 for lower VRAM), roughly 1,000–2,000 training steps (though some guides extend to 2,500–3,000), and a network rank of 16–32 (with some recommending up to 64 for more detail). Because these values vary by platform, start with your platform’s recommended defaults, which are usually well-tuned for its specific model.
Step 4: Generate Consistent Portraits with Smart Prompting
Prompt Engineering for Consistency
Include your trigger word in every prompt, for example ohwx woman, portrait, soft window lighting. Structure prompts in this order: subject first, then action or state, environment, lighting, camera angle and lens, and finally style or artistic medium, because diffusion models weight earlier tokens more heavily. Keep descriptors consistent across generations and use negative prompts to block artifacts, such as blurry, distorted, extra fingers, plastic skin, deformed, bad anatomy.
LoRA Strength and Seeds
Start with a LoRA weight of 0.6–0.8 and adjust, because using a LoRA at full weight (1.0) often produces over-stylized results. Too low and the output will not resemble you. Too high and the model overfits. Lock the seed for a series to maintain composition and color consistency. Sozee.ai’s Photo Control automates these controls, so you set expression, outfit, setting, and more while your face remains consistent across every frame. Even with careful prompting, you may still run into consistency problems, so it helps to know how to diagnose and fix them.
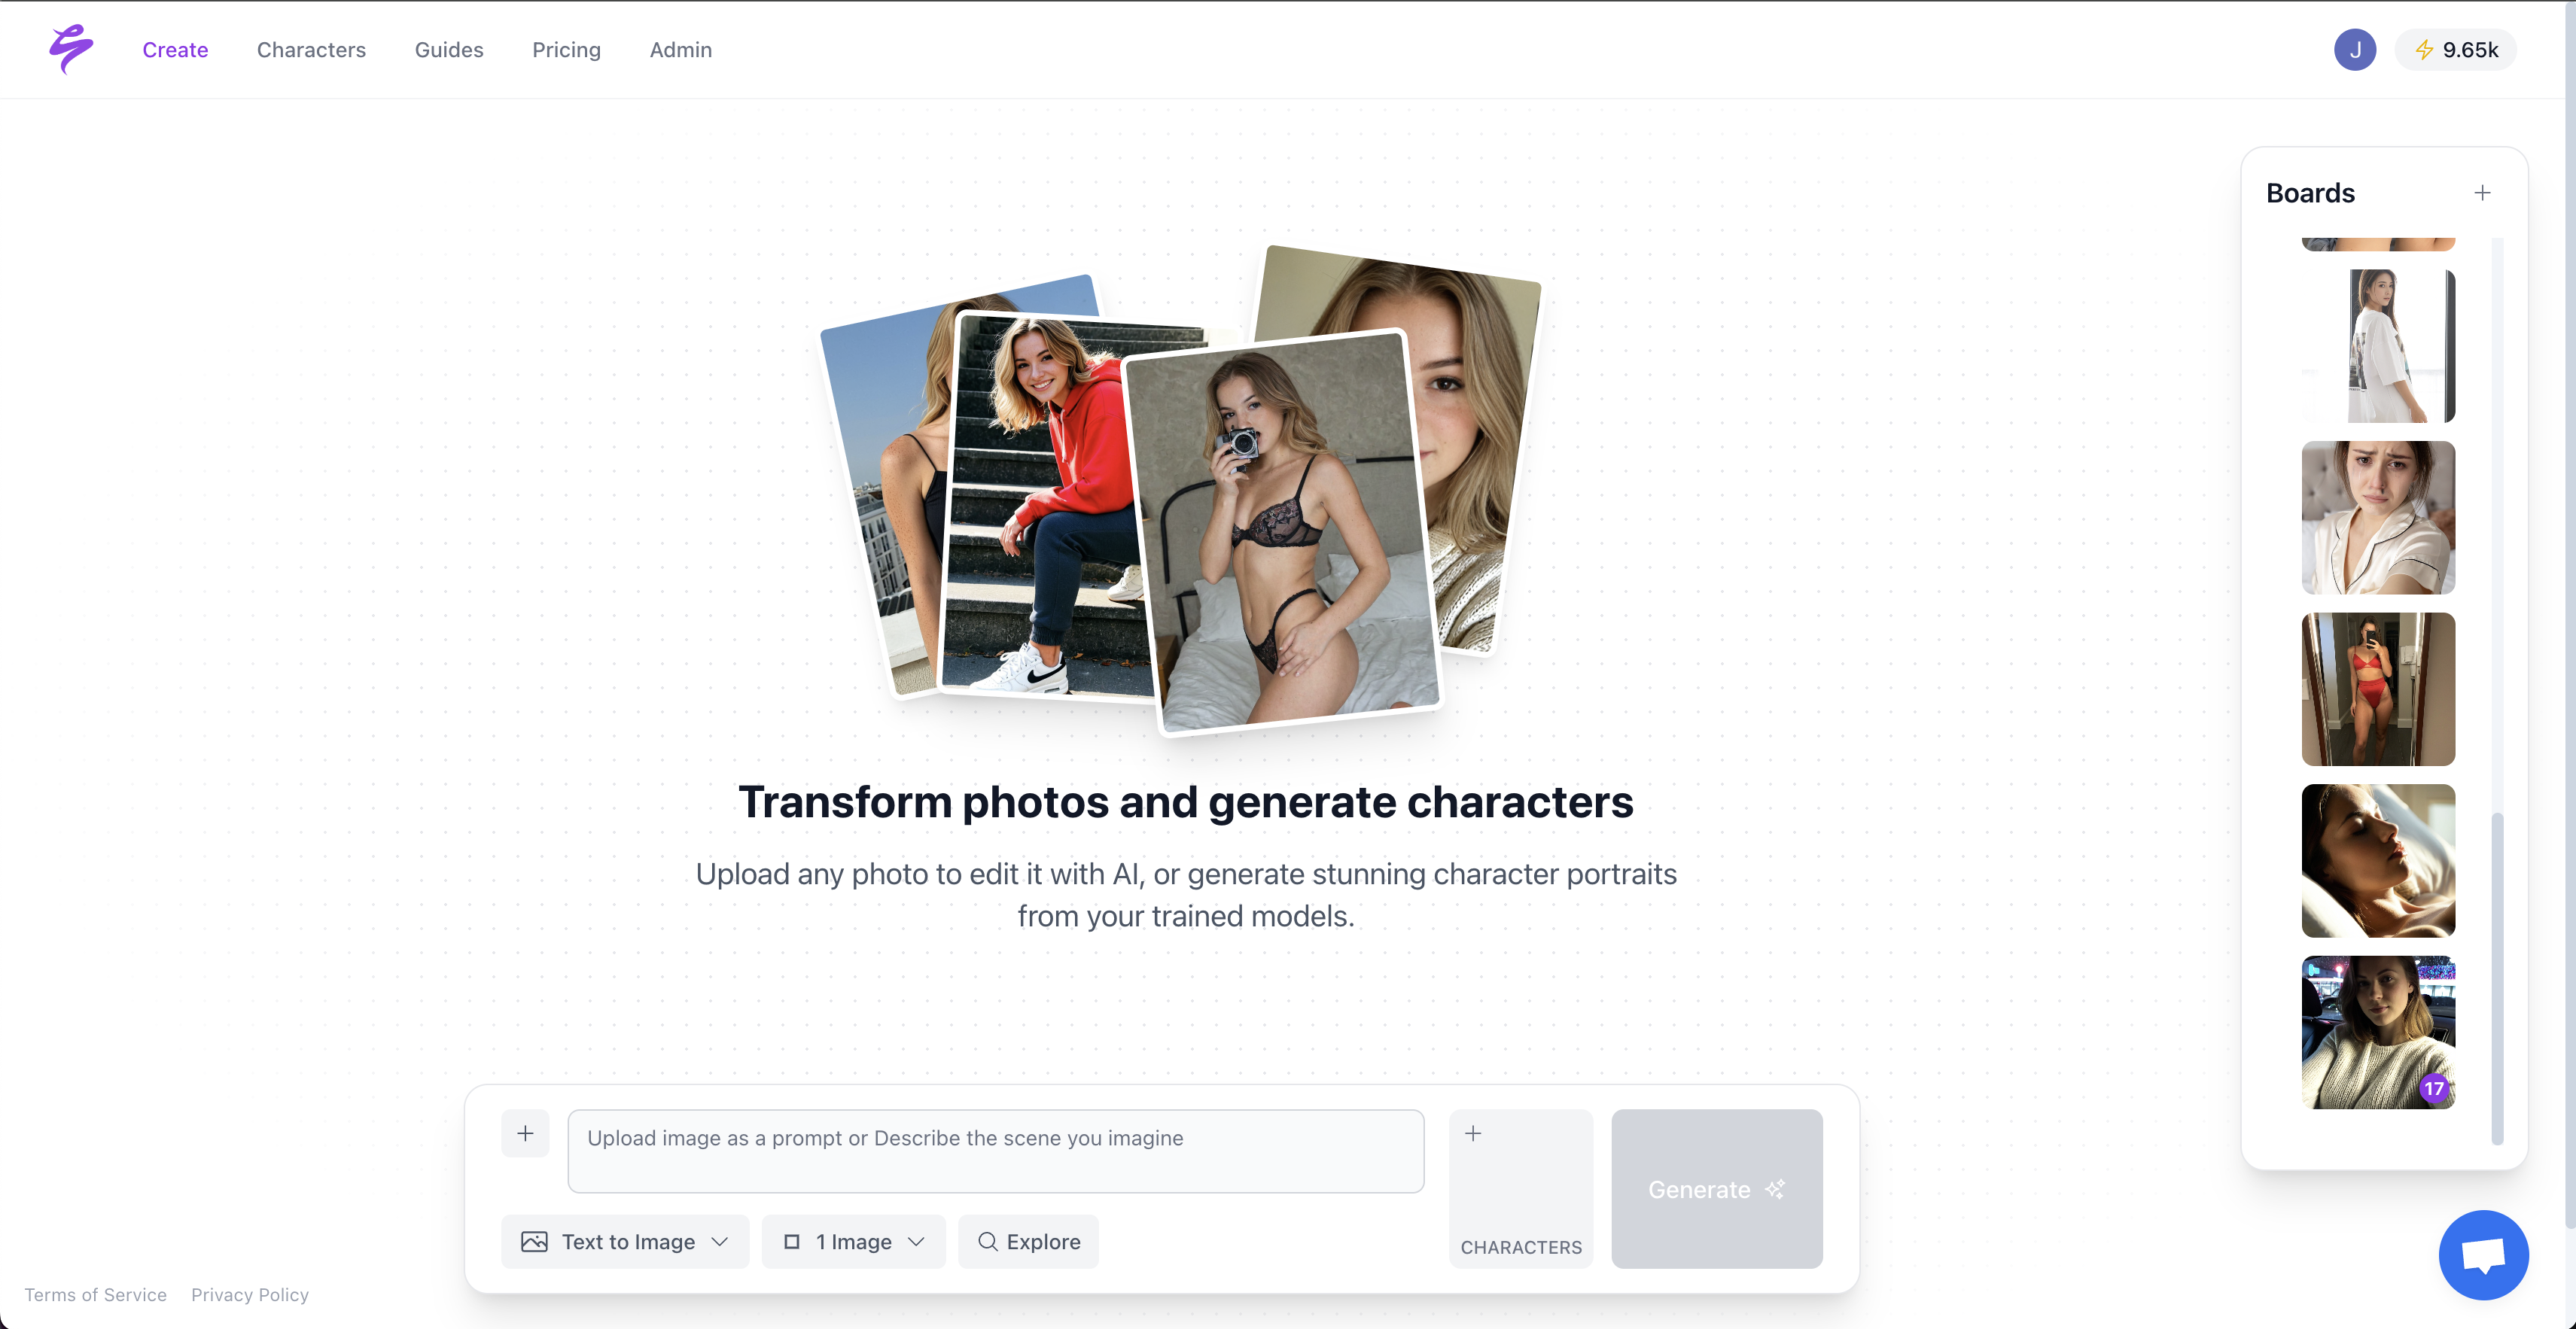
Start creating now with Sozee.ai, with no training or technical setup required.
Step 5: Troubleshoot Consistency Issues
Why Faces Change Between Generations
Identity drift is the most common consistency failure and is hardest to fix with prompting alone because models make thousands of micro-decisions about facial structure that prompts cannot fully constrain. Common root causes include insufficient training data, inconsistent captions, low LoRA strength, or switching base models mid-project.
How to Fix Inconsistent AI Portraits
- Add more diverse photos to your dataset. Varied angles, expressions, and lighting give the model a richer understanding of your face.
- Standardize captions across all training images. Mismatches between captions and image content cause the trained LoRA to ignore prompt instructions for those attributes.
- Increase LoRA strength incrementally (0.6 → 0.8 → 1.0) and test at each step.
- Use a fixed seed for a series to keep composition stable.
- Keep positive prompts focused at 40–75 tokens. Adding more detail beyond that point dilutes the weight of every other token and produces confused results.
- Switch to a platform with built-in likeness control such as Sozee.ai, which removes the training step entirely.
Step 6: Advanced Tips for Professional Results
The open-weights image-model landscape in 2026 is led by newer FLUX releases from Black Forest Labs, while SDXL remains widely used for its mature LoRA ecosystem. Combining your face LoRA with style LoRAs or checkpoints unlocks specific aesthetics. Use inpainting to fix small imperfections rather than regenerating the whole image. For inpainting, mid denoising strength (0.4–0.6) is ideal for fixing localized issues, because it keeps the general shape but replaces pixels with cleaner ones.
Sozee.ai extends this further. Photo Shoot generates a coherent set of up to 10 images from a single frame. Identity, outfit, and environment stay fixed, while angle, pose, and expression vary. Live Mode renders your character onto your camera feed in real time. You act, your character performs, and you capture the frames you want.
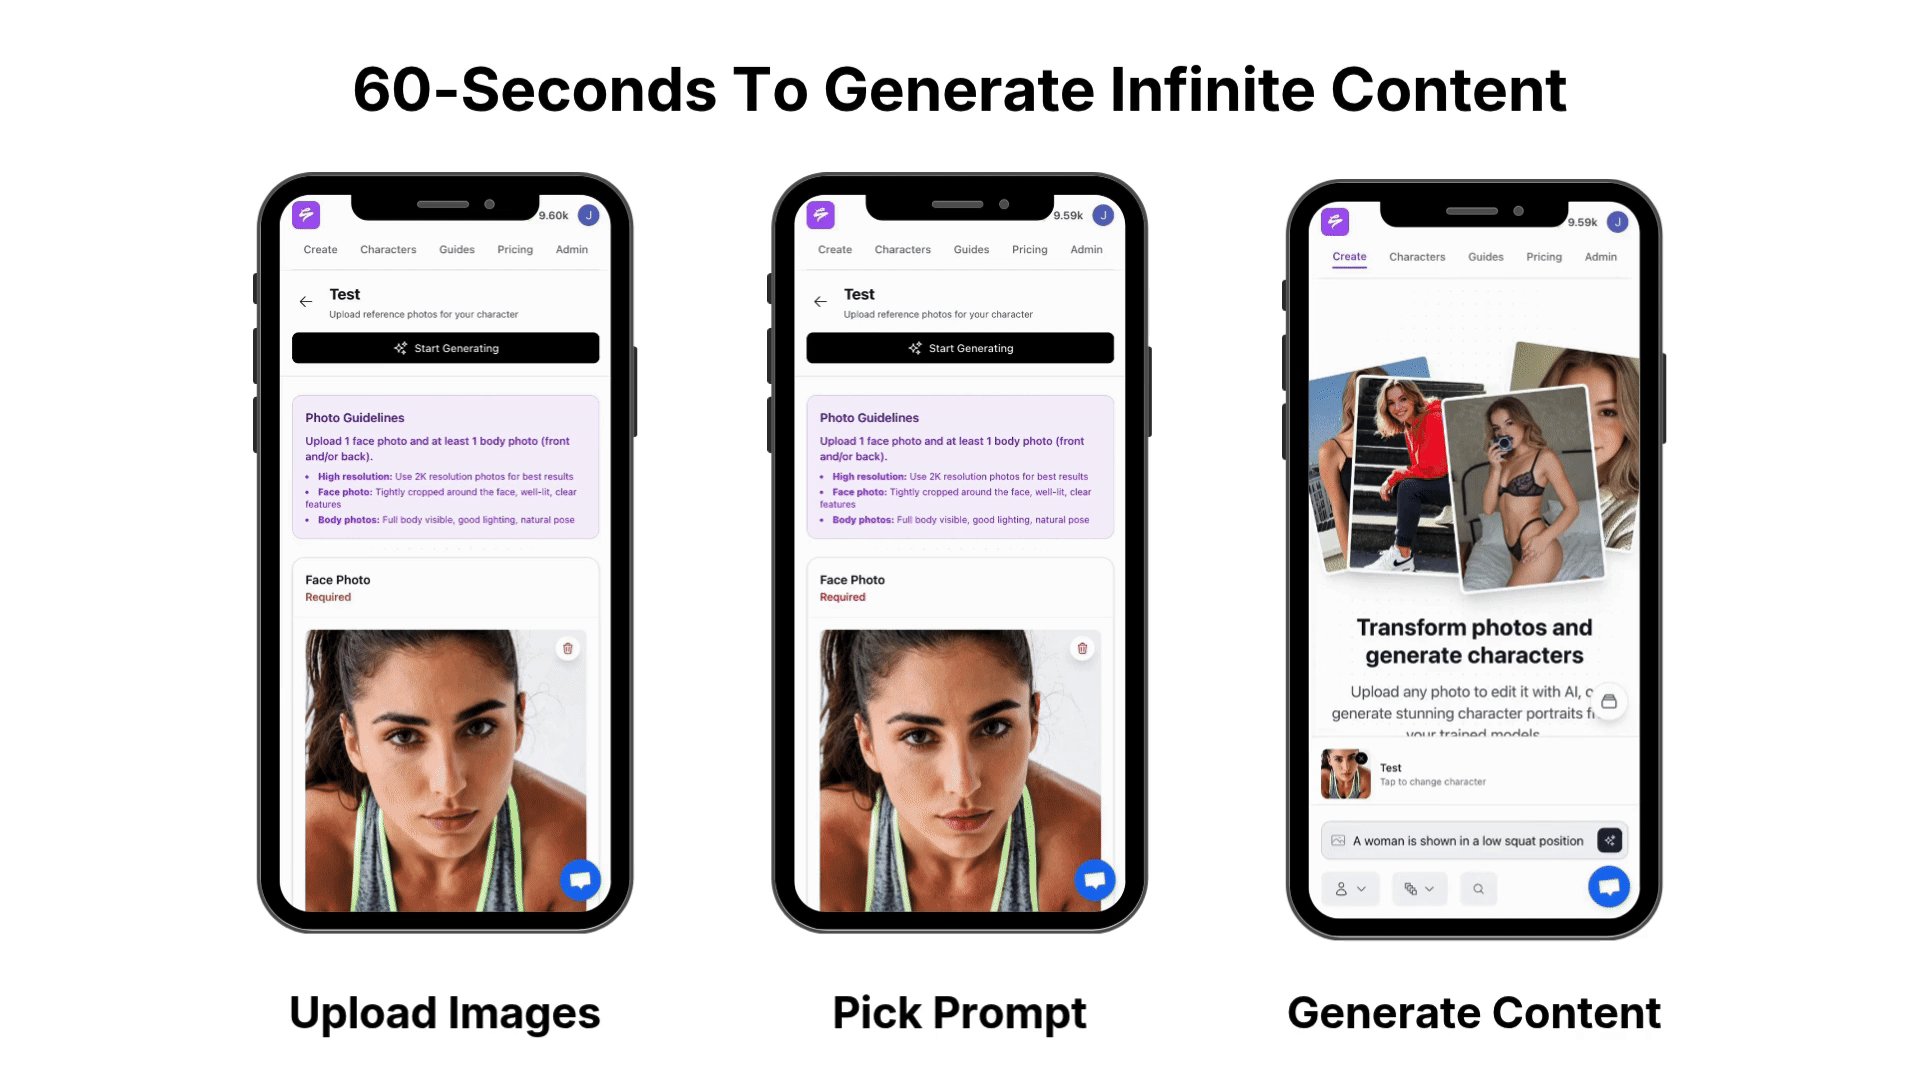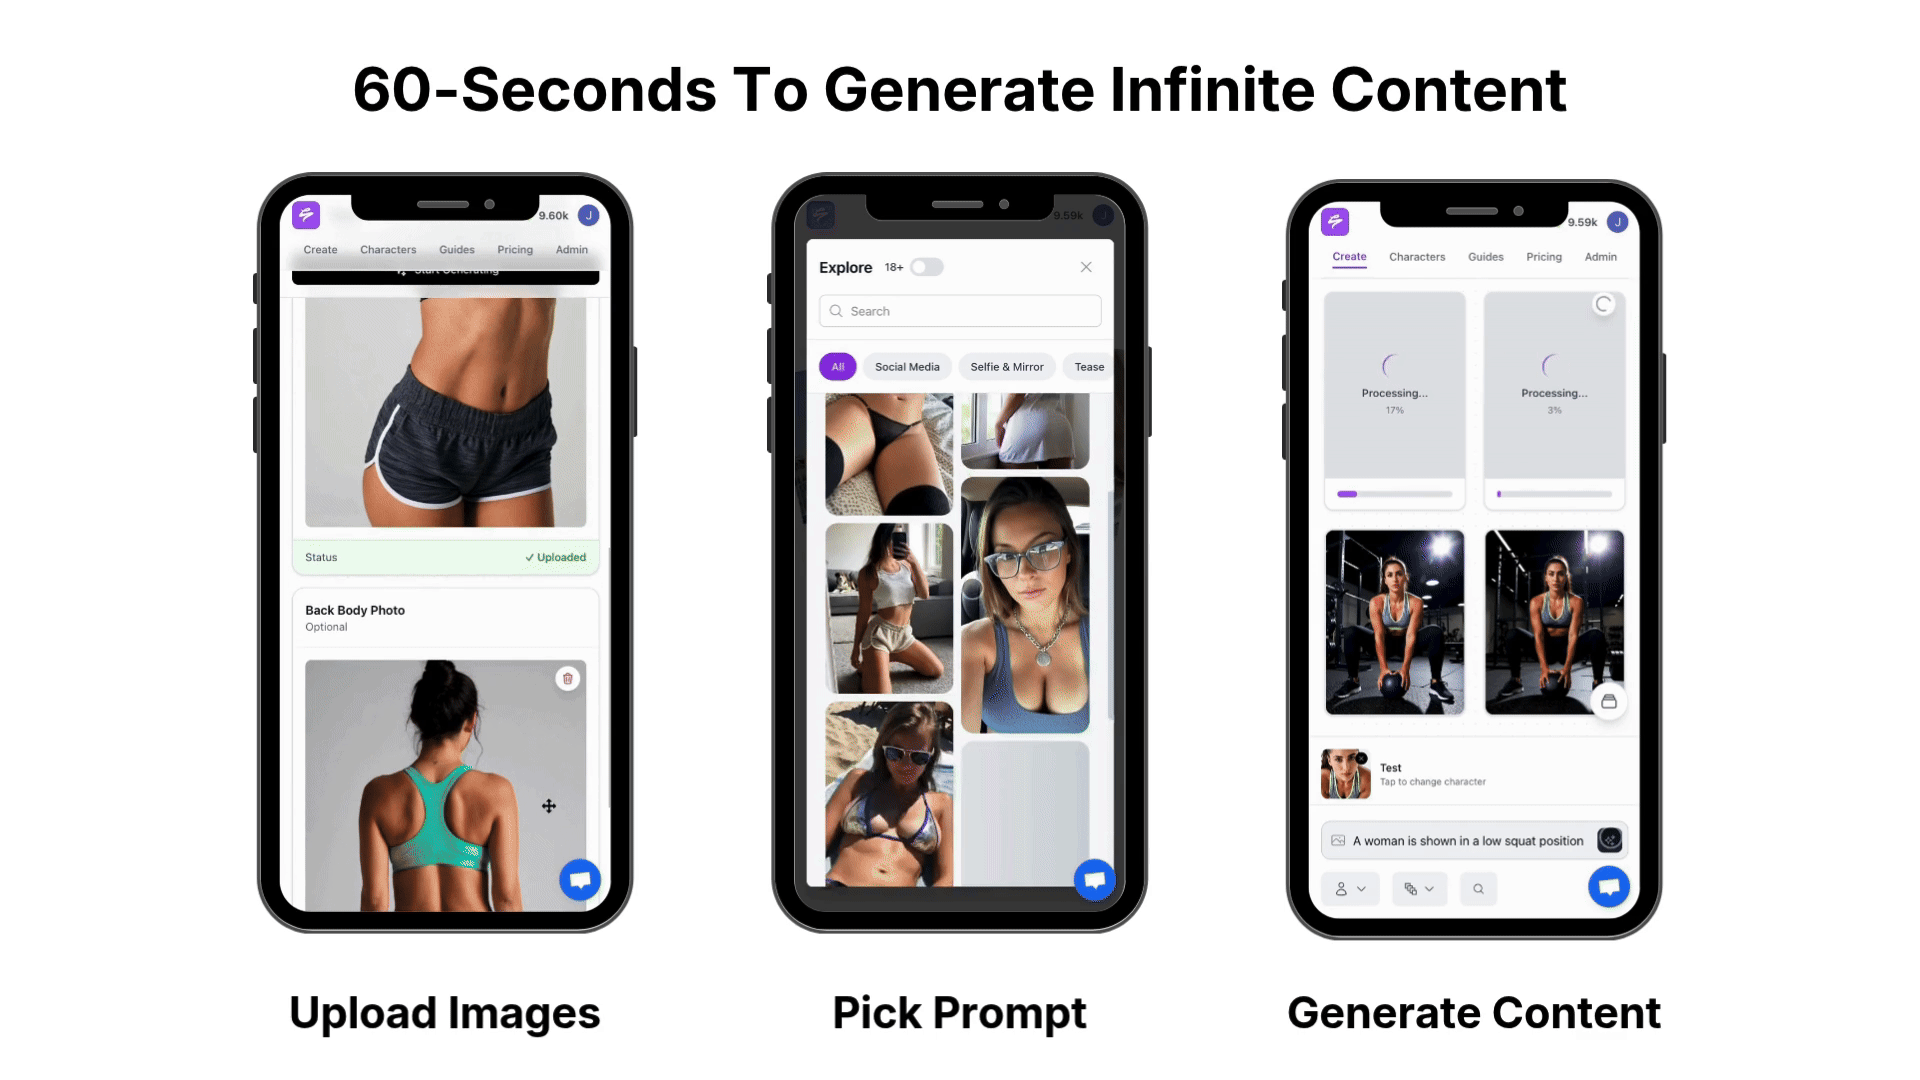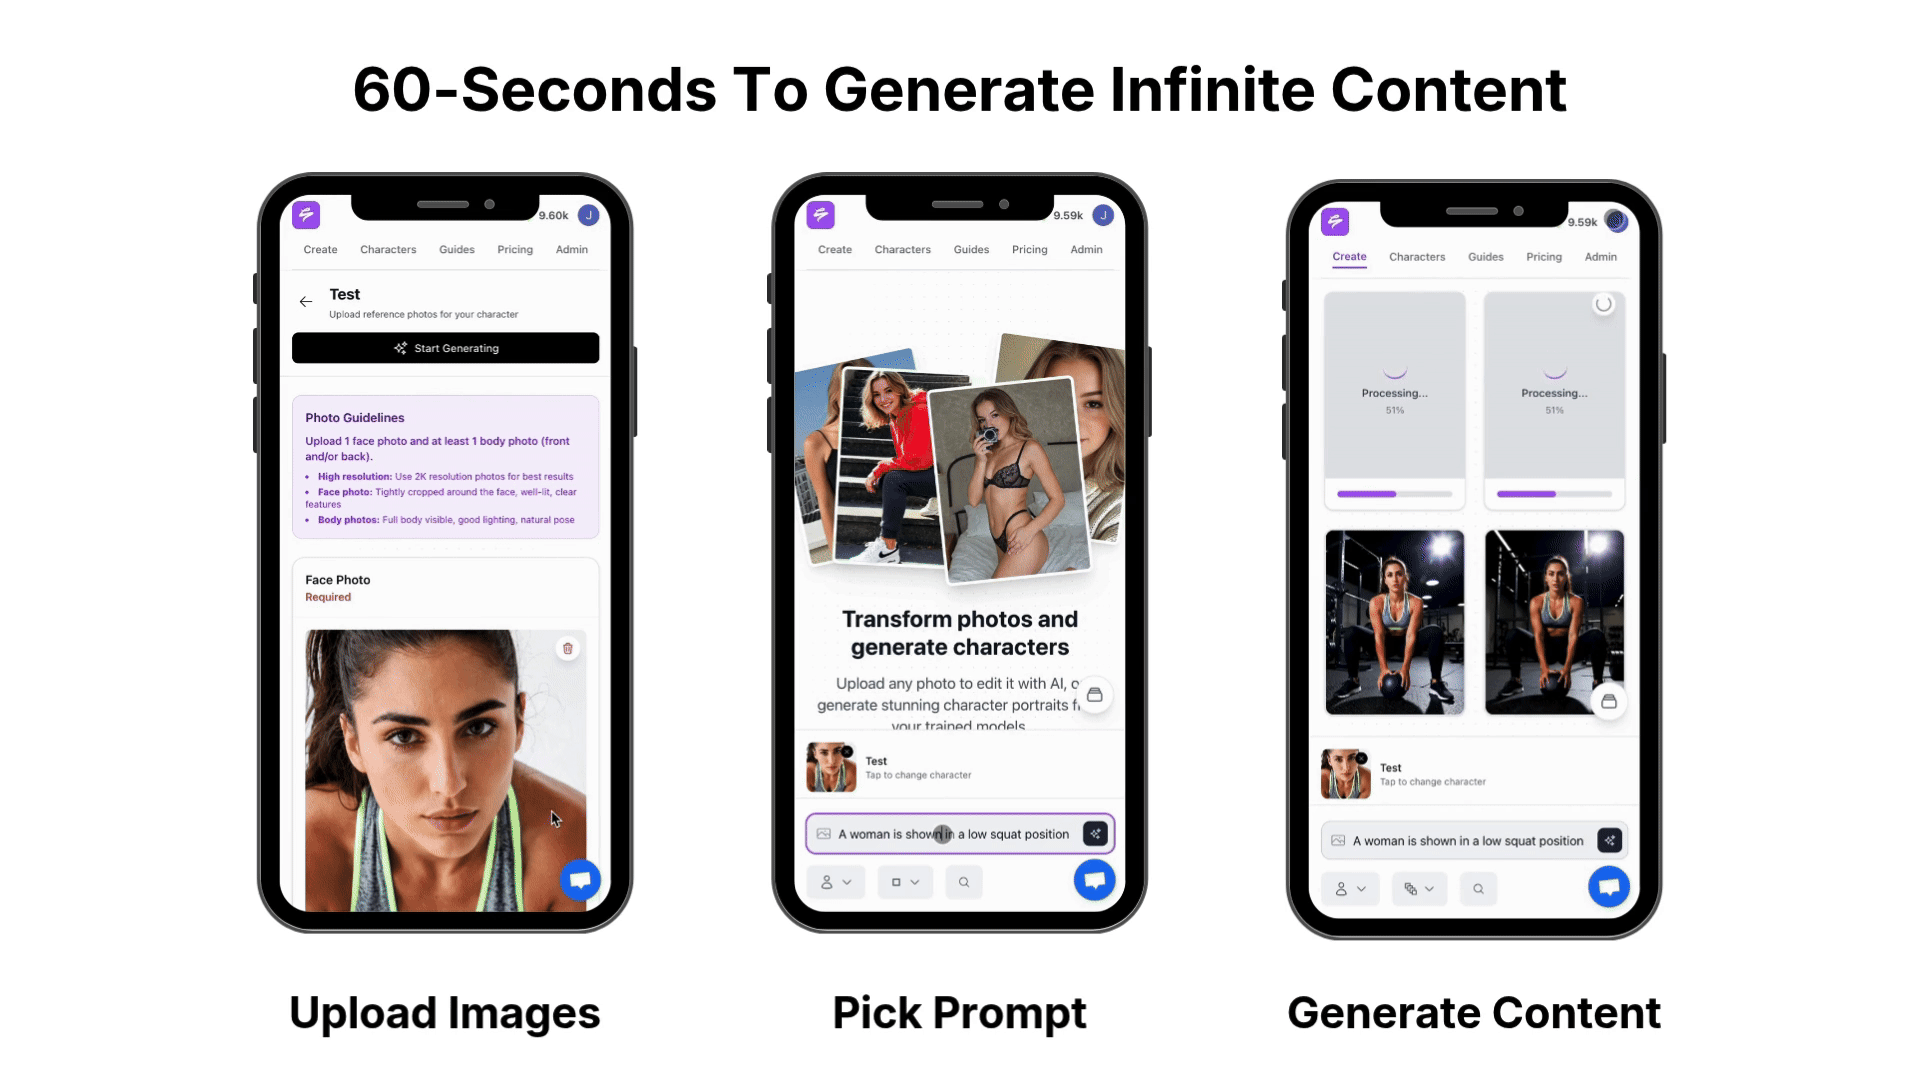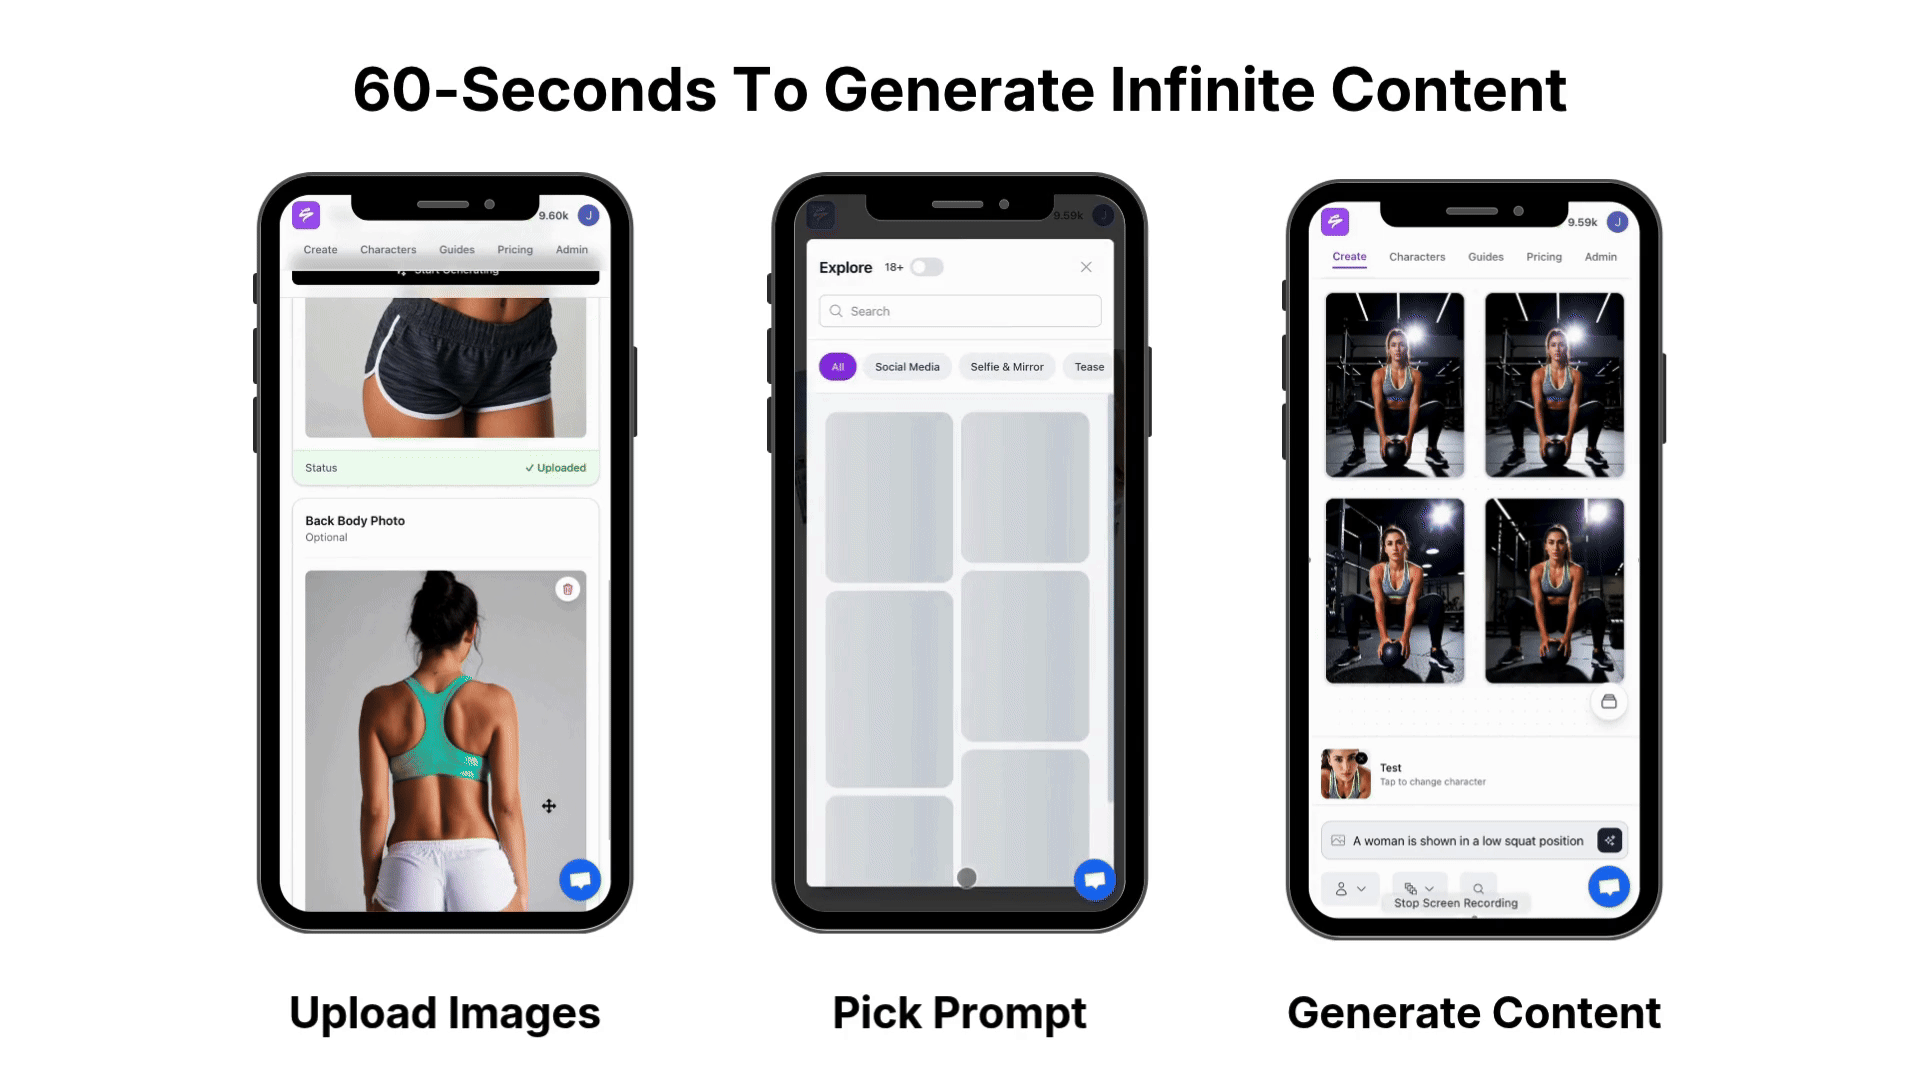
Why Sozee.ai Is the Best Solution for Creators Who Want Consistent Portraits
As the steps above show, traditional LoRA training works, yet it is technical, time-consuming, and requires constant tweaking. The workflow of zip files, learning rates, trigger word configuration, and parameter tuning creates a significant barrier for creators who want results rather than a course in machine learning.
Sozee.ai removes the entire training step. You upload as few as 3 photos, and the system keeps your appearance stable across every generation. Photo Control gives you five deliberate dimensions, Setting, Outfit, Shot style, Expression, and Object, which replaces prompt gambling with a director’s panel. Every setting, outfit, and object you build becomes a reusable asset that makes the next shoot faster. The Scheduler connects Instagram, TikTok, X, Facebook, Reddit, and Fanvue so you can publish and measure from the same platform. Analytics split what Sozee posted from what you posted, which shows exactly what works.
For agencies, Teams and isolated workspaces mean one login manages an entire roster. For micro-influencers, dropping a sponsor’s product into the Object slot and shooting it across multiple settings, outfits, and expressions delivers a full campaign in an afternoon.
Get started free and create your first consistent AI portrait today.
Conclusion: Consistent AI Portraits Without the Headache
The workflow for consistent AI portrait photography follows a clear path. Prepare 10–20 quality selfies from varied angles with clean lighting. Choose a platform that matches your technical comfort. Train with a carefully chosen trigger word and accurate captions, then generate with consistent prompts and a locked seed. Traditional LoRA training is powerful but demanding, because it requires the right hardware, the right parameters, and ongoing iteration.
Sozee.ai delivers the same reliable identity without any training. You upload, direct, and create. Your face remains steady in every frame, every set, every week, and you never touch a config file.
Start creating now: sign up for Sozee.ai free and see your face stay consistent in every frame.
Frequently Asked Questions
How many selfies do I need to train an AI model?
For traditional LoRA training, 10–20 high-quality, well-lit photos from varied angles form a solid starting point. More photos, up to 30 or 50, can improve accuracy, but returns diminish beyond that range. Quality consistently matters more than quantity. One sharp, unfiltered, front-facing photo taken on the rear camera outperforms a stack of filtered or arm’s-length shots. As noted earlier, Sozee.ai requires only 3 photos and skips the training step entirely.
What is a LoRA model?
LoRA (Low-Rank Adaptation) is a lightweight fine-tuning method originally developed by Microsoft Research that adapts a base image model, such as FLUX or SDXL, to a specific face or concept by training a small set of additional weights rather than modifying the entire model. The result is a compact adapter file, typically 2MB to 300MB, that you load alongside the base model at inference time to generate images of yourself. LoRA reduces the number of trainable parameters by a factor of roughly 10,000 compared to full fine-tuning, which makes it practical on consumer hardware. The “rank” setting controls the trade-off between adapter size and expressiveness. Lower ranks are compact but may miss subtle identity details, while higher ranks approach the fidelity of full fine-tuning methods like DreamBooth.
Can I train an AI model for free?
Some platforms offer free tiers or trial credits, yet reliable training typically costs a few dollars per run on managed platforms. Local training on your own GPU costs nothing per run after hardware, but requires a capable GPU, such as an RTX 4090 or equivalent for comfortable FLUX LoRA training, plus the time investment to configure and run the workflow. Sozee.ai offers a free tier to start creating immediately, with no training cost and no hardware requirement.
How do I keep my AI portraits consistent?
Use your trigger word in every prompt, maintain consistent descriptors for style and lighting across generations, lock your seed for a series, and keep LoRA strength in the 0.6–0.8 range. Standardize captions across all training images so the model learns which features are fixed and which are variable. Avoid switching base models mid-project, because this can disrupt the model’s learned behavior. For the most reliable consistency without manual management, platforms like Sozee.ai automate likeness control entirely, so your face stays fixed while you change every other dimension of the shoot.
Is Sozee.ai better than training my own LoRA model?
For creators who want consistent, professional portraits without learning technical tools, Sozee.ai is usually the better fit. Traditional LoRA training delivers strong results but requires dataset preparation, trigger word configuration, parameter tuning, and ongoing troubleshooting, which creates a meaningful time and skill investment. Sozee.ai removes the training step. You upload as few as 3 photos, and the system stabilizes your appearance instantly. Photo Control replaces prompt engineering with five deliberate dimensions, Setting, Outfit, Shot style, Expression, and Object, so every generation becomes a decision rather than a gamble. The platform also includes Photo Shoot for coherent multi-image sets, Live Mode for real-time character performance, a built-in Scheduler for multi-platform publishing, and Analytics to measure what works. For creators whose goal is consistent content at scale rather than AI model training as a skill, Sozee.ai provides the more direct path.