
Last updated: September 23, 2026
Key Takeaways
- Training a custom LoRA uses 10–30 high-quality, varied images plus a rare trigger word, and the full workflow takes several hours including dataset prep, captioning, training, and validation.
- Hardware choice sets your path: an NVIDIA GPU with 12GB or more VRAM unlocks free local one-click apps, while no GPU points you to cloud trainers like Civitai or Tensor.Art.
- Strong dataset curation matters most, so remove watermarks, duplicates, and repeated backgrounds, and keep angles, lighting, and framing varied to prevent identity drift or background leakage.
- Core training settings include picking SDXL or FLUX, then setting repeats (2–15), epochs (5–20), learning rate (around 1e-4), and rank/alpha values, with SDXL usually producing smaller files and faster runs than FLUX.
- Sozee provides consistent character generation without any training and uses as few as three photos to create an instant, hyper-realistic likeness across every output.
Lock In Your Consistent Character With Sozee
The Hardware Decision Tree For LoRA Training
If you do, use a local one-click app. Two practical options for local one-click LoRA training are Ostris/AI-Toolkit, available via the Pinokio one-click installer for Windows, and FluxGym. Both tools are free and open-source. Note that FluxGym does not support FLUX.2 [dev] or FLUX.2 [klein] as of 2026, so FLUX.2 [dev] and FLUX.2 [klein] architectures need a compatible trainer such as ostris/ai-toolkit or a fal.ai endpoint.
If you do not, use a cloud trainer. Two no-hardware options for LoRA training are Civitai’s On-Site Trainer and Tensor.Art, along with other browser-based trainers.
The VRAM requirements vary by base model. SDXL trains at a 12GB minimum, while FLUX.1 and FLUX.2 prefer 16GB minimum and 24GB recommended, dropping to roughly 9–13GB with NF4 or int4 quantization. Many beginners quit at this fork because no guide states it clearly. You now have the answer before opening a single settings screen.
Step 1: Prepare Your Dataset
For a character or likeness LoRA, 15–30 well-varied images form a practical sweet spot; fewer than 10 usually under-trains the identity, and more than 80 for a simple subject risks the model memorizing backgrounds instead of learning the subject. Style LoRAs typically use 30–80 images.
Variety beats volume. Twenty headshots can provide less useful coverage than 12 images split across close, medium, full-body, front, side, and three-quarter views, because a LoRA learns correlations rather than a checklist. Aim to cover at least four framing buckets: face, bust, body, and back.
Clean your dataset before training:
- Watermarks and text overlays
- Other people in the frame
- Heavy compression artifacts or motion blur
- Near-duplicate frames, since two frames of the same shot teach nothing and overweight that look
- Repeated backgrounds, because whatever repeats gets baked into the LoRA, so a repeated background wall becomes part of “the person”
More images make a LoRA worse when they add identity drift, low-quality evidence, duplicate weighting from near-identical frames, or conflicting style. That is why dataset curation matters more than dataset size, so fix the data before you train.
Step 2: Choose Your Base Model And Method
With your dataset ready, the next decision shapes every setting that follows: which base model you train on.
SDXL Vs. FLUX: Your First Major Choice
SDXL produces faster runs and smaller files, usually 20–80MB, uses rank 32–64, and trains in 1,000–3,000 steps. FLUX produces stronger realism and larger files, often 100–400MB at rank 16–32, and trains in 1,500–2,500 steps. LoRAs are architecture-specific, so an SDXL LoRA will not load against FLUX, and a FLUX LoRA will not load against SDXL. Decide on your base model before touching any other setting.
Route to your trainer based on the hardware decision tree above. Cloud trainers handle both architectures. Local apps have architecture constraints, so check the documentation for your chosen tool before uploading your dataset.
Step 3: Caption Your Images And Pick A Trigger Word
Captioning means writing one text file per image that describes what appears in the frame, covering everything except the subject’s inherent identity. The trigger word is a rare, invented token placed at the start of every caption that switches the LoRA on at generation time.
Follow the golden rule: never describe what the person is, and instead describe everything else. Correct: myTrigger, sitting at a café table, warm afternoon light, denim jacket. Counterproductive: myTrigger, a woman with long blonde hair and blue eyes, smiling. The second caption teaches the LoRA to lock in those features rather than learn them as separable attributes.
Caption style depends on your base model. FLUX.1, FLUX.2 Klein, and other prose-native models prefer natural-language sentences, while SDXL booru-native checkpoints prefer comma-separated tag lists. Auto-captioning tools help here. WD Tagger outputs tag lists. JoyCaption and Qwen3-VL output natural-language sentences, and Civitai’s 2026 training guidance for FLUX.2 recommends JoyCaption specifically.
Rare tokens matter because common words like “woman” or “style” already have strong associations the LoRA must fight. Use tokens like ohwx, sks_person, or zxq_style, which do not exist in the model’s vocabulary.
Step 4: Configure The Settings
These are the actual values that most guides bury in jargon or skip entirely.
- Base model: SDXL or FLUX.1 or FLUX.2, or FLUX.2 Klein 4B for a 24GB card
- Trigger word: the rare token from Step 3, placed at the start of every caption
- Repeats: how many times each image appears per epoch. A range of 2–15 works in practice, and higher repeats let you use fewer epochs.
- Epochs: full passes through the dataset. A range of 5–20 makes a reasonable first run.
- Learning rate: around 1e-4 (0.0001) for both SDXL and FLUX, with FLUX more sensitive, so 5e-5 works safer for Klein 4B.
- Rank/alpha: Common rank and alpha pairs include FLUX 16/16 and SDXL 32/32, and some guides recommend SDXL 32/16, where alpha equals rank divided by two. When alpha equals rank, the scaling factor stays neutral at 1.0.
- Steps: 1,000–3,000 for SDXL and 1,500–2,500 for FLUX. A 20-image character LoRA on FLUX.2 at rank 16 with 2,000 steps gives a sensible starting point.
- Checkpoint frequency: save every 250 steps instead of only at the end. Black Forest Labs’ FLUX.2 Klein LoRA guide recommends checkpointing every 250 steps and picking the best checkpoint by eye rather than assuming the final step works best.
Step 5: Run The Training And Find Your File
Click Start Training. Cloud runs finish in 10–45 minutes, while local runs take 45 minutes to a few hours depending on GPU and step count.
The finished file uses the .safetensors format. It lands in your trainer’s output folder or appears as a download on the cloud platform’s dashboard. SDXL LoRAs at rank 32–64 typically range from 20–80MB, while FLUX LoRAs at rank 16–32 typically range from 100–400MB.
Step 6: Test And Troubleshoot
Start LoRA strength at 0.8. Test 0.6, 0.8, and 1.0 under identical prompt, seed, sampler, and image size. Likeness LoRAs often look more natural at 0.6–0.8, because full strength can push skin texture or facial proportions into an over-processed look.
Use these plain-language failure modes and fixes:
- “It looks burnt” (overcooked). Too many steps or a learning rate set too high cause this. Drop to a checkpoint saved 500 steps earlier, or lower learning rate to 5e-5 and retrain.
- “The face is baked in” (overfitting). The LoRA only recognizes training-set poses and scenes. Lower strength to 0.6, or retrain with more varied backgrounds.
- “It ignores my trigger word.” The trigger may be missing from the prompt, or captions may be too generic. Confirm the trigger appears in every caption and in your test prompt. If adding the trigger makes no noticeable difference, the LoRA may have been trained with caption dropout and may not require one.
Run a bleed check by generating a prompt that excludes the trigger entirely, such as “a portrait of a woman smiling,” to confirm the LoRA does not leak into unrelated generations. A modl.run character LoRA guide recommends two hardcoded bleed-check prompts that exclude the trigger word to detect whether the LoRA leaks into unrelated prompts.
Trainer Comparison: Civitai Vs. Tensor.Art Vs. Local One-Click App
Now that you know the full workflow, this comparison shows how the three main trainer options differ on base model support, cost per run, and hardware needs.
| Trainer | Base Models Supported | Cost Per Run | Hardware Required |
|---|---|---|---|
| Civitai On-Site Trainer | SD 1.5, SDXL, Flux, and Flux.2 Klein | From about 500 Buzz, roughly $0.50 | None (browser) |
| Tensor.Art | SD 1.5, SDXL, and FLUX, plus other cutting-edge base models such as Stable Diffusion 3, HunYuan DiT, and Kolors | Free tier, up to 100 images per run | None (browser) |
| FluxGym / AI Toolkit (local) | AI Toolkit (local) supports SDXL, FLUX.1, and FLUX.2 Klein, while FluxGym supports SDXL and FLUX.1 but not FLUX.2 bases | Free | NVIDIA GPU with 12GB or more VRAM |
Image Counts At A Glance
As covered in Step 1, 15–30 varied images form the sweet spot for a character or likeness LoRA, while style LoRAs usually sit in the 30–80 image range. Use this as a quick reference when planning your dataset.
Typical LoRA Training Time
A cloud run usually finishes in 10–45 minutes, and a local run on a 24GB card takes 45 minutes to a few hours depending on step count and dataset size. Budget 4–6 hours of total elapsed time for a first LoRA once you include dataset selection, cropping, captioning, and validation, because the training run itself is the cheap part.
LoRA Training Cost Overview
Cloud training ranges from roughly $0.50 for an SDXL job on Civitai’s on-site trainer to about $2–$8 for a FLUX run on a per-step endpoint. When you already own the GPU, local LoRA training stays effectively free apart from electricity, with marginal power cost around $0.08 per hour or roughly $0.40 per run. Plan for 2–3 iterations to tune rank, learning rate, and dataset composition, and expect a fully dialed-in LoRA to land in the $5–$15 range on a single consumer GPU.
Free LoRA Training Options
Tensor.Art includes LoRA training on its free tier and allows free accounts to train on up to 100 images per run. On local hardware, FluxGym and AI Toolkit are free and open-source if you own an NVIDIA GPU with 12GB or more VRAM. Civitai’s on-site trainer uses paid credits and starts at around 500 Buzz, roughly $0.50.
Recommended Learning Rates In Practice
Use 1e-4 (0.0001) as the standard starting point for both SDXL and FLUX. If the result looks overcooked, with distorted outputs and a trigger word that overpowers everything, drop to 5e-5 and pull an earlier checkpoint. If the result looks undercooked after 2,000 steps, with weak resemblance and little trigger response, raise to 1.5e-4. FLUX reacts more strongly to learning rate than SDXL, and anything above 5e-5 on FLUX.2 Klein 4B can produce distorted outputs, so treat 5e-5 as the safe ceiling for that architecture on a first run.
Common Pitfalls And Pro Tips
- Contradictory forum settings. Most forum configs describe someone else’s working setup rather than a universal optimum. Change one variable at a time.
- Overcooked vs. undercooked. Overcooked outputs look distorted, the trigger overpowers everything, and every result resembles one training image. Undercooked outputs show weak resemblance and little trigger response. Fix overcooked runs by using an earlier checkpoint, and fix undercooked runs with more steps or a higher rank, rather than more images.
- Background leakage. If 15 of your 20 training images show the same room, the LoRA learns the room along with the character. Vary backgrounds deliberately.
- The wasted weekend. Most failed LoRAs stem from dataset or caption problems rather than hyperparameter issues, so fix the data before you retrain.
The Honest Alternative For A Single Consistent Character
A trained LoRA works best for a reusable style, a brand asset, or a narrow range of prompts you will run hundreds of times. For the same person in every frame, every set, and every week, a full LoRA often adds unnecessary overhead.
Training a LoRA makes sense when you plan to generate hundreds of shots and when drift becomes expensive to fix manually, while most projects manage with a single strong reference image. For one consistent face or persona, you often spend a weekend curating images, captioning, training, testing, and retraining before you know whether it worked.
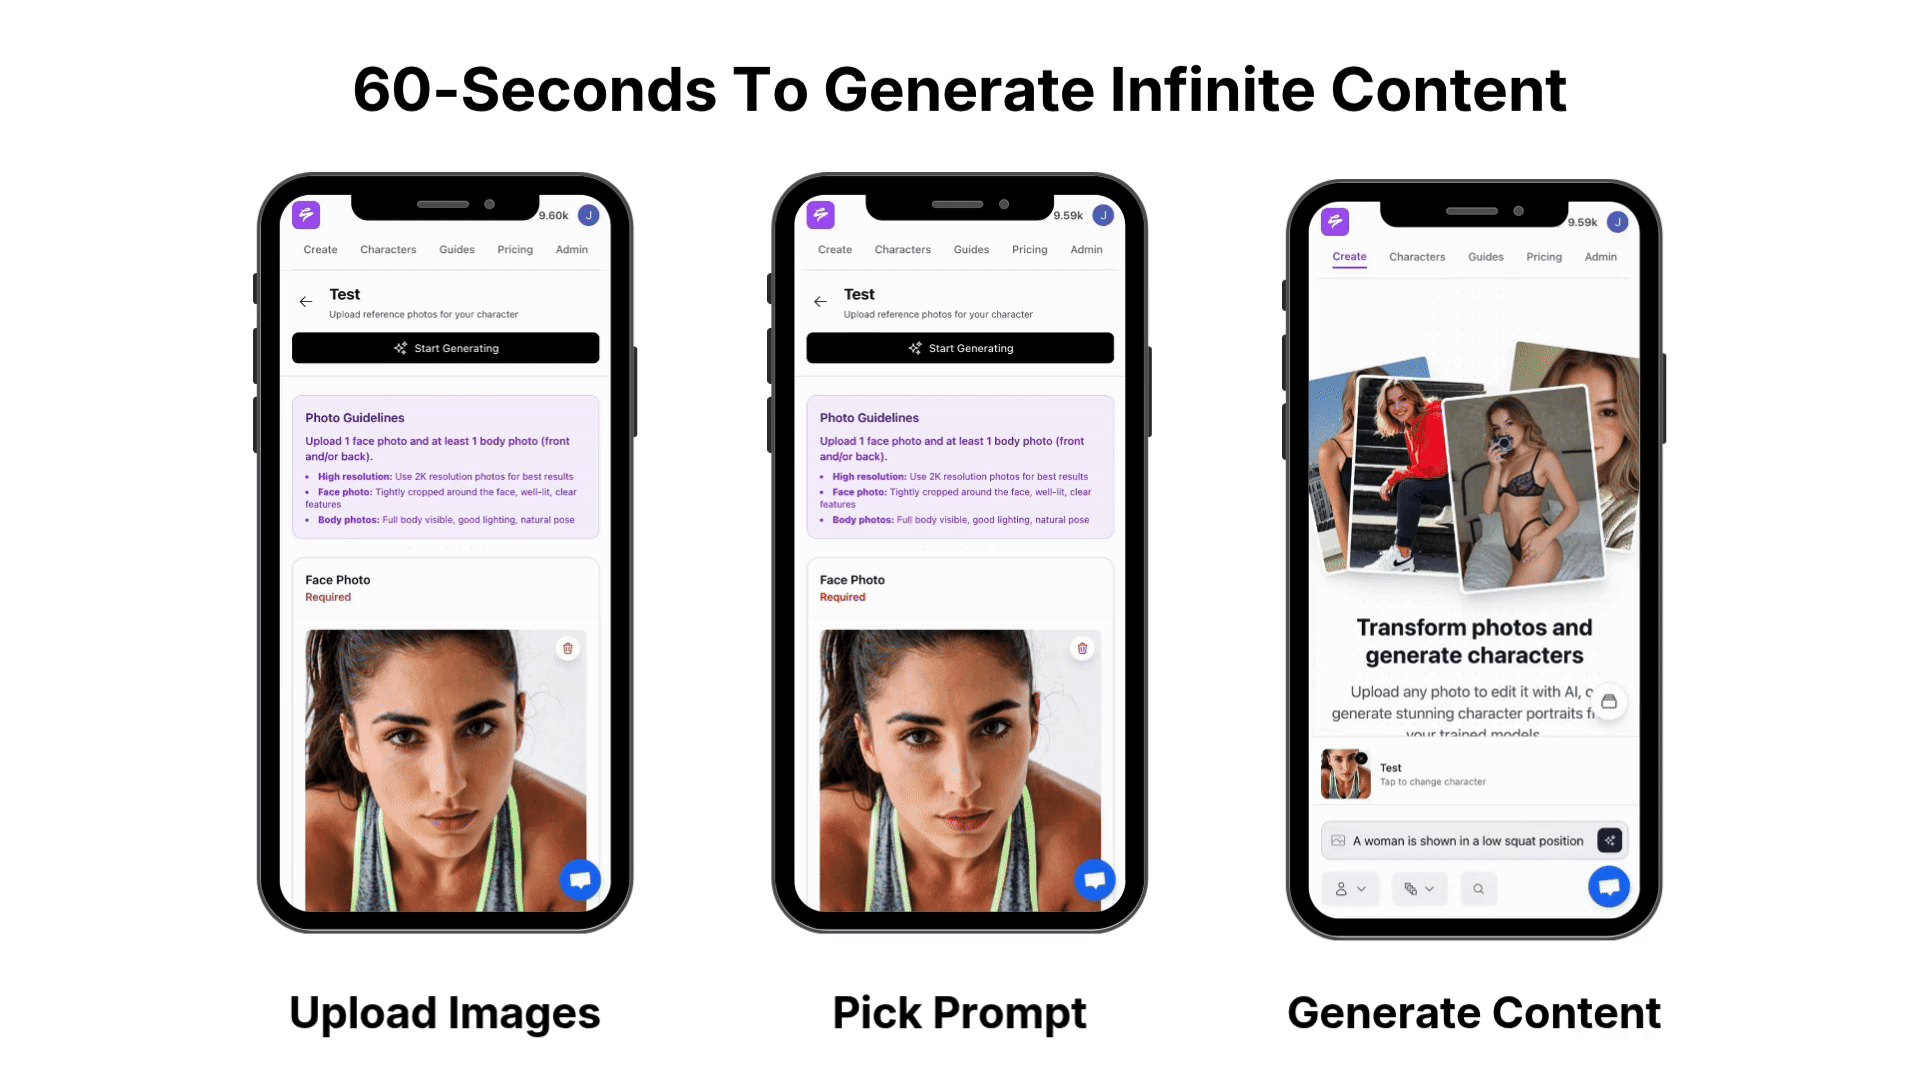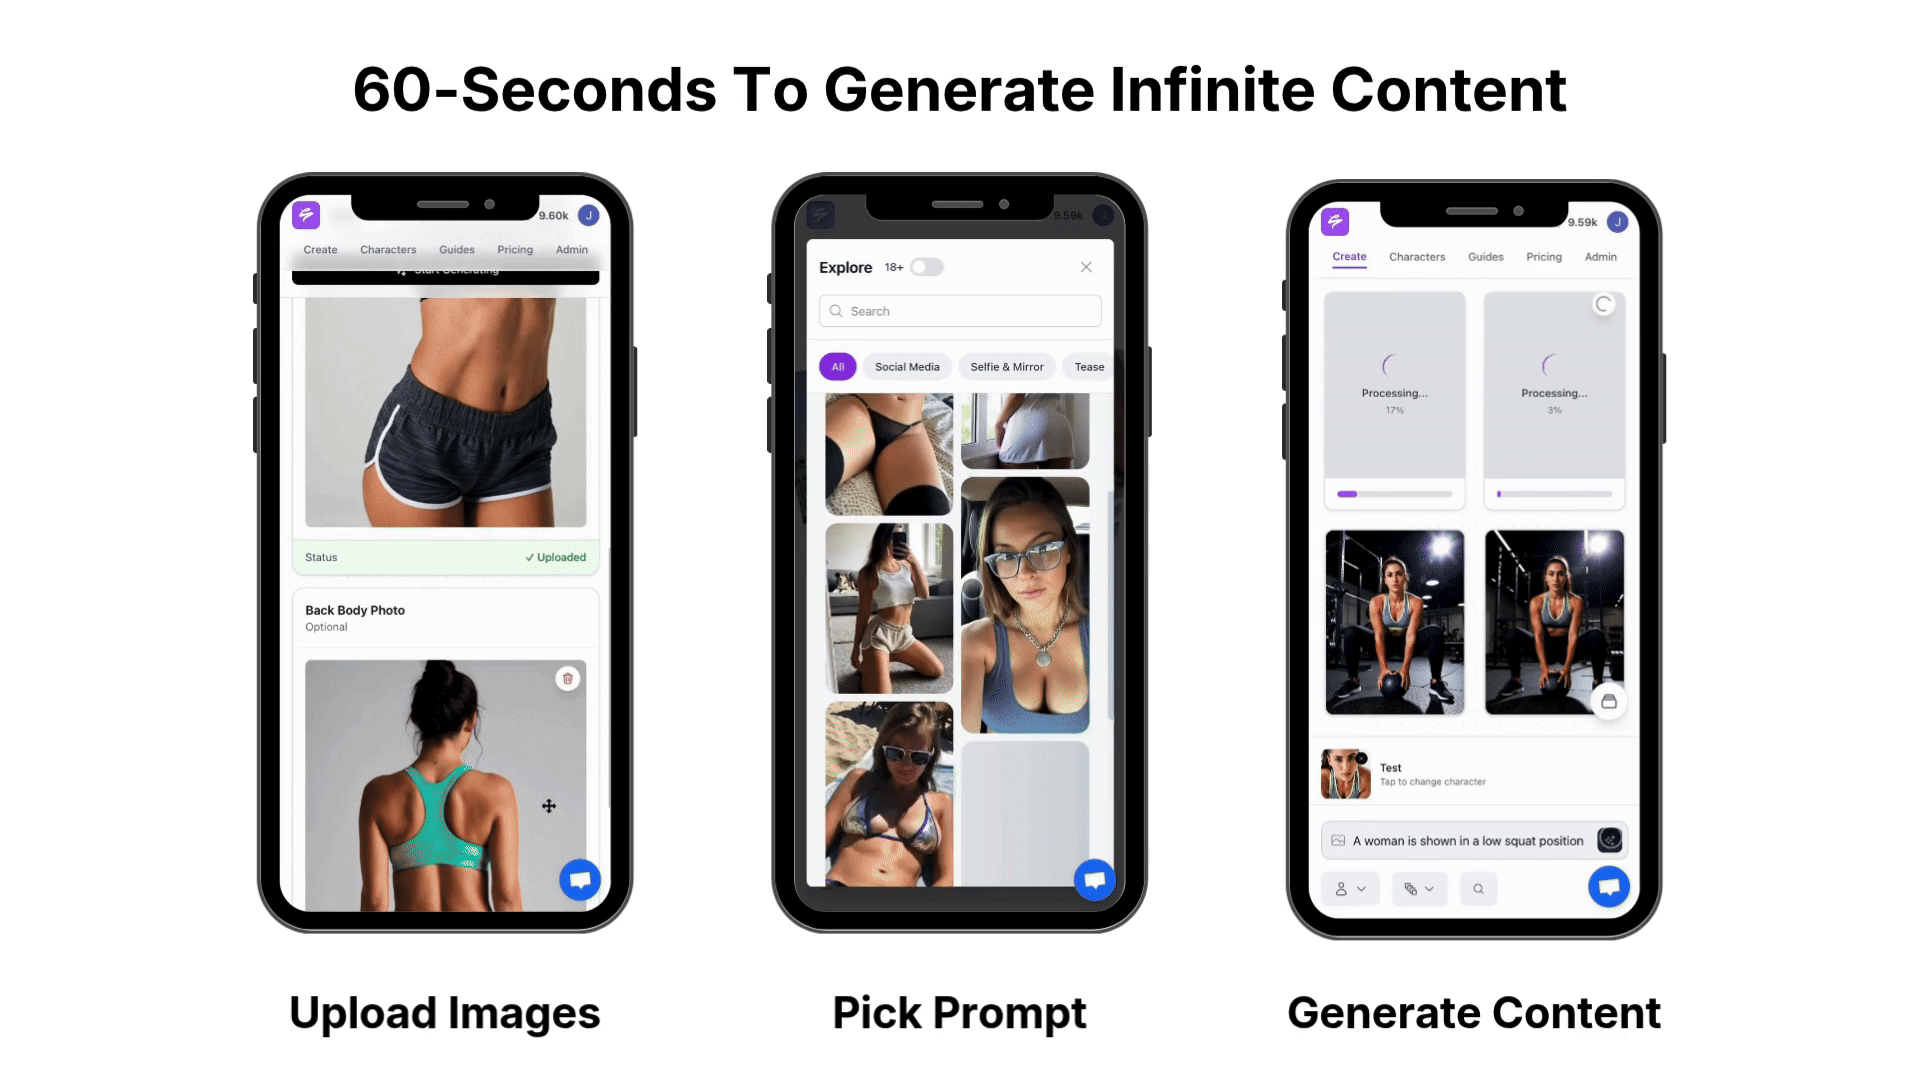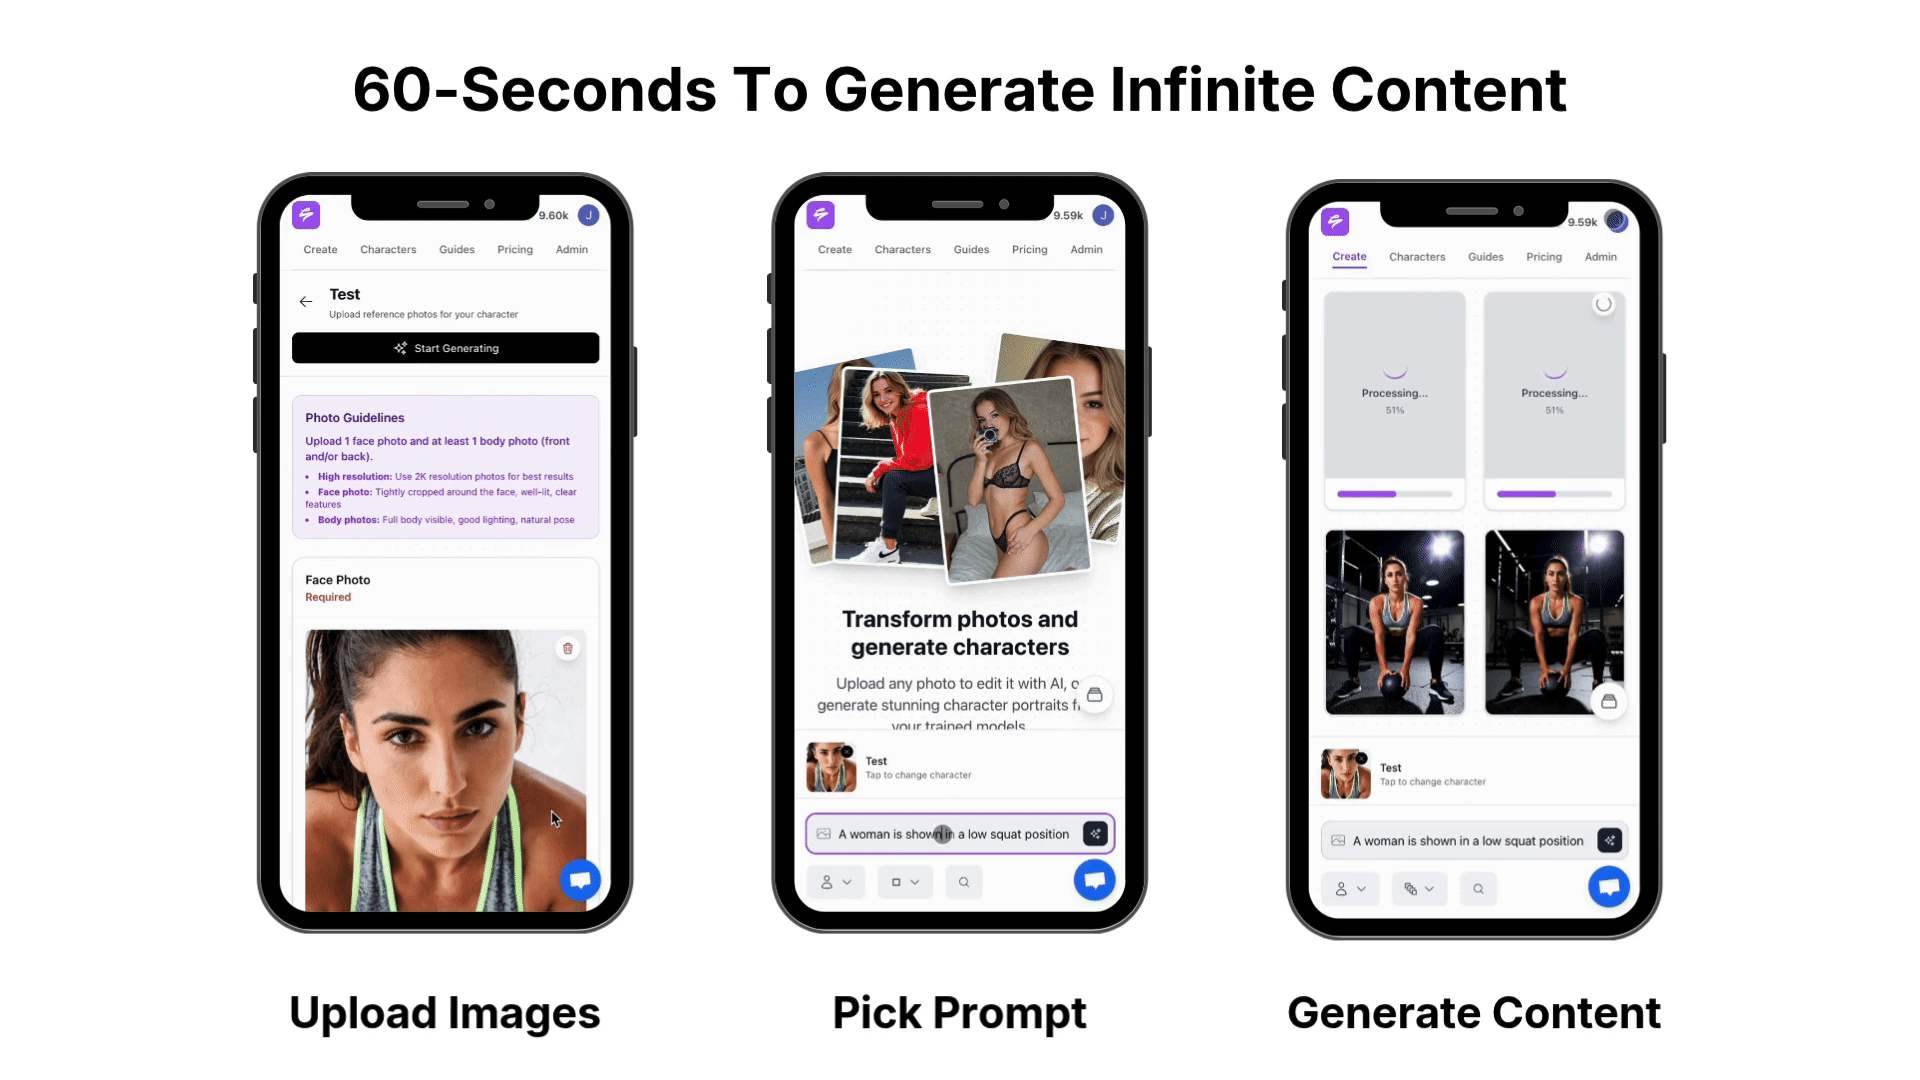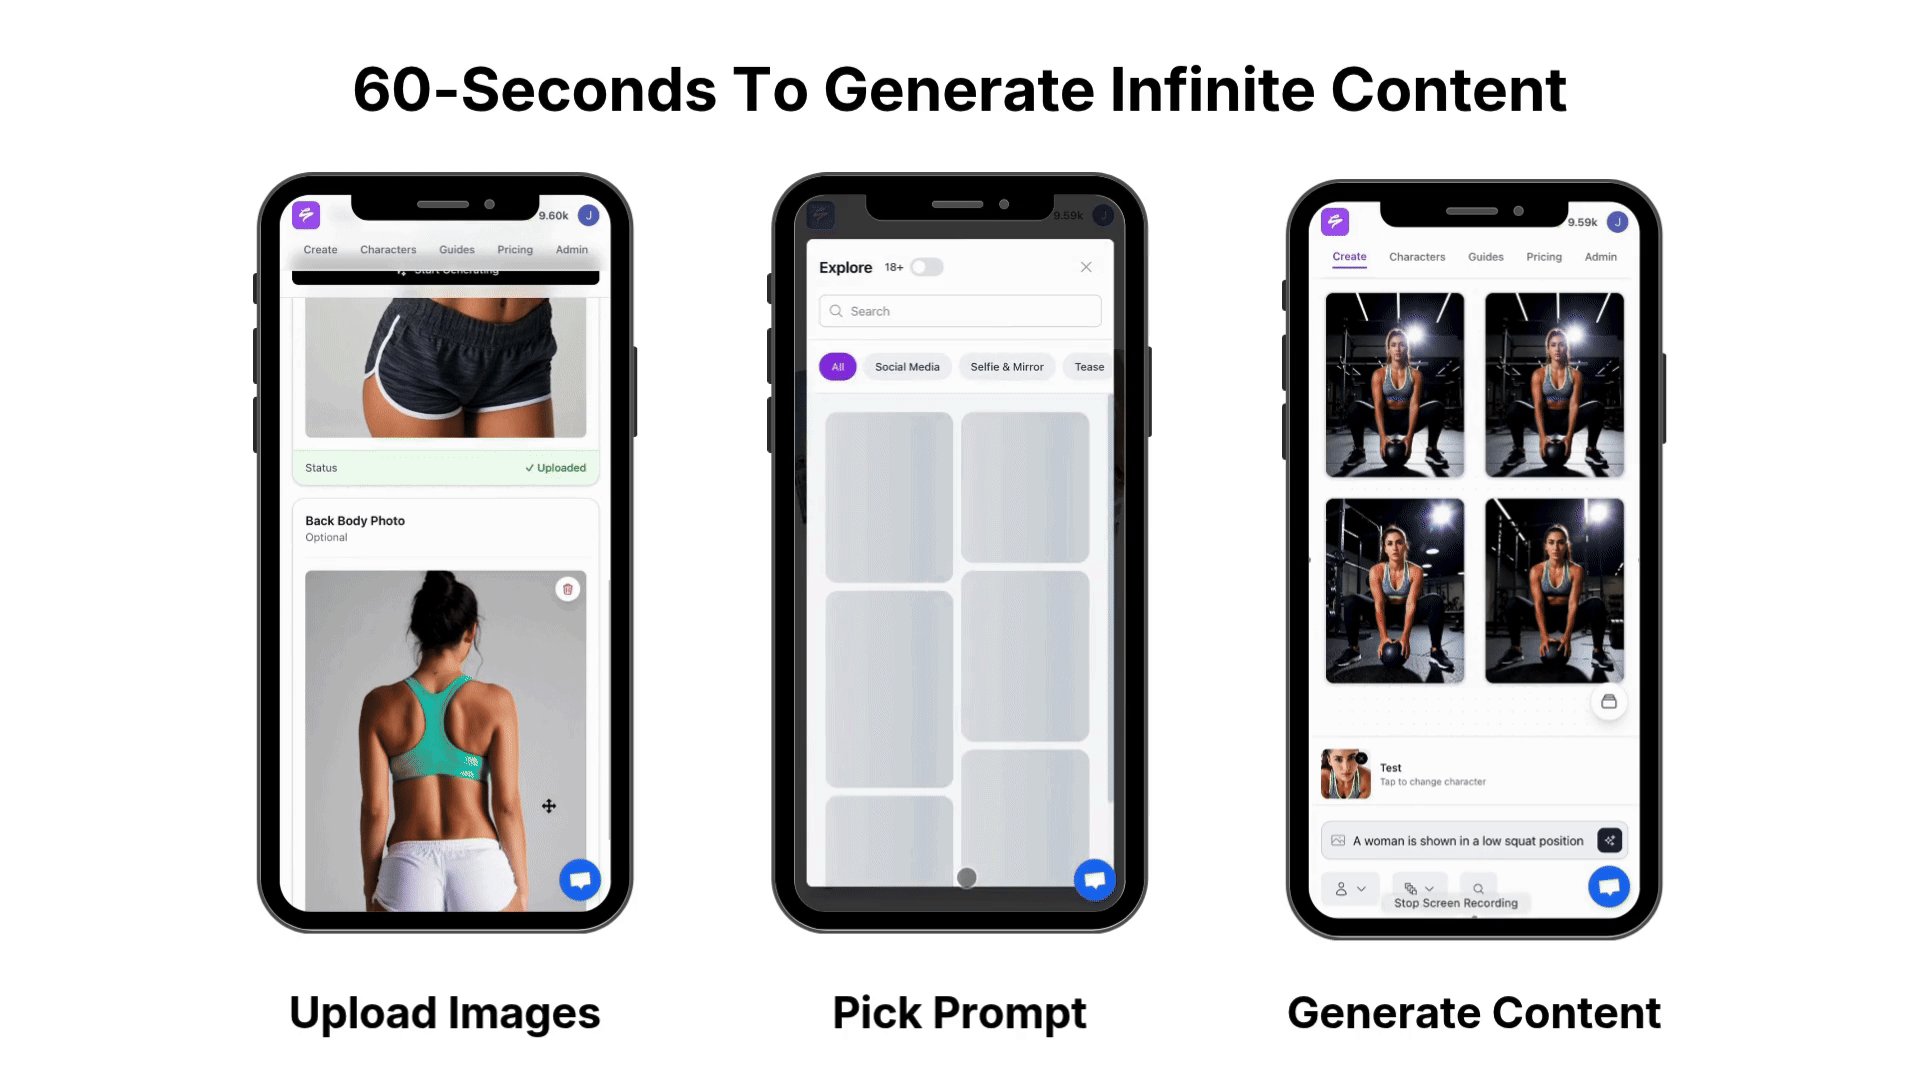
Sozee focuses on that exact use case. You upload as few as three photos, and Sozee reconstructs your likeness with hyper-realistic accuracy, with no training, no waiting, and no technical setup. You can also generate an entirely original character from scratch that stays consistent from the first frame.
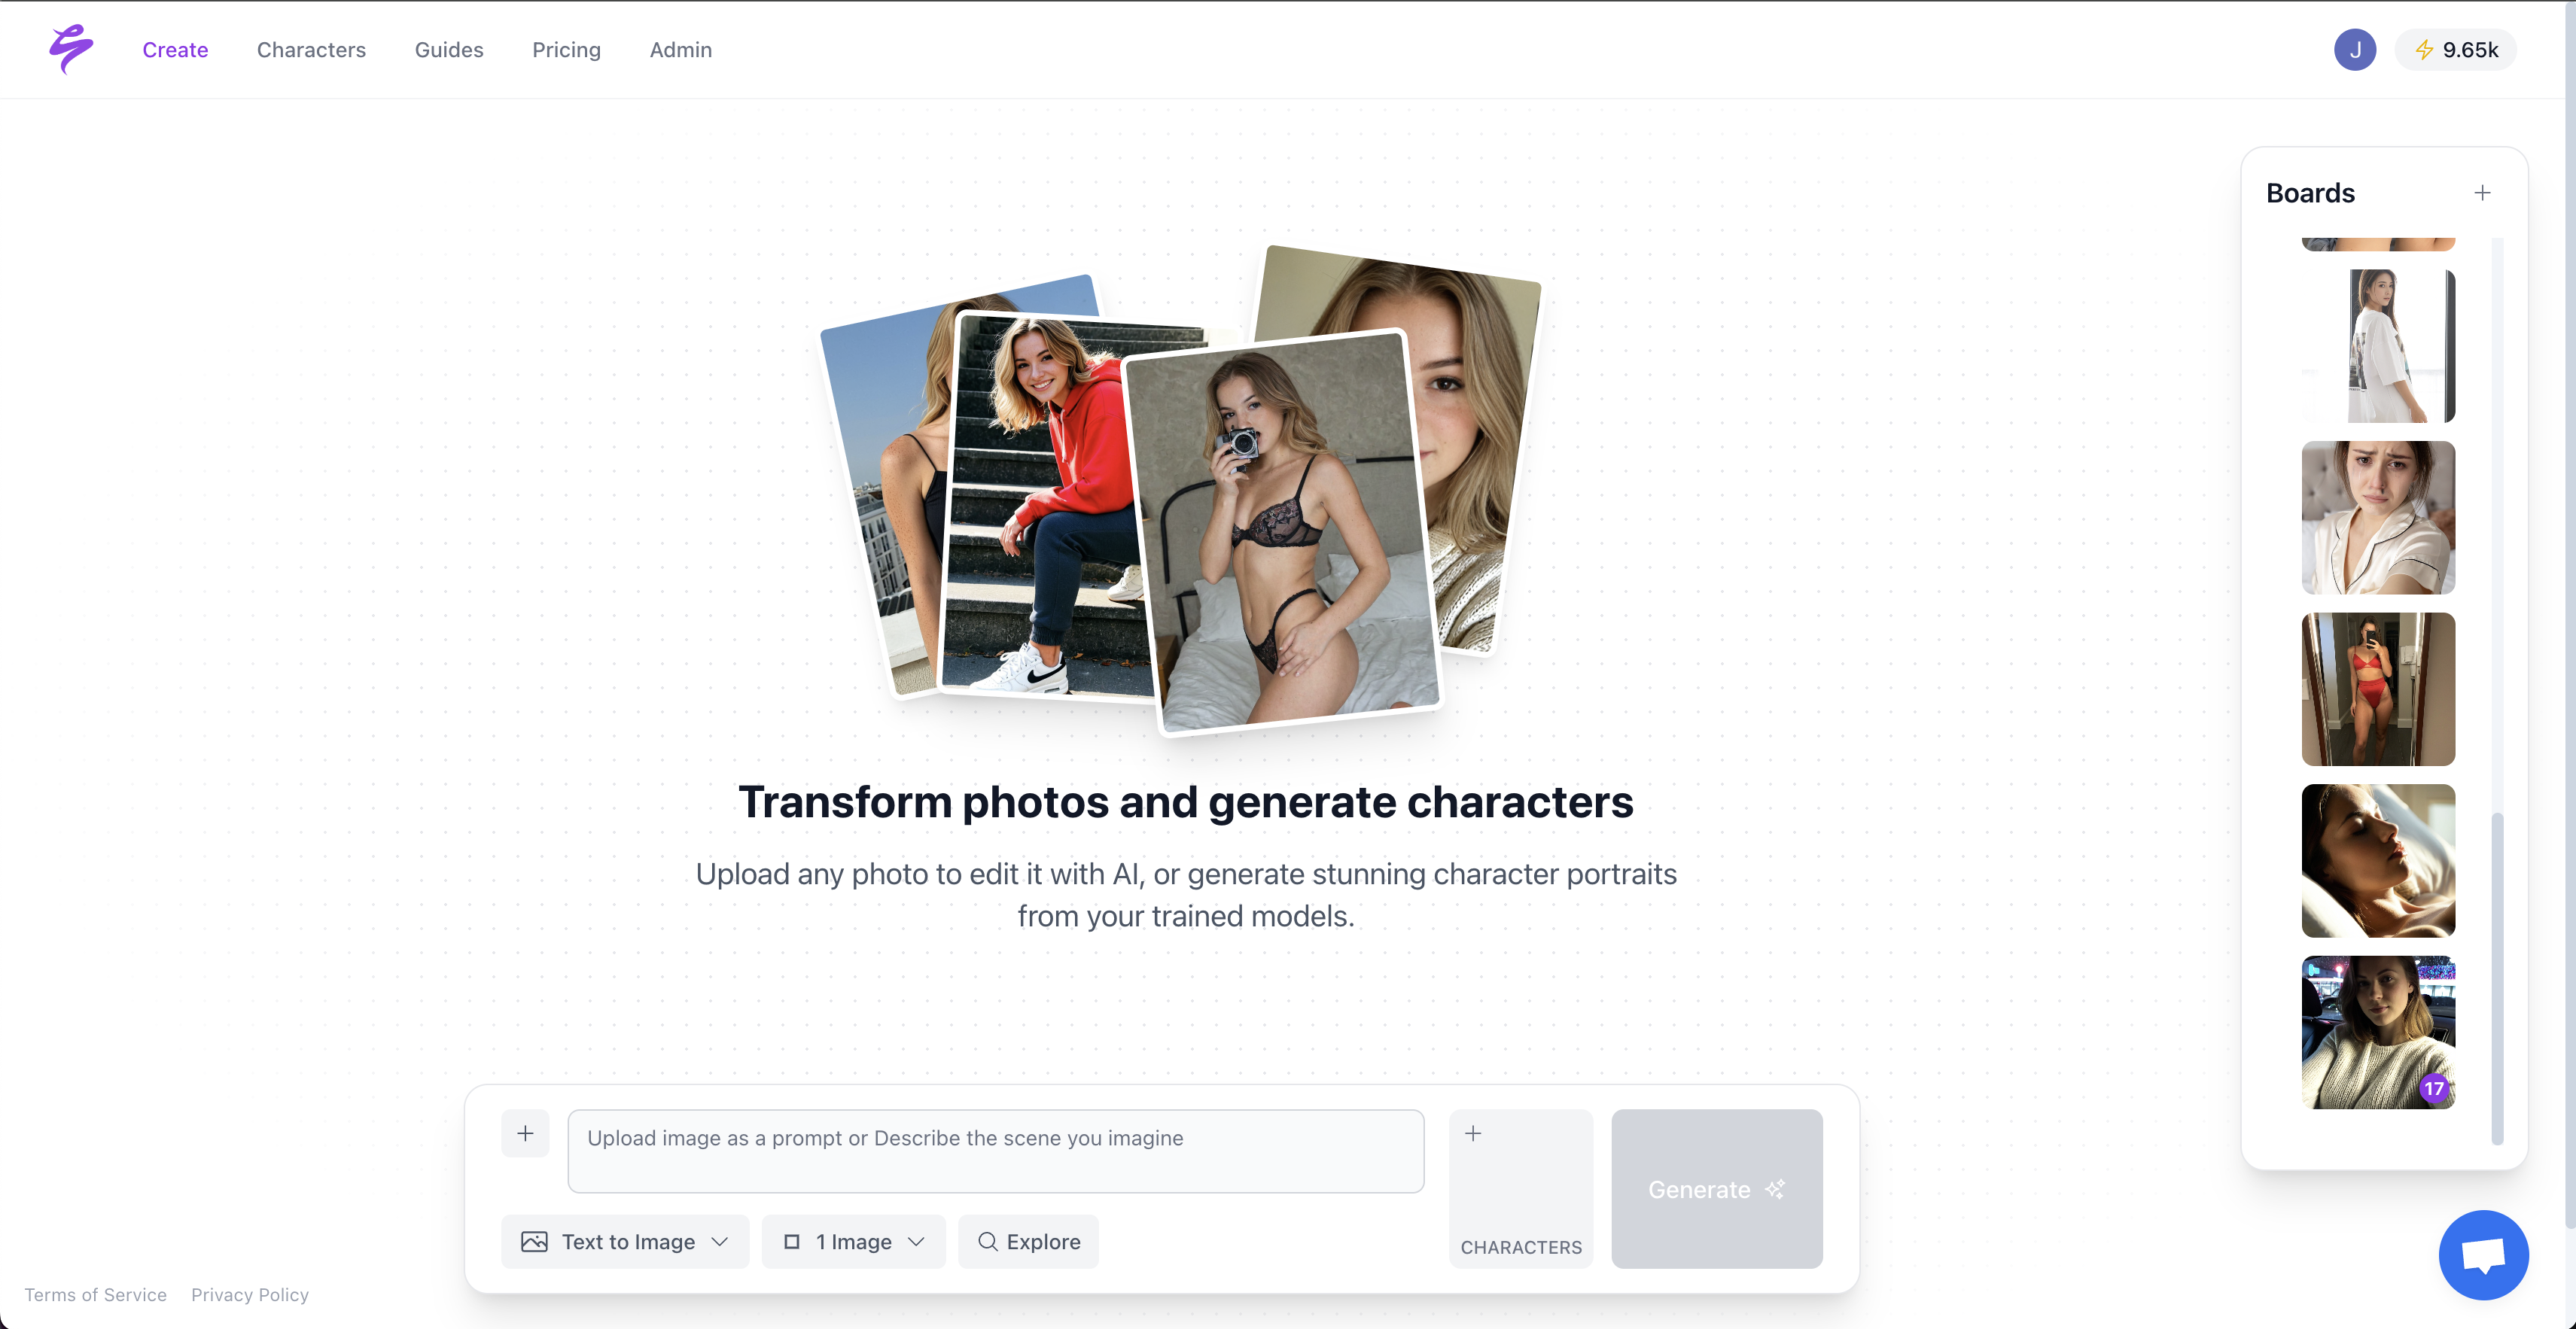
Sozee replaces a .safetensors file with a living character system:
- Likeness stays locked, with the same face and body across every frame, set, and week.
- Settings, outfits, and objects become reusable assets you own and re-attach whenever you like.
- The Agent turns a half-formed idea into a finished shoot setup through a short guided conversation, one tap away from Generate.
The key difference lies in time-to-first-image. A self-hosted LoRA takes roughly 20 minutes of training and under an hour total before you see whether it worked, while Sozee needs only three photos to start producing consistent images.
Create Your Consistent Character In Minutes
Frequently Asked Questions
This quick FAQ summarizes the most common decisions so you can revisit them without rereading the full guide.
Can I Train A LoRA Without A GPU?
Browser-based trainers such as Civitai’s on-site trainer and Tensor.Art run the full training pipeline on cloud GPUs. You upload your images, set your parameters, and receive a finished .safetensors file, with no local hardware required. Civitai’s trainer starts at around 500 Buzz, roughly $0.50, and supports SD 1.5, SDXL, FLUX, and FLUX.2 Klein. Tensor.Art includes training on its free tier for up to 100 images per run. Cloud runs typically finish in 10–45 minutes.
Is LoRA Training Free Anywhere?
Tensor.Art includes LoRA training on its free tier for up to 100 images per run, with Pro raising that to 1,000 images at $9.90 per month. On local hardware, FluxGym and AI Toolkit are free and open-source, so your only cost is electricity, provided you own an NVIDIA GPU with 12GB or more VRAM. Civitai’s on-site trainer uses paid credits and starts at around 500 Buzz, roughly $0.50, with the exact cost shown before you commit a job.
When Does It Make Sense To Skip Training?
Skip training when your main goal is one consistent face or persona rather than a reusable style or brand asset. Training a character LoRA can take about 1.3 hours to a usable checkpoint on a local RTX 5090, or 2.2 hours for a full 2,500-step run, and 15–90 minutes on other setups. The full workflow of dataset curation, captioning, training, testing, and retraining often stretches across a weekend. No-training likeness tools reach a first image in minutes from as few as three photos, with the same face locked across every frame, set, and week. LoRA training earns its cost when you need a style that generalizes across hundreds of prompts or a brand asset you will reuse at scale. For a single consistent character, the overhead rarely pays off.
Skip Training And Start Generating With Sozee